

Maximum of 25 job preferences reached.
Top Data Engineer Jobs in Washington, DC

Financial Services
Design, build, and maintain data lakes, data warehouses, and end-to-end data pipelines for a multi-tenant SaaS platform. Lead code and design reviews, write infrastructure-as-code, optimize performance and scalability, participate in data governance, mentor junior engineers, evaluate new technologies, automate tests, collaborate cross-functionally, and join on-call rotation to ensure reliable data delivery.
Top Skills:
AthenaAws CloudformationAws GlueCassandraCi/CdDynamoDBEksEmrGreenplumInfrastructure-As-CodeKafkaKinesisKubernetesLambdaMongoDBMskPostgresPythonRdsRedshiftS3SQLSQL ServerTeraform

Computer Vision • Software
Leads the migration of legacy data warehouses and pipelines to an Azure and Databricks lakehouse. Defines technical architecture, reusable Azure Data Factory and Databricks pipelines, reconciliation methods, quality gates, and performance solutions. Mentors data engineers, reviews technical work, and collaborates with product, QA, platform, and customers in a remote Agile environment.
Top Skills:
AgileSparkAzureAzure Data FactoryDatabricksDelta LakePythonSQL
Database
Build and maintain FinOps data pipelines, BigQuery and dbt models, cost attribution systems, forecasting and anomaly detection models, and cost-versus-revenue analytics. Identify and implement AWS and GCP savings opportunities, automate governance with Python, Terraform, and Lambda, and partner with Engineering, Finance, Product, and leadership on cloud costs, forecasting, reporting, and architecture decisions.
Top Skills:
AWSAws Cost And Usage ReportsAws Cost ExplorerAws LambdaBashBigQueryCloudzeroDbtGCPGcp Billing ReportsHexLinearNotionPulumiPythonSQLTerraformVantage
Healthtech • Biotech • Pharmaceutical
Designs, develops, maintains, and optimizes complex data systems, SQL/ETL processes, reporting solutions, and .NET applications supporting pharmacy benefit management. Responsibilities include database performance tuning, data warehousing, troubleshooting pharmacy claims, technical specification development, software testing, cloud integration, stakeholder collaboration, Agile participation, and mentoring. The role requires strong SQL Server, dimensional modeling, cloud database, Python, PowerShell, and healthcare data standards expertise.
Top Skills:
.NetAnsi X12AWSAws RdsAzure Sql DatabaseC#CassandraGitlabHadoopHl7JSONMicrosoft Sql ServerMongoDBNcpdpPower BIPowershellPythonRdbmsSparkSQLSsasSsisSsmsSsrsTableauVisual StudioVisualcronXML

Artificial Intelligence • Information Technology • Machine Learning • Generative AI • Big Data Analytics
Designs and optimizes scalable data platforms, architectures, and production pipelines supporting AI and machine learning. Responsibilities include Databricks Lakehouse development, batch and real-time processing, data governance, security, monitoring, performance tuning, infrastructure planning, and collaboration with DevOps, MLOps, and cross-functional teams. The role serves as the AI team’s data engineering subject matter expert and ensures reliable, secure, cost-effective data solutions.
Top Skills:
DatabricksDelta LakeDuckdbGoogle Cloud PlatformInfrastructure As CodeJSONKerasLangchainLangsmithPandasParquetPdfPostgresPysparkPythonPyTorchSQLTensorFlow

Agriculture • Industrial • Manufacturing
Designs, develops, and optimizes enterprise data pipelines and platforms using Snowflake, integrating Oracle Fusion, on-premises databases, and cloud applications. Applies data quality, governance, security, and performance practices while supporting Power BI, AI, and machine learning use cases. Partners with business and technical stakeholders, leads data migrations, translates requirements into sustainable solutions, mentors junior engineers, and guides engineering standards.
Top Skills:
Apache AirflowAzure Blob StorageAzure Data FactoryDbtOci Object StorageOracle EpmOracle ErpOracle FusionPower BIPower Bi CopilotPythonSnowflakeSnowflake CortexSQLSQL Server

AdTech • Artificial Intelligence • Gaming • Machine Learning • Software • Virtual Reality • Metaverse
Designs, builds, and evolves scalable data platform services, distributed systems, backend infrastructure, pipelines, and self-service tooling. Provides technical leadership for cross-functional initiatives, improves platform reliability and developer experience, and delivers reusable solutions supporting Unity’s advertising ecosystem and internal engineering teams.
Top Skills:
Apache FlinkApache KafkaApache PaimonSparkArgocdKubernetesTerraform

Edtech
Leads the design, development, and optimization of scalable data pipelines and analytics platforms. Builds ETL/ELT workflows using Databricks and Spark, integrates and transforms source data into curated models, manages SQL Server data, and maintains documentation and lineage. Collaborates with product, analytics, and engineering teams to deliver reliable data solutions. Applies responsible AI practices and delivers projects independently within established timelines.
Top Skills:
SparkAzureDatabricksDatabricks SqlDaxGitPower BIPysparkPythonSQLSQL Server

Information Technology • Consulting
Design, build, and optimize enterprise ETL/ELT pipelines, cloud data lakes, lakehouse solutions, data models, and semantic layers across AWS and Azure. Ensure data quality, security, performance, reliability, and governance while supporting analytics, reporting, and AI initiatives. Collaborate with product, engineering, IT, and business stakeholders to translate requirements into scalable data solutions, monitor pipeline health, troubleshoot issues, and improve data architecture and practices.
Top Skills:
AWSAws BedrockAzureAzure Data FactoryAzure DevopsAzure FabricCi/CdDatabricksDmsGitGluePower BIRagRedshiftS3SparkSQLSsis

Fintech • Software • Financial Services
Own Step’s analytics data models, transformation pipelines, metric definitions, semantic layer, and data quality practices. Partner with Product, Marketing, Engineering, Risk, Growth, and Finance to establish trustworthy data foundations and enable self-service analysis. Build reusable query, visualization, and code components; apply AI-augmented workflows; and collaborate with data scientists, analysts, and platform engineers. The role requires strong SQL, modeling, pipeline, BI, communication, and independent ownership skills, with occasional travel for team onsites.
Top Skills:
Ai ToolsBigQueryCiData Observability ToolingData PipelinesDbtLookerMixpanelPythonSemantic LayerSQLTableau

Software
Own Mux’s end-to-end data platform, including ingestion, Snowflake administration, dbt transformations, orchestration, data quality, observability, and reverse ETL. Build semantic models supporting AI agents, establish governance and reliability standards, and partner with Engineering, Finance, Product, and GTM. Use AI coding tools to develop and maintain pipelines while validating output quality. The role requires strong SQL, Python, data modeling, cloud warehouse administration, and production data engineering experience.
Top Skills:
AirbyteAWSBigQueryClaude CodeCubeCursorDatabricksDbtDbt Semantic LayerElementaryFivetranGCPHubspotKafkaKinesisLlm AgentsLookmlMcp ServersMetaplaneMetricflowMonte CarloNetSuiteOmniPythonRedisSalesforceSnowflakeSQL

Cloud • Fintech
Designs, builds, and optimizes scalable Databricks-based data platforms, pipelines, integrations, and reusable engineering tools. The role focuses on platform performance, reliability, cost efficiency, security, governance, automation, and cloud infrastructure. It collaborates with engineering, analytics, security, and other stakeholders on architecture, technical planning, production support, and continuous improvement. The position requires hands-on data engineering experience with Databricks, cloud services, Python, SQL, Spark, infrastructure-as-code, and CI/CD practices.
Top Skills:
Apache KafkaSparkAWSAzureCi/CdConfluentDatabricksDelta LakeGCPInfrastructure-As-CodePythonScalaSQL
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free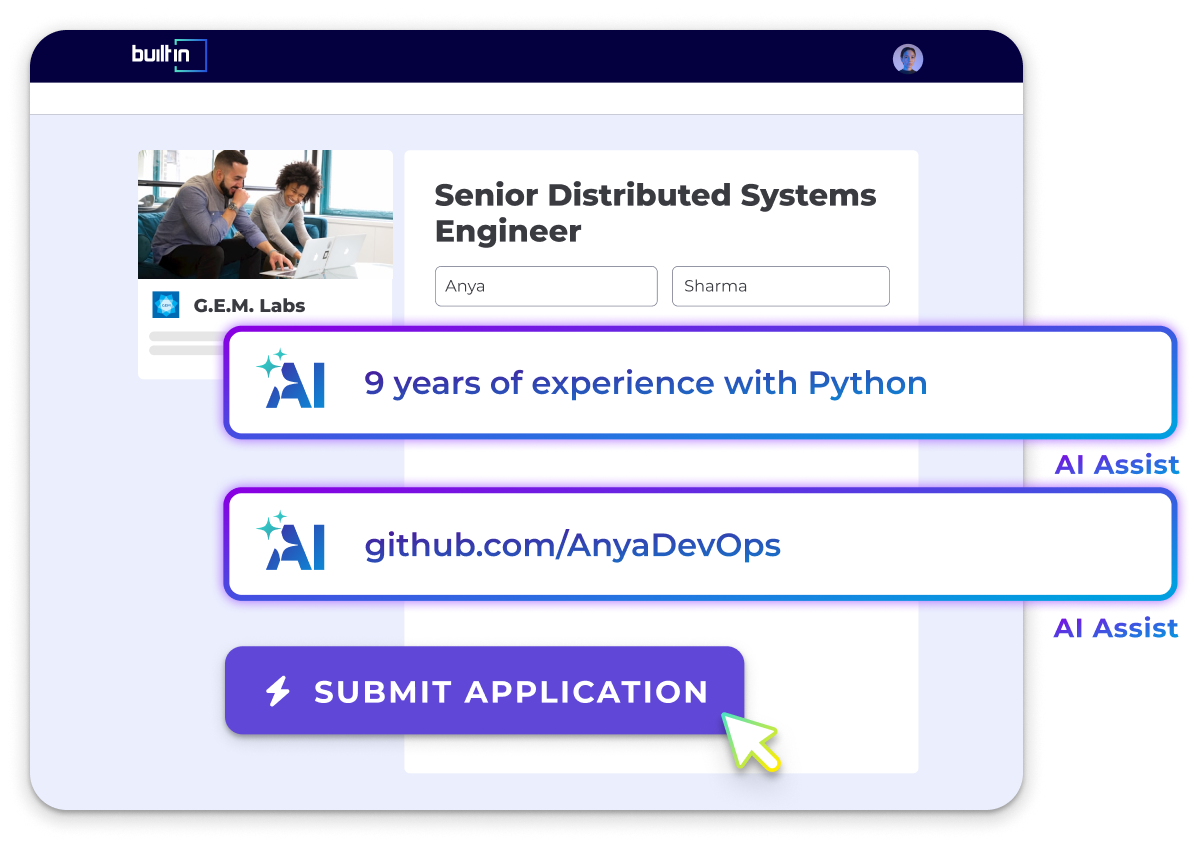

Edtech
Lead the architecture and development of Penn Foster Group’s Databricks-based cloud data platform. Build scalable batch, streaming, CDC, and API pipelines using Python, SQL, Spark, and Azure; establish engineering standards, governance, observability, and CI/CD practices; develop AI-ready semantic data products; and mentor data engineers. Partner with BI, product, security, governance, and MLOps teams to support analytics, machine learning, generative AI, and self-service reporting.
Top Skills:
Adls Gen2SparkAuto LoaderBusiness ObjectsCi/CdDatabricksDatabricks GenieDatabricks JobsDatabricks ReposDatabricks WorkflowsDbtDelta LakeDelta Live TablesGenerative AiGitGreat ExpectationsInfrastructure As CodeLakeflowLakehouse MonitoringLiquid ClusteringMedallion ArchitectureAzureMicrosoft Entra IdMlflowMlopsPhotonPower BIPysparkPythonRbacSQLSql WarehousesTableauUnity Catalog

Other
Designs and leads enterprise data pipelines and integrations across Snowflake, Oracle Fusion, on-premises databases, and cloud applications. Ensures data quality, governance, security, scalability, and performance while supporting Power BI, AI/ML, and self-service analytics. Partners with business and technical stakeholders, leads migrations, mentors engineers, optimizes data platforms, and establishes engineering best practices.
Top Skills:
Apache AirflowAzure BlobAzure Data FactoryDbtOci Object StorageOracle EpmOracle FusionPower BIPower Bi CopilotPythonSnowflakeSnowflake CortexSQLSQL Server

Big Data • HR Tech • Mobile • Software • Database
Designs, builds, deploys, and maintains scalable data pipelines, data lake systems, batch and streaming processing, MLOps frameworks, data documentation tooling, and an agentic data exploration platform. The role supports customer-facing products and enables engineering teams through reliable infrastructure, observability, data discovery, and AI capabilities.
Top Skills:
Amazon Ec2Amazon MskAmazon S3Apache AirflowApache FlinkApache IcebergApache KafkaApache ParquetSparkAWSAws GlueAws IamDelta LakeDockerKubernetesLlmsMlopsSpark Structured Streaming
Big Data • HR Tech • Mobile • Software • Database
Build and operate scalable batch and streaming data pipelines, data lake infrastructure, MLOps frameworks, data documentation systems, and an AI-assisted data exploration tool. The role focuses on reliable data ingestion, large-scale processing, workflow orchestration, observability, and infrastructure supporting customer-facing products and machine learning development.
Top Skills:
Amazon MskApache AirflowApache FlinkApache IcebergApache KafkaSparkAws Ec2Aws GlueAws IamAws S3Delta LakeDockerKubernetesParquetSpark Structured Streaming

Robotics
Build and maintain production data pipelines that transform robot logs and telemetry into reliable, queryable datasets. Design Spark-based ETL workflows, orchestrate processing with Airflow or similar tools, manage gold-layer datasets, and implement data quality, schema evolution, monitoring, and metadata practices. Collaborate with robotics, hardware, reliability, analytics, and ML teams on data modeling, fleet insights, debugging, and root-cause analysis. The role may also contribute to Python, Java, or C++ libraries supporting data capture and consumption.
Top Skills:
Apache AirflowApache IcebergSparkAvroAWSC++DagsterData Catalog SystemsData ModelingData OrchestrationData QualityDelta LakeETLJavaMedallion ArchitectureMetadata ManagementParquetPrefectPythonScalaSchema Evolution
Database
Designs and leads production-grade batch, incremental, streaming, and real-time data pipelines across Microsoft Fabric and Azure. Builds Delta Lake medallion architectures, dimensional and Data Vault models, CDC and incremental-loading solutions, CI/CD automation, governance, security, observability, and data-quality controls. Supports migrations to Fabric, prepares governed data for AI and RAG workloads, and leads client-facing engineering workstreams, estimates, risk management, mentoring, and operational handover.
Top Skills:
SparkAzure Data FactoryAzure DevopsAzure SynapseBicepData Vault 2.0Dataflows Gen2DaxDelta LakeGenaiGitGitKqlLakehouseAzureMicrosoft FabricMicrosoft PurviewOnelakePower BIPysparkPythonRagRest ApisSpark SqlSQL ServerSsasSsisT-SqlTerraform
Information Technology • Consulting • Financial Services
Develops and maintains SQL data extracts, validation rules, financial reports, and Power BI or Tableau dashboards for a federal financial management program. Produces recurring status and trend visuals, supports change and release management using JIRA, maintains SharePoint resources, ensures Section 508 accessibility and sensitive-data protection, and creates user guidance. The role also supports data quality checks, process improvement, and ad hoc reporting tasks.
Top Skills:
DaxJIRAExcelMicrosoft OutlookMicrosoft PowerpointMicrosoft ProjectMicrosoft TeamsMicrosoft WordPower BIPower QueryPythonRSharepointSQLTableau

Fitness
Own PushPress’s data platform, including ingestion, orchestration, cloud warehouse performance, governance, privacy, data quality, monitoring, and AI-ready data foundations. Build reliable pipelines integrating product, payment, and third-party data; establish data contracts, access controls, auditability, and semantic definitions; support real-time analytics and trustworthy reporting. Partner with Engineering, Data, and AI teams while maintaining infrastructure, incident response, documentation, and operational runbooks.
Top Skills:
Ai AgentsAirflowCcpaCdcCi/CdClickhouseDagsterElementaryEvent-Driven ArchitecturesFivetranGdprHevoMonte CarloPciPosthogPythonRbacRetrieval-Augmented GenerationRudderstackSegmentSemantic LayersSnowplowSQLStreamingTerraformTypescript

21 Days AgoSaved
Information Technology • Professional Services
Build and own production data infrastructure for a healthcare AI platform. Responsibilities include REST API ingestion, Azure Event Hubs streaming into Databricks, Delta Lake medallion pipelines, entity resolution, semantic metrics, data-quality instrumentation, reconciliation, schema-drift handling, and troubleshooting source-to-warehouse discrepancies. The role requires strong Python and SQL skills, independent pipeline ownership, and experience with Databricks, Spark, PySpark, streaming, and healthcare-related data is a plus.
Top Skills:
SparkAuto LoaderAzure Data FactoryAzure Data Lake StorageAzure Event HubsAzure Key VaultDatabricksDbt MetricsDelta LakeDelta Live TablesHolistics Aml/AqlKafkaKinesisLookmlPysparkPythonRest ApisSpark SqlSQLStructured Streaming

Software • Design • App development
Designs, builds, and maintains scalable batch and streaming data pipelines across AWS and GCP. Develops ETL/ELT workflows using Python, PySpark, and advanced SQL; optimizes performance, storage, and query execution; implements data quality and governance controls; and supports data lakes, warehouses, and ML workflows. Collaborates with data scientists and ML engineers on MLOps automation and production deployments while maintaining CI/CD, Docker, infrastructure standards, and technical documentation.
Top Skills:
Amazon EmrAmazon MwaaAmazon RedshiftAmazon S3AWSAws GlueBigQueryCi/CdDockerGCPGitGoogle Cloud StorageLinuxMlopsPysparkPythonSQLTerraformUnix

Artificial Intelligence • Logistics • Software • Defense
Build and operate a Kubernetes-based data platform spanning lakehouse storage, ingestion, transformation, entity resolution, lineage, and data quality. Develop batch and streaming pipelines across heterogeneous and disconnected environments, create full-stack tools for subject matter experts, and expose documented APIs for applications and AI agents. Collaborate with product, AI/ML, infrastructure, mission partners, and field teams while mentoring engineers and supporting secure, air-gapped deployments.
Top Skills:
AirflowAmazon AuroraAmazon S3Apache IcebergApache Rest CatalogArgo WorkflowsAWSAws GlueAzureCi/CdDagsterDatahubDebeziumDevsecopsDockerFips-Validated ImagesKafkaKubernetesLakefsNessieNifiOpenlineagePrestoPythonReactRest ApisSpark SqlSQLTrinoTypescriptVue

Information Technology • Professional Services • Cybersecurity • Defense
Develop and maintain data transformation pipelines, data models, dashboards, visualizations, and self-service analytics tools. Clean, validate, and analyze complex datasets; translate business needs into technical solutions and actionable insights; document workflows; and communicate findings to technical and non-technical stakeholders. The role requires Kibana expertise, strong ETL and data pipeline knowledge, collaboration skills, an active TS/SCI clearance, and Security+ certification.
Top Skills:
AWSAws GovcloudAzureCi/CdConfluenceElastic StackElasticsearchGCPGitGrafanaJIRAKibanaKubernetesLogstashNumpyPandasPower BIPythonRSQLTableau

AdTech • Automotive • Big Data • Consumer Web
Administer and enhance Edmunds’ Databricks data platform and AWS infrastructure. Build and maintain ETL pipelines, infrastructure-as-code tooling using Terraform or CDK, and operational dashboards, alerts, and reports. Collaborate with business, engineering, analytics, security, and infrastructure teams to support data platform users and AI solutions. Evaluate new technologies, troubleshoot platform issues, and improve operational, cost, and security visibility.
Top Skills:
SparkAWSAws CdkDatabricksInfrastructure As Code (Iac)PythonScalaSQLTerraform

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.






Popular Washington, DC Job Searches
Tech Jobs & Startup Jobs in Washington, DC
Remote Jobs in Washington, DC
Content Jobs in Washington, DC
Customer Success Jobs in Washington, DC
IT Jobs in Washington, DC
Cyber Security Jobs in Washington, DC
Tech Support Jobs in Washington, DC
Data & Analytics Jobs in Washington, DC
Analysis Reporting Jobs in Washington, DC
Analytics Jobs in Washington, DC
Business Intelligence Jobs in Washington, DC
Data Engineer Jobs in Washington, DC
Data Science Jobs in Washington, DC
Machine Learning Jobs in Washington, DC
Data Management Jobs in Washington, DC
UX Designer Jobs in Washington, DC
Software Engineer Jobs in Washington, DC
Android Developer Jobs in Washington, DC
C# Jobs in Washington, DC
C++ Jobs in Washington, DC
DevOps Jobs in Washington, DC
Front End Developer Jobs in Washington, DC
Golang Jobs in Washington, DC
Hardware Engineer Jobs in Washington, DC
iOS Developer Jobs in Washington, DC
Java Developer Jobs in Washington, DC
Javascript Jobs in Washington, DC
Linux Jobs in Washington, DC
Engineering Manager Jobs in Washington, DC
.NET Developer Jobs in Washington, DC
PHP Developer Jobs in Washington, DC
Python Jobs in Washington, DC
QA Jobs in Washington, DC
Ruby Jobs in Washington, DC
Salesforce Developer Jobs in Washington, DC
Scala Jobs in Washington, DC
Finance Jobs in Washington, DC
HR Jobs in Washington, DC
Internships in Washington, DC
Legal Jobs in Washington, DC
Marketing Jobs in Washington, DC
Operations Jobs in Washington, DC
Office Manager Jobs in Washington, DC
Operations Manager Jobs in Washington, DC
Product Manager Jobs in Washington, DC
Project Manager Jobs in Washington, DC
Sales Jobs in Washington, DC
Account Executive (AE) Jobs in Washington, DC
Account Manager (AM) Jobs in Washington, DC
Sales Leadership Jobs in Washington, DC
Sales Development Representative Jobs in Washington, DC
Sales Engineer Jobs in Washington, DC
Sales Operations Jobs in Washington, DC
All Filters
Total selected ()
No Results
No Results
