

Maximum of 25 job preferences reached.
Top Data Engineer Jobs in Krakow

Artificial Intelligence • Cloud • Information Technology • Software • Consulting • Data Privacy
Lead architecture and migration of data pipelines across Airflow, Spark, dbt, and BigQuery. Preserve pipeline outputs through regression testing, refactor duplicated logic, establish testing and incident-management practices, implement data-lifecycle verification, document architecture decisions, and mentor data engineers. The role requires hands-on technical leadership, pipeline migration experience, engineering-practice adoption, and collaboration across the team.
Top Skills:
AirflowAWSAzureBigQueryBigquery AeadConfig ConnectorDatabricksDbtGCPGcp KmsKafkaKubernetesPythonSnowflakeSparkTink
Artificial Intelligence • Cloud • Information Technology • Software • Consulting • Data Privacy
Build and operate production-grade Kafka-compatible streaming systems and Apache Flink applications. Develop Go services, manage event processing, state, checkpoints, schemas, and delivery guarantees, and deploy workloads on AWS and Kubernetes. Troubleshoot distributed production systems while improving reliability, scalability, performance, and resilience. Collaborate with engineers on platform evolution and apply AI-powered development tools and GenAI workflows.
Top Skills:
Apache FlinkAWSClaude CodeCursorCustom Resource Definitions (Crds)Github CopilotGoKafkaKubernetesKubernetes Operators

Software
Own and operate a business-critical data platform, developing SQL databases, data models, integrations, pipelines, and automated data quality controls. Build trusted datasets and semantic layers for Power BI reporting, maintain documentation and lineage, manage access and versioning, troubleshoot failures, and collaborate with business and technical stakeholders. Continuously improve automation, governance, performance, and reporting accuracy across sustainability and operational data use cases.
Top Skills:
Azure Blob StorageAzure Data FactoryAzure Sql DatabaseLogic AppsPower BIPythonSharepointSQL

Automotive
Develop and maintain C++ software for data logging, visualization, and processing on Linux platforms. Design and execute software tests, troubleshoot defects, prepare technical documentation, support deployed tools, and collaborate with software, hardware, and systems integration teams. The role also involves implementing standards-compliant solutions, resolving project technical issues, and continuously improving technical expertise.
Top Skills:
Asam MdfC++20C++23CanDebianEthernetLinLinuxUbuntu

Cloud • eCommerce • Software
Lead data engineering for Finance by designing dbt dimensional models, building Python or Go ETL pipelines, and loading data into BigQuery on Google Cloud. Own data quality, reconciliation, observability, documentation, and production reliability. Lead multi-sprint initiatives, partner with Finance and BI stakeholders, review code, mentor engineers, and use AI-assisted development tools responsibly. The role focuses on trusted financial reporting data, including billing, subscriptions, payments, revenue, and related metrics.
Top Skills:
BigQueryCi/CdClaude CodeCloud MonitoringDbtDockerFivetranGitGoGoogle Cloud PlatformIamKubernetesMonte CarloPythonSQLTerraform

Artificial Intelligence
Own and grow the Data Layer: build and operate ingestion, transformation, reconciliation, and serving pipelines (raw→refined→curated). Use agentic AI tools to accelerate delivery, ensure data correctness, and partner with backend, AI, and product teams to define reliable data contracts.
Top Skills:
Agentic Dev ToolsAPIsClaude CodeCloud Data WarehouseCodexCursorEltMajor Cloud PlatformMedallion/Lakehouse ArchitectureOrchestration FrameworkSQLStreaming/Event Ingestion

Artificial Intelligence • Information Technology
Build large-scale data pipelines and infrastructure for frontier AI model training. Develop data-processing models such as classifiers, quality filters, and labeling systems; design deduplication, quality scoring, labeling, and augmentation strategies; and create reliable tooling for researchers to explore and train on massive datasets. The role also evaluates how data quality and composition affect model outcomes, with web crawler experience as a bonus.
Top Skills:
Kubernetes

Software • Analytics • Financial Services • Cryptocurrency
Staff Software Engineer responsible for designing, building, and operating distributed market data systems. The role focuses on real-time blockchain data ingestion, streaming, normalization, storage, APIs, reliability, data correctness, observability, incident recovery, and production support. The engineer will lead technical decisions, mentor teammates, translate ambiguous requirements into designs, and use AI-assisted development throughout the software lifecycle.
Top Skills:
APIsBlockchain IndexingDistributed SystemsEvmGoReal-Time StreamingRustSolana

Information Technology • Consulting
Build and maintain high-performance data lakehouse infrastructure using Java and Rust. Develop reliable Apache Iceberg maintenance workflows, including compaction, snapshot expiry, manifest rewriting, and orphan file cleanup. Ensure data integrity under concurrency, retries, and failures. Maintain a Rust-based SQL query router, develop connectors, review open-source contributions, support production deployments, and participate in on-call debugging.
Top Skills:
Apache IcebergApache ParquetSparkDatafusionJavaKubernetesPostgresRustSQLTrinoTypescript

Cloud • Information Technology • Internet of Things • Professional Services • Software
Design, implement, and maintain scalable streaming and batch data pipelines using Apache Pinot, Iceberg, Flink, and Spark. Improve pipeline performance, reliability, observability, and data quality while participating in software development, testing, incident resolution, and postmortems. Collaborate with engineering, product, and data teams, use AI coding tools, and continuously develop expertise in production data systems.
Top Skills:
Apache FlinkApache IcebergApache PinotSparkCi/CdCloud EnvironmentsCodexCursorGitGithub CopilotJavaPythonScala
Artificial Intelligence • Information Technology • Analytics
Design and implement data-driven applications and end-to-end data systems for clients. Responsibilities span cloud engineering, infrastructure, data engineering, ETL, machine learning, and data science. The role involves evaluating and presenting results, applying software engineering best practices, collaborating with data scientists and stakeholders, and delivering solutions through agile, iterative development.
Top Skills:
AgileCloud TechnologiesContinuous Integration And DeliveryData ScienceETLGenerative AiJavaMachine LearningPythonRScalaVersion Control
Gaming • Esports
Build and maintain data pipelines and infrastructure for analytics, experimentation, and company metrics. Collaborate with machine learning engineers on training, quality assessment, and model release automation. Improve data delivery processes, automate manual workflows, and develop scalable data models. The role requires strong Apache Spark and Python expertise, SQL proficiency, Git experience, and familiarity with cloud data platforms and Kubernetes.
Top Skills:
SparkAWSAzureDatabricksGitKubernetesPythonSnowflakeSQL
New
Track Smarter, Apply Better.
Ditch the spreadsheets. Organize your job search with our freeApplication Tracker.
Use For Free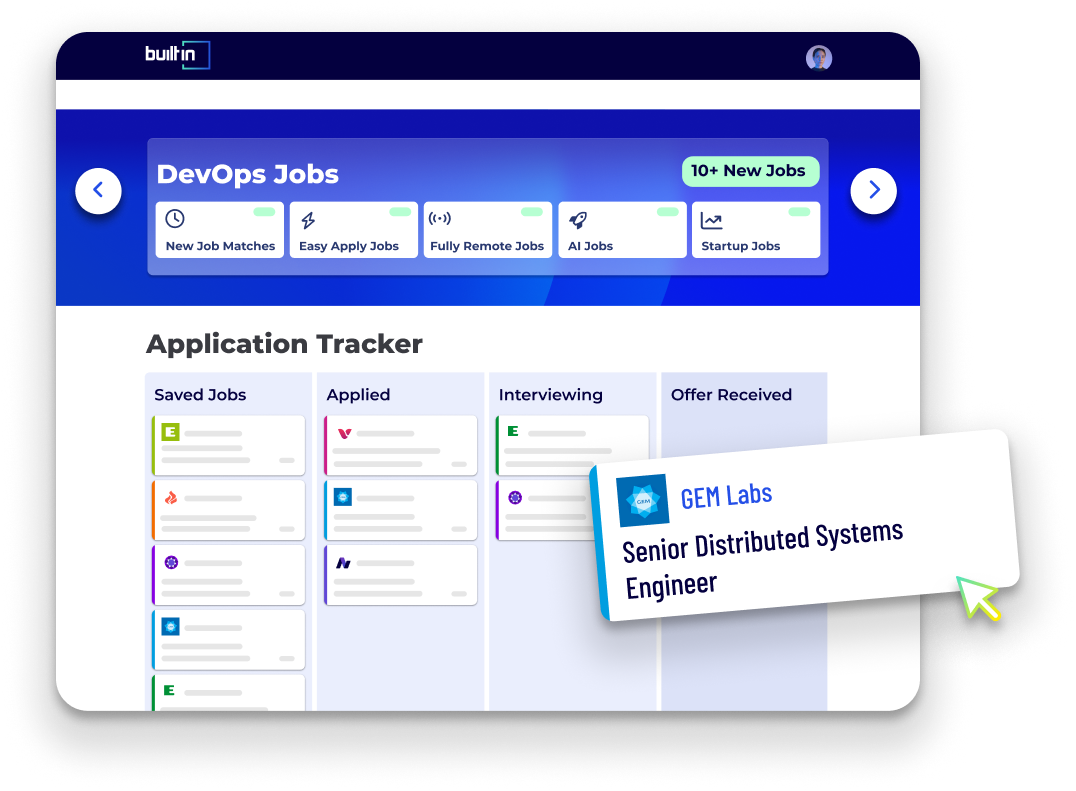
Gaming • Esports
Build and maintain data pipelines, infrastructure, data models, and automation for analytics and machine learning workflows. Collaborate with ML engineers on model training, quality assessment, and releases. Improve internal data delivery processes and enable efficient access to large-scale organizational data.
Top Skills:
SparkAWSAzureDatabricksGitKubernetesPythonSnowflakeSQL

Travel
Develop and maintain unified observability across Kubernetes, databases, Trino, Hadoop, and Apache Ozone. Build DORA metrics collection and service health dashboards, identify monitoring gaps, optimize Alertmanager rules, reduce alert fatigue, and provide centralized SRE expertise. The role requires strong Prometheus, Grafana, Alertmanager, PromQL, reliability metrics, incident analysis, and distributed-systems knowledge.
Top Skills:
AlertmanagerApache OzoneDora MetricsGoGrafanaHadoopJavaScriptKubernetesPrometheusPromqlPythonSli/Slo/SlaTrino
Artificial Intelligence • Cloud • Information Technology • Software • Consulting • Data Privacy
Design and implement scalable Databricks data pipelines, standardize and migrate legacy pipelines, develop dbt and Python transformations, onboard regional datasets, optimize performance and resource usage, and collaborate with architects and analytics teams. The role also contributes to future Data Science and MLOps foundations while supporting cloud-based data platforms and data modeling practices.
Top Skills:
AWSAzureCi/CdDatabricksDbtGCPPythonSnowflake
Artificial Intelligence • Cloud • Information Technology • Software • Consulting • Data Privacy
Design, build, test, deploy, and operate scalable Azure and Databricks data pipelines and analytical data products. Refactor pipelines for reliability, performance, observability, and maintainability; diagnose incidents; and implement SRE, DataOps, CI/CD, testing, monitoring, governance, and security practices. Collaborate with data, architecture, product, and engineering teams to onboard workloads, translate reporting needs into technical solutions, document data flows, and share engineering practices.
Top Skills:
DatabricksAzurePythonSQL

Gaming • Software
Build end-to-end data applications, APIs, internal tools, and user interfaces using AI-assisted development. Work across Python backends, React frontends, data models, Databricks, dbt, pipelines, cloud infrastructure, testing, security, and performance. Review AI-generated code, establish guardrails, improve engineering workflows, and help shape application architecture and technical direction.
Top Skills:
AWSCi/CdClaude CodeCodexCursorDatabricksDbtDockerFastapiKubernetesMcpMySQLNext.JsPostgresPythonReactSparkSparksqlSQLTypescript

Marketing Tech • Software
Build and operate resilient, large-scale backend and data collection systems managing 400M+ creator profiles and billions of data points. Design distributed services that handle API instability, rate limits, outages, and partial failures; optimize collection economics; and own architecture, implementation, deployment, observability, and production operations. Collaborate with data and product teams to improve freshness, reliability, coverage, and system performance.
Top Skills:
Amazon CloudwatchAmazon S3AthenaAurora LimitlessAWSCursorCustom Routing LayersEcsGitLinearNode.jsNotionPostgresProxy NetworksPulumiSlackSqsTypescript

Information Technology • Software • Consulting
Design and deliver cloud-native data platforms, scalable big data pipelines, lakehouses, warehouses, transformation frameworks, BI solutions, and ML-enabled data workflows. Lead client-facing pre-sales engagements, technical workshops, proof-of-concepts, executive conversations, and enterprise data modernization initiatives. Build reusable architectural IP, influence senior stakeholders, and translate ambiguous business challenges into production-ready solutions using AWS and modern data technologies.
Top Skills:
Amazon AthenaAmazon BedrockAmazon EmrAmazon KinesisAmazon QuicksightAmazon RedshiftApache AirflowApache HadoopApache HudiApache IcebergApache KafkaAWSAws GlueAws Lake FormationCi/CdCollibraDatabricksDbtDelta LakeGitGlue CatalogHdfsHiveLookerMlflowPower BIPysparkPythonSagemakerScalaSnowflakeSparkSQLTableauUnity CatalogWeights & BiasesYarn

Information Technology • Software • Business Intelligence
Develop and maintain scalable AWS data engineering platforms and reusable Python modules. Build object-oriented data processing solutions, debug pipelines across Step Functions, Glue, Athena, and Lambda, and apply modern engineering practices including testing, CI/CD, and version control. Collaborate with agile teams to deliver reliable solutions across countries and business environments.
Top Skills:
Amazon AthenaAutomated TestingAWSAws GlueAws LambdaAws Step FunctionsAzure DevopsCi/CdDynamoDBGitPandasPython
Information Technology • Software • Business Intelligence
Design and implement Azure-based data processing systems, scalable data pipelines, data warehouses, data lakes, and ETL workflows. Transform and optimize structured and unstructured data, tune queries, improve storage and retrieval performance, and resolve system bottlenecks. Collaborate with data scientists, analysts, and stakeholders to deliver technical solutions while working within Agile methodologies.
Top Skills:
AgileAzureAzure DevopsDatabricksJIRAPysparkPythonSQL
Cloud • Security • Software • Cybersecurity
As a Principal Big Data Engineer, you will design scalable solutions, develop data pipelines, create features, and collaborate with various teams to enhance Akamai's data platform.
Top Skills:
AkkaDeltaFlinkIcebergJavaKafkaMicroservicesMongodbPostgresPythonRabbitMQRedisScalaSparkSqs
Information Technology • Software • Business Intelligence
Designs, builds, and supports GCP data ecosystems, including cloud storage, processing, warehouses, data lakes, pipelines, and integrations. Responsibilities include requirements gathering, data modeling, performance optimization, troubleshooting, monitoring, root cause analysis, and client collaboration. The role also mentors junior data engineers and contributes to ETL/ELT, orchestration, transformation, and database management initiatives.
Top Skills:
AlteryxApache AirflowSparkBigQueryCloud FunctionsCloud StorageConfluenceDatabricksDataformDbtGitGoogle Cloud PlatformJIRALookerAzureNoSQLPower BIPythonSQLTableauTalend
One Month AgoSaved
Cloud • Information Technology • Internet of Things • Professional Services • Software
Develop and maintain Python-based Splunk services and add-ons for large-scale, real-time data ingestion and processing. Participate in requirements, design, development, testing, automation, deployment, code reviews, troubleshooting, and on-call support. Build cloud-based backend solutions using AWS, Azure, or GCP, with LLMs, Generative AI, agentic architecture, and RAG. Improve system reliability, diagnose production issues, and create maintainable, documented software.
Top Skills:
Agentic ArchitectureAWSAzureCi/CdFastapiGCPGenerative AiLarge Language Models (Llms)NoSQLPythonRetrieval-Augmented Generation (Rag)SQLTest Automation

Fintech • Payments
Design, build, and maintain AWS-based lakehouse solutions and medallion architecture using Iceberg and Glue. Implement CDC and streaming ingestion with Debezium and Kafka. Develop PySpark batch/distributed jobs on EMR/Glue, orchestrate workflows with Airflow, ensure data quality/governance, and collaborate on infrastructure and IaC practices to deliver reliable business-ready datasets.
Top Skills:
AirbyteApache AirflowApache IcebergAws EmrAws Glue CatalogAws Glue JobsAws IamAws S3DagsterDebeziumDelta LakeKafkaMariadbMySQLPostgresPysparkPythonShell ScriptingSQLUnix/Linux

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.






Popular Job Searches
Tech Jobs & Startup Jobs in Poland
Software Engineer Jobs in Poland
Data Science Jobs in Poland
Machine Learning Jobs in Poland
Artificial Intelligence Jobs in Poland
Product Manager Jobs in Poland
Front End Developer Jobs in Poland
QA Engineer Jobs in Poland
Cybersecurity Jobs in Poland
IT Jobs in Poland
Data Engineer Jobs in Poland
Data Analyst Jobs in Poland
UX Designer Jobs in Poland
Graphic Designer Jobs in Poland
Finance Jobs in Poland
HR Jobs in Poland
Marketing Jobs in Poland
Operations Manager Jobs in Poland
Project Manager Jobs in Poland
Sales Jobs in Poland
Tech Jobs & Startup Jobs in Krakow
Software Engineer Jobs in Krakow
Data Science Jobs in Krakow
Machine Learning Jobs in Krakow
Artificial Intelligence Jobs in Krakow
Product Manager Jobs in Krakow
Front End Developer Jobs in Krakow
QA Engineer Jobs in Krakow
Cybersecurity Jobs in Krakow
IT Jobs in Krakow
Data Engineer Jobs in Krakow
Data Analyst Jobs in Krakow
UX Designer Jobs in Krakow
Graphic Designer Jobs in Krakow
Finance Jobs in Krakow
HR Jobs in Krakow
Marketing Jobs in Krakow
Operations Manager Jobs in Krakow
Project Manager Jobs in Krakow
Sales Jobs in Krakow
Tech Jobs & Startup Jobs in Warsaw
Software Engineer Jobs in Warsaw
Data Science Jobs in Warsaw
Machine Learning Jobs in Warsaw
Artificial Intelligence Jobs in Warsaw
Product Manager Jobs in Warsaw
Front End Developer Jobs in Warsaw
QA Engineer Jobs in Warsaw
Cybersecurity Jobs in Warsaw
IT Jobs in Warsaw
Data Engineer Jobs in Warsaw
Data Analyst Jobs in Warsaw
UX Designer Jobs in Warsaw
Graphic Designer Jobs in Warsaw
Finance Jobs in Warsaw
HR Jobs in Warsaw
Marketing Jobs in Warsaw
Operations Manager Jobs in Warsaw
Project Manager Jobs in Warsaw
Sales Jobs in Warsaw
Remote Jobs in Poland
Remote Jobs in Warsaw
Remote Jobs in Krakow
All Filters
Total selected ()
No Results
No Results
