

Maximum of 25 job preferences reached.
Top Site Reliability Engineer Jobs

Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Design, build, and operate global, multi-cloud HPC service platforms. Own IaC-driven provisioning, reliability, observability, capacity planning, incident response, and automation to ensure high uptime and QoS for internal customers.
Top Skills:
AiopsAWSCi/CdContainer ManagementGCPGoInfrastructure As CodeKubernetesLog CollectionLsfMetricsMonitoringObservabilityOciPerlPythonRubySlurm
eCommerce • Fashion • Mobile • Software
Lead Nordstrom’s enterprise platform and SRE technical direction across cloud infrastructure, CI/CD, reliability, security, and multi-region architecture. Establish long-term architecture and engineering standards, improve autonomous deployment and runtime scaling, drive resilience and observability practices, guide major incident response, and influence teams without direct authority. Mentor senior engineers, resolve cross-team technical challenges, evaluate emerging technologies, and balance reliability investments with business value.
Top Skills:
Active-Active ArchitectureActive-Passive FailoverAi OperationsArtifact AttestationArtifact SigningAutomated RemediationBuild ProvenanceCanary AnalysisCapacity ForecastingCell-Based ArchitectureChaos EngineeringCi/CdCloud PlatformsContainerizationDeployment Policy EnforcementError BudgetsImmutable ArtifactsIncident CommandKubernetesLoad TestingMulti-Region ArchitectureObservabilityProgressive DeliveryService MeshSlosSoftware Supply Chain SecuritySre

Fintech • Payments
Develop and maintain reliable platforms through automation, observability, incident response, performance optimization, and infrastructure improvements. The role collaborates with engineering teams, supports 24x7 reliability rotations, troubleshoots complex issues across code and infrastructure, and improves operational processes. Required experience includes SRE or equivalent work, software development, cloud platforms, monitoring, databases, and containerization. Preferred skills include Terraform, REST APIs, Grafana, Splunk, Agile, and GitOps.
Top Skills:
AWSAzureC#DockerGCPGitopsGoGrafanaJavaKubernetesNoSQLPythonRdbmsRest ApisSplunkTerraform

Artificial Intelligence
Develop and maintain reliable infrastructure and software platforms across engineering teams. Manage AWS accounts and networking, Kubernetes clusters, observability and monitoring tools, and CI/CD systems. Write and improve code, support production workloads, participate in on-call operations, estimate work, collaborate across teams, and drive reliability, performance, and continuous improvement.
Top Skills:
ArgocdAWSCi/CdCoralogixDockerGithub ActionsJavaScriptKubernetesPythonSentryTerraformUnix Shell
Artificial Intelligence
Build and maintain reliable infrastructure and software platforms across engineering teams. Responsibilities include managing AWS accounts and networking, Kubernetes clusters, observability and monitoring tools, and CI/CD systems. The role involves writing and improving code, supporting production workloads, collaborating across teams, estimating work, participating in on-call rotations, and continuously improving system reliability, performance, and deployment processes.
Top Skills:
Argo CdAWSCi/CdCoralogixDockerGithub ActionsJavaScriptKubernetesPythonSentryTerraformUnix Shell
Fitness • Healthtech • Software
Own reliability and security of CI/CD and production services: define SLI/SLOs, lead incident response and postmortems, build observability (Datadog), operate Kubernetes and IaC (Terraform), harden pipelines with SAST/DAST/SCA and policy-as-code, and coach teams on reliability and operational best practices.
Top Skills:
AWSCi/CdConftestDastDatadogDockerGithub ActionsGoInfrastructure As CodeKubernetesKyvernoOpa/RegoPythonSastScaTerraformTypescript
eCommerce • Fintech • Logistics • Software • Transportation • Big Data Analytics
Contribute to designing, operating, and scaling reliable distributed systems within DAT’s SRE platform team. Responsibilities include troubleshooting incidents, implementing monitoring and automation, capacity planning, performance tuning, infrastructure-as-code, cloud migration, reliability initiatives, and on-call support. The role collaborates with software engineers and architects, promotes SRE best practices, and helps modernize legacy systems using cloud platforms and infrastructure tooling.
Top Skills:
ArgocdAutomationAWSC++Cloud InfrastructureDatadogDistributed SystemsGithub ActionsGoInfrastructure As CodeJavaJavaScriptKotlinKubernetesMonitoringObservabilityPythonTerraform
Aerospace • Other
Deploys, operates, scales, and maintains compute, storage, and networking infrastructure supporting SpaceX manufacturing systems. Responsibilities include infrastructure as code, observability, capacity planning, lifecycle management, incident response, postmortems, reliability engineering, user support, and cross-site collaboration. The role is onsite, participates in on-call rotations, requires travel to manufacturing sites, and supports mission-critical production environments.
Top Skills:
AnsibleClickhouseDockerKubernetesKvmLinuxPostgresPuppetPythonQemuTerraformVsphere

eCommerce • Legal Tech • Professional Services • Software • Data Privacy
The Site Reliability Engineer will ensure systems run smoothly, work with automation tools, resolve issues, and drive operational improvements.
Top Skills:
AWSAzureCloudFormationDockerGCPGrafanaKubernetesMemcachedNew RelicOpentelemetryPostgresPrometheusPulumiRedisSentryTerraform
Legal Tech • Software
Design and improve observability (monitoring, logging, tracing, SLIs/SLOs), build automation and CI/CD, lead incident response and reliability improvements, mentor SREs, run on-call, and apply AI/ML to operational signals to forecast and reduce risks.
Top Skills:
AWSBashCi/CdDistributed TracingGoInfrastructure As CodeKubernetesLoggingMonitoringPythonSlisSlos
Consulting • Quantitative Trading
Build and operate a reliable, scalable internal Agentic AI platform. Define SLOs, error budgets, observability standards, incident response runbooks, and reliability practices. Develop automation and Python applications, integrate APIs and asynchronous systems, manage cloud and Kubernetes deployments, and support users during incidents. Work with databases, CI/CD pipelines, AI agents, and RAG workflows while improving code quality, developer processes, platform performance, availability, accuracy, and cost efficiency.
Top Skills:
Ai AgentsAmazon OpensearchAmazon S3Asynchronous ArchitectureAWSCi/CdDatadogDynamoDBElasticsearchEvent-Driven ArchitectureGithub ActionsKubernetesMcp ServersMySQLPostgresPythonRest ApisRetrieval-Augmented Generation (Rag)
Fintech • Real Estate • Software
Lead reliability and observability efforts across the org: design and maintain Kubernetes and AWS infrastructure, build CI/CD pipelines, drive IaC standards (Terraform/Crossplane), partner with 16+ teams to roll out tools and processes, participate in on-call rotation and incident response, and use AI tools to accelerate work.
Top Skills:
Ai ToolsArgoAurora PostgresAWSCi/Cd PipelinesCrossplaneDatadogDocumentdb (Mongo)EcsEksGithub ActionsHelmKubernetesMongoDBPostgresRdsTerraform
New
Track Smarter, Apply Better.
Ditch the spreadsheets. Organize your job search with our freeApplication Tracker.
Use For Free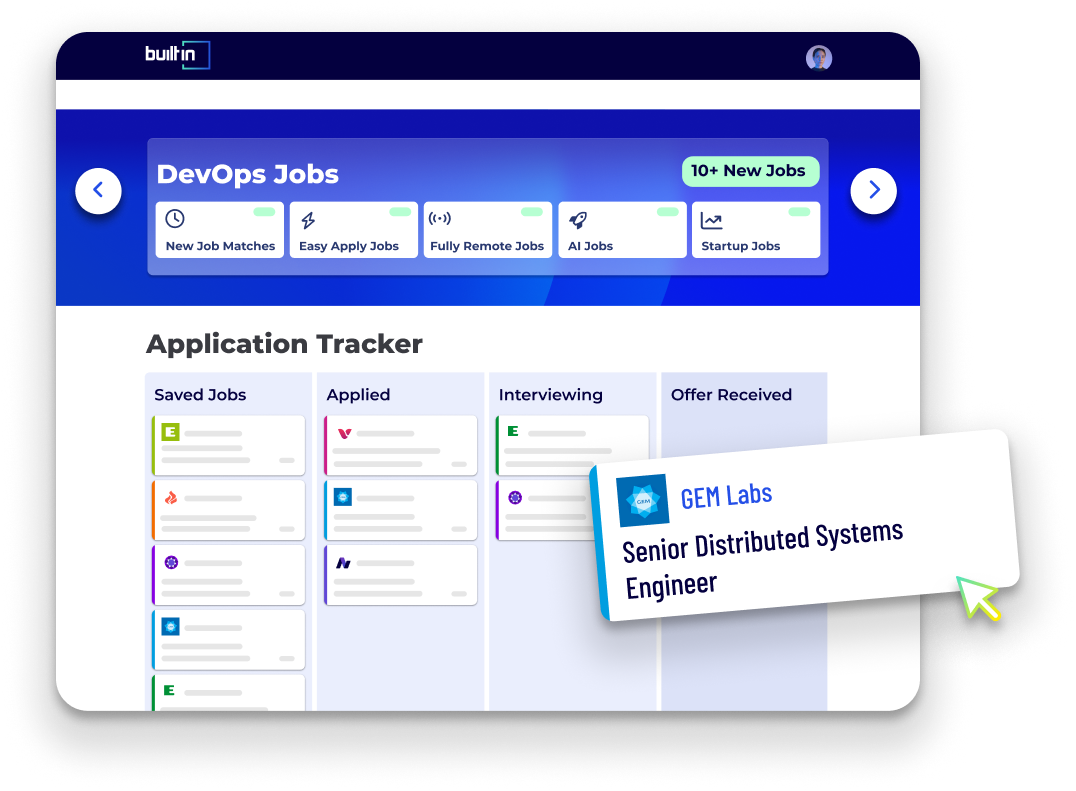
Cloud • Security • Software • Cybersecurity
Architect, build, and support reliable network infrastructure and automation for Akamai’s distributed cloud platform. Develop Bash and Python tooling, establish deployment standards, define SLOs, mentor engineers, and troubleshoot complex network issues. The role requires expertise in large-scale distributed systems, TCP/IP, BGP, Linux networking, configuration management, CI/CD, and open-source networking software, with participation in on-call rotations.
Top Skills:
AnsibleArgocdBashBgpBirdChefFirewallsFrrGithub ActionsGoGobgpJenkinsLinux NetworkingLoad BalancingPuppetPythonRustSaltstackSlack BotsTcp/Ip
16 Days AgoSaved
Cloud • Security • Software • Cybersecurity
Develop and operate Akamai’s Linux-based cloud infrastructure, including bare-metal and virtual machine platforms, kernels, operating systems, and KVM/QEMU virtualization. Build software, automation, observability, and infrastructure enhancements at scale; troubleshoot complex distributed-system issues; collaborate across engineering and operations; mentor team members; and participate in on-call service restoration.
Top Skills:
AnsibleChefKubernetesKvm/QemuLinuxLinux KernelNested VirtualizationPuppetSaltstack
Fintech • Software • Financial Services
Lead the SRE function for NinjaTrader’s trading platform, ensuring availability, scalability, performance, and 99.95% uptime. Responsibilities include managing Kubernetes services, resolving production incidents, participating in a 12x7 on-call rotation, automating deployments and operational tasks, designing monitoring and alerting systems, establishing SLIs/SLOs, using Terraform for infrastructure automation, and implementing cloud security and compliance practices. The role also mentors engineers and collaborates cross-functionally on reliable platform delivery.
Top Skills:
AnsibleAWSAzureBashDatadogDockerGCPGithub ActionsGoGrafanaHelmKubernetesPci DssPrometheusPythonSoc 2Terraform
Reposted 2 Months AgoSaved
Financial Services
Lead SRE for AI platforms responsible for driving reliability culture, designing resilient systems, leading incident response, mentoring engineers, establishing SLOs/error budgets, applying AI-assisted operational workflows, and improving observability, CI/CD, container orchestration, and automation across services.
Top Skills:
.NetAgentic AiAiopsBlack-Box MonitoringCi/CdContainer OrchestrationContainersEnterprise Ai ToolingEvent CorrelationJavaKubernetesNetworkingObservabilityPythonRunbook AutomationService Level Objectives (Slos)Spring BootTelemetry CollectionWhite-Box Monitoring
Insurance • Cybersecurity
Build and operate AWS infrastructure, automation, observability, CI/CD, and internal developer platform capabilities. Improve system resilience through failure testing, automated recovery, capacity planning, and SLOs. Develop reusable self-service tools, lead projects from scoping through rollout, mentor engineers, establish infrastructure standards, collaborate across engineering and security teams, and participate in a low-volume on-call rotation.
Top Skills:
AWSEcsGithub ActionsGoKafkaKubernetesPythonTerraform
Fintech • Analytics
Own the availability, performance, scalability, and reliability of critical shared services. Develop automation, maintain SLOs, improve observability, support cloud migration, and partner with development teams on reliable releases. Participate in on-call rotations, incident response, postmortems, root cause analysis, architectural reviews, and operational testing. Maintain infrastructure as code, CI/CD pipelines, cloud platforms, and monitoring dashboards while promoting strong engineering practices and continuous improvement.
Top Skills:
AWSAzureCi/CdDatadogDockerDynatraceGitKubernetesPythonShellTerraform
Fitness
Lead site reliability and platform engineering initiatives across IT, defining observability strategy, automating operational processes, improving infrastructure reliability, and managing large-scale ambiguous projects. Troubleshoot systems across the application, operating system, and network stack; design cloud and Kubernetes platforms; maintain infrastructure-as-code; improve incident response; and mentor engineers through architecture guidance, documentation, and code reviews.
Top Skills:
AlertingAmazon EksAnsibleAWSAzureBashCloudFormationDashboardsDnsDockerGCPGoHelmKubernetesLinuxLoad BalancingLoggingMetricsMicroservicesNatObservabilityProxiesPulumiPythonReactSecrets ManagementSecurity ScanningService MeshTcp/IpTerraformTracing
Healthtech • Information Technology
Manages and enhances IBM BPM/ODM, WebSphere, cloud, Kubernetes, and OpenShift platforms. Responsibilities include upgrades, patching, risk remediation, containerization, CI/CD integration, automation, platform monitoring, security, scalability, compliance, production incident resolution, release deployments, and development-team guidance. Provides on-call support and collaborates with application teams, vendors, and business stakeholders.
Top Skills:
AnsibleArtifactoryBashBitbucketCi/CdDb2 LuwGitGitHarnessHashicorp ProductsIbm BpmIbm OdmImage ScanningJavaJavaScriptJenkinsKshKubernetesLinuxOpenshiftPerlPrivate CloudProcess Federation ServerPublic CloudPythonRbacSvnTeamcityUrbancode DeployWebsphere LibertyWindows

Information Technology
Leads site reliability and cloud operations in a secure AWS GovCloud environment. Provides technical expertise across Windows, Linux, and AWS; manages incidents and service degradations within SLAs; streamlines ServiceNow, Confluence, Jira, and SAFe processes; develops metrics and reports; documents procedures; coordinates stakeholders and cybersecurity teams; and supports requirements gathering, delegation, and after-hours outage response.
Top Skills:
Agile SafeAWSAws GovcloudConfluenceJIRALinuxServicenowWindows

Healthtech • Pharmaceutical • Manufacturing
Support operational deployments and maintenance for Core Speech production systems. Implement and maintain monitoring, alerting, performance reporting, and capacity planning. Participate in on-call rotation for off-hours reliability support. Drive improvements to system performance and architecture, and collaborate on projects while complying with corporate and quality standards.

Artificial Intelligence • Software
The Site Reliability Engineer will maintain high-performance cloud and on-premises services, automate tasks, troubleshoot production issues, and collaborate with product teams.
Top Skills:
AWSAzureBashDockerGCPGoJavaJavaScriptKubernetesLinuxOpenshiftPodmanPrometheusPython
Reposted 2 Months AgoSaved
Easy Apply
Easy Apply
Cloud • Information Technology • Security • Software • Cybersecurity
Responsible for managing operations within classified environments, overseeing cloud infrastructure, automating tasks, and ensuring system stability in a high-security setting.
Top Skills:
AnsibleAws EcsKubernetesLinuxPythonTerraform
Aerospace • Other
Design, deploy, operate, and scale GPU/CPU infrastructure supporting classified AI and national security missions. Responsibilities include managing Kubernetes and AI clusters, automating on-premise infrastructure deployments, supporting GPU-as-a-service platforms, operating databases, monitoring, and distributed storage, and improving service reliability, scalability, and availability. The role collaborates closely with AI engineers and requires Linux, infrastructure automation, containerization, scripting, software development, and security-clearance eligibility.
Top Skills:
AnsibleBashBazelC++Distributed DatabasesGoKubernetesLinuxMakefilesNvidia Gpu Deployment StacksOci ContainersPythonTcp/IpTerraformVirtualization

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies Hiring Site Reliability Engineers
See All






Popular Job Searches
All Software Engineer Jobs
.NET Developer Jobs
Aerospace Thermal Engineering Jobs
AI Engineer Jobs
Android Developer Jobs
Automation Engineer Jobs
Backend Developer Jobs
Blockchain Developer Jobs
C# Jobs
C++ Jobs
Cloud Architect Jobs
Cloud Engineer Jobs
Design Engineer Jobs
DevOps Engineer Jobs
Director Of Engineering Jobs
Electrical Engineering Jobs
Embedded Software Engineer Jobs
Engineering Jobs
Engineering Manager Jobs
Environmental Engineering Jobs
Field Engineer Jobs
Front End Developer Jobs
Full Stack Developer Jobs
Game Developer Jobs
Golang Jobs
Hardware Engineer Jobs
Industrial Engineering Jobs
iOS Developer Jobs
Java Developer Jobs
Javascript Developer Jobs
Linux Jobs
Manufacturing Engineer Jobs
Mechanical Engineering Jobs
Network Engineer Jobs
PHP Developer Jobs
Process Engineer Jobs
Project Engineer Jobs
Prompt Engineering Jobs
Python Jobs
QA Jobs
Robotics Engineer Jobs
Ruby on Rails Jobs
Salesforce Administrator Jobs
Salesforce Developer Jobs
Scala Jobs
Sharepoint Developer Jobs
Site Reliability Engineer Jobs
Software Engineering Manager Jobs
Solutions Architect Jobs
SQL Developer Jobs
Structural Engineer Jobs
System Engineer Jobs
Test Engineer Jobs
Web Developer Jobs
All Filters
Total selected ()
No Results
No Results
