

Maximum of 25 job preferences reached.
Top Site Reliability Engineer Jobs
Fintech
Design, build, and maintain scalable, reliable application infrastructure; automate deployments and recovery; implement observability and monitoring; troubleshoot performance bottlenecks; advise development teams on microservice best practices; produce runbooks; participate in 24x7 on-call rotation and ensure security and compliance.
Top Skills:
AWSCi/CdDockerEncryption ProtocolsGitGoIpJavaJavaScriptKubernetesLinuxObservabilityPythonRubyScripting LanguagesSwarmTcpUdp

Artificial Intelligence • Cloud • Machine Learning • Infrastructure as a Service (IaaS)
Own and improve reliability, performance, and capacity of Lambda's production storage fleet. Build monitoring, alerting, CI/CD, and self-healing automation; investigate and resolve storage incidents; automate operational workflows; collaborate with storage, networking, and release teams; participate in on-call rotation to reduce MTTR and operational toil.
Top Skills:
AlertmanagerAnsibleArgocdBuildkiteCephClushCsi DriversDatadogDell PowerscaleDockerEthtoolGithub ActionsGoGpfsGpudirect StorageGrafanaHelmInfinibandJenkinsKubernetesKustomizeKvm/QemuLinuxLustreMlxlinkNetappNfsNvme-Of/TcpPodmanPrometheusPythonRdmaRoceS3SmbSQLSr-IovSumologicTerraformVastVector DbWeka

Software
Own and improve reliability, performance, and capacity of Lambda's production storage fleet. Build monitoring, alerting, CI/CD, and self-healing automation; troubleshoot storage incidents and low-level I/O/network issues; automate deployments and incident workflows; participate in on-call to reduce MTTR.
Top Skills:
AlertmanagerAnsibleArgocdBuildkiteCephDatadogDockerGithub ActionsGoGpfsGrafanaHelmJenkinsKubernetesKustomizeLinuxLustreNfsNvme-Of/TcpPodmanPrometheusPythonS3SmbSQLSumologicTerraformVector Db

Cloud • Software
The Senior Site Reliability / Gitops Engineer will drive automation and collaboration within the IS team, enhancing Canonical's IT operations and services while managing infrastructure as code and cloud technologies.
Top Skills:
Cloud ComputingDockerElasticsearchGitopsGrafanaIacKubernetesLinuxPrometheusPython
Insurance
Lead reliability and observability for the financial data platform: define SLOs/SLIs, build metrics pipelines, extend instrumentation across Velocity, Redpanda, MuleSoft, Snowflake, Fabric, and AWS; implement incident management (Datadog -> Incident.io -> ServiceNow), scale automation and remediation, and design AI-assisted SRE agents using Cursor for triage and root-cause analysis.
Top Skills:
Ai Coding AssistantsAWSCursorD365DatadogFabricGrafanaIncident.IoKafkaLlmsMulesoftOpentelemetryPower AppsPrometheusRedpandaServicenowSnowflakeVelocity

Cloud • Software
Lead incident detection and resolution, design automation and self-healing systems, build observability and AI/ML-powered operational tooling, define SLOs/SLIs and error budgets, mentor engineers, and operate in a 24/7 global SRE model to improve reliability and reduce toil.
Top Skills:
AirflowArgo WorkflowsCachingCi/CdClaude CodeCodexCursorDatadogDnsDockerElkGithub CopilotGoGrafanaHTTPKubernetesLinuxLoad BalancingPrometheusPythonSplunkTemporalUnix
Aerospace • Other
Design, deploy, and automate core infrastructure (on‑prem and cloud) and manage Kubernetes and Linux fleets. Collaborate with engineers to build scalable, operable services and improve lifecycle: testing, CI/CD, deployment, monitoring, and performance.
Top Skills:
AnsibleBashBazelCi/CdCloudDatabasesDistributed DatabasesKubernetesLinuxMakefilesMonitoringPythonStorageTcp/IpTerraform
Aerospace • Other
Design, deploy, and automate infrastructure for on‑prem and cloud compute. Manage core services (databases, monitoring, storage), collaborate with software teams to build scalable, operable systems, and own the service lifecycle from design through deployment, operation, and refinement to ensure secure, reliable, and autonomous satellite software services.
Top Skills:
AnsibleBashBazelCloudDatabasesKubernetesLinuxMakefilesMonitoringPythonTcp/IpTerraform
Aerospace • Other
Design, deploy, and automate on‑prem and cloud compute infrastructure; manage core infrastructure (databases, monitoring, storage); collaborate with software teams to build scalable, operable systems; improve service lifecycle from design through deployment, operation, and refinement.
Top Skills:
AnsibleBashBazelDatabasesKubernetesLinuxMakeMakefilesMonitoringPythonStorageTcp/IpTerraform

Information Technology • Security • Cybersecurity
Design, build, and scale Kubernetes-based, multi-tenant infrastructure and CI/CD systems. Own AI tooling infrastructure (MCP servers) and secure AI access patterns. Optimize CI/CD, streaming analytics (Kafka, Flink, ClickHouse), observability, and incident response. Implement IaC (Terraform, Helm, Pulumi), GitOps (Argo CD), progressive delivery, automated testing, and mentor engineering teams.
Top Skills:
Ai AgentsAi/Llm ToolingAksArgo CdBashClickhouseDatadogEksFlinkGithub ActionsGitlab CiGitopsGkeGoGrafanaHelmJenkinsKafkaKubernetesLangfuseLangsmithMcp ServersMlopsOpentelemetryPrometheusPulumiPythonTerraform

Software
Support and improve production SaaS infrastructure across AWS, colocation, and hosted platforms. Administer Windows and Linux systems, virtualization, storage, networking, and database support. Lead incident troubleshooting, root cause analysis, monitoring improvements, vulnerability remediation, automation initiatives, and medium-sized infrastructure projects. Collaborate on compliance (SOX/PCI/HIPAA), disaster recovery, and documentation to increase operational reliability.
Top Skills:
AWSBackup And RecoveryBashDatabasesFirewallsLinuxMonitoring PlatformsNetworkingPowershellPythonStorage SystemsVirtualizationWindows Server

Software • Financial Services
Lead reliability, observability, and resilience for cloud-based financial SaaS. Define SLOs/SLIs, design monitoring/tracing, own incident response and runbooks, build IaC and automation, implement AIOps, perform chaos and load testing, and write production-grade Python tooling while ensuring security and compliance.
Top Skills:
AnsibleAWSAzureBashCi/CdCloudFormationDatadogElkGitGrafanaNew RelicPowershellPrometheusPythonTerraform
New
Track Smarter, Apply Better.
Ditch the spreadsheets. Organize your job search with our freeApplication Tracker.
Use For Free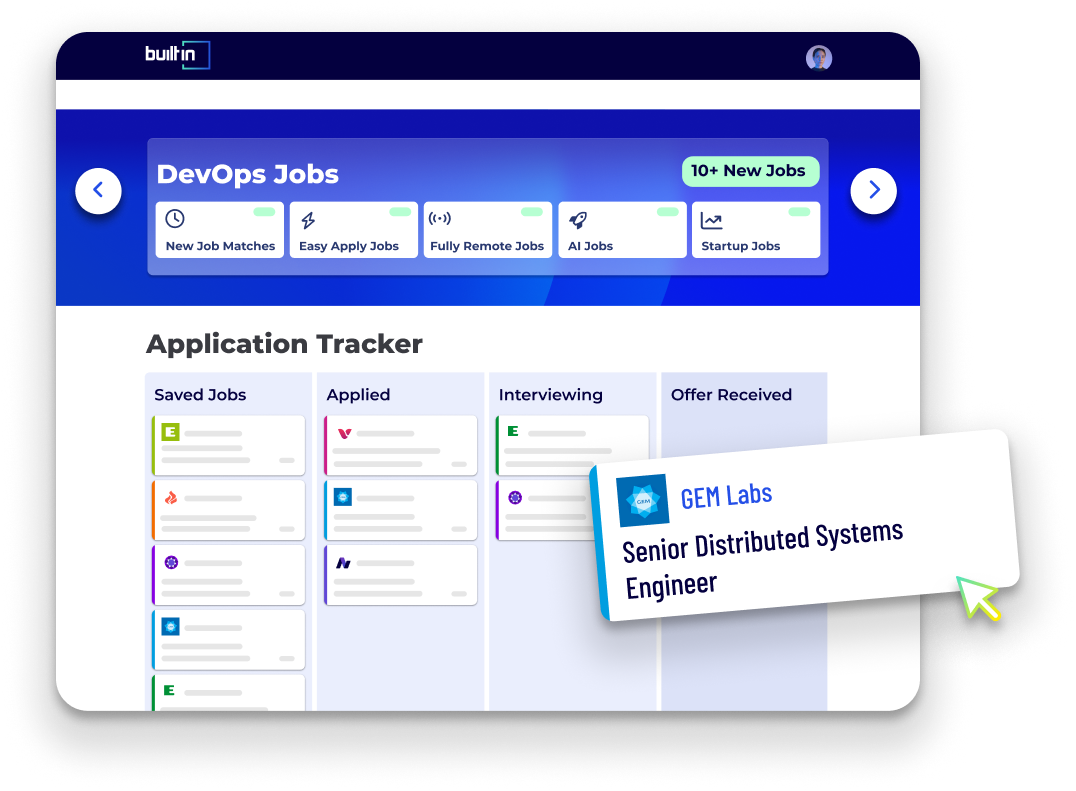

Other
The Senior Site Reliability Engineer ensures the integrity, performance, and reliability of cloud infrastructure, overseeing software development, maintenance, and site reliability issues while promoting industry best practices.
Top Skills:
Cloud InfrastructureDevOpsSoftware Development

Big Data
You will manage AWS infrastructure, automate deployments, debug application issues, and improve the operational health of Metabase Cloud.
Top Skills:
AWSDatadogGoGrafanaKubernetesPrometheusPythonTerraform
Financial Services
Lead reliability and platform engineering for workflow orchestration (Airflow, Automic/UC4). Split between production support/on-call, incident response, SLO/SLI ownership, and engineering projects: automation, IaC, containerization, observability, and platform modernization to improve developer experience.
Top Skills:
AnsibleApache AirflowAutomic/Uc4AWSBash/ShellCeleryCi/CdControl-MDockerElkGrafanaHelmKubernetesLinuxPrometheusPythonTerraformWindows

Cloud • Fintech • HR Tech
Senior SRE responsible for reliability, automation, and security of IL5-compliant cloud platforms. Own infrastructure as code (Terraform, Argo CD), run 24/7 incident response, maintain STIG compliance, operate and patch Windows 365/AVD with Intune, manage Entra ID identity governance, monitor Sentinel/Defender tooling, and automate lifecycle and provisioning for segregated VDI user pools.
Top Skills:
Access PackagesArgo CdAzureAzure FirewallAzure Virtual Desktop (Avd)Ci/CdConditional AccessDefender For Cloud AppsDefender For EndpointExpressrouteGoKubernetesMfa (Passkeys/Tap)Microsoft Entra IdMicrosoft IntuneMicrosoft SentinelNsgPythonRubyStigTerraformVnetWindows 365
Aerospace • Hardware • Defense
Design, build, operate, and scale mission-critical cloud infrastructure. Ensure reliability and SLAs, run on-call rotations, lead architecture and automation (IaC/GitOps), optimize Kubernetes, implement monitoring/alerting, and collaborate with cross-functional teams to improve processes and reliability.
Top Skills:
Aws Ec2Aws LambdaAws S3Aws VpcGitopsInfrastructure-As-CodeKubernetesService MeshService RegistrationTerraform
Cloud • Security • Software • Cybersecurity
Lead reliability and performance efforts for distributed metadata systems: tune and optimize systems, develop monitoring and automation, manage rollouts, troubleshoot incidents, run simulations and analytics, and support database/configuration management to improve global network stability and capacity.
Top Skills:
Big DataLinuxPostgresPythonSQLUnix
Software
Operate and scale Lambda's multi-tenant cloud networking and SDN infrastructure; run Kubernetes control plane and SmartNIC dataplane software; build automation, CI/CD and GitOps workflows; deploy monitoring and observability; collaborate across teams, drive incident response and on-call rotation, capacity planning, and postmortems to improve reliability.
Top Skills:
AnsibleCCi/CdDpdkGitopsGoHelmKubernetesLinuxMonitoring/ObservabilityOpenstack NeutronOvnOvsPythonSmartnicsSr-IovTerraform
Artificial Intelligence • Cloud • Machine Learning • Infrastructure as a Service (IaaS)
Operate and scale a multi-tenant cloud networking platform and SDN infrastructure, manage Kubernetes control plane and SmartNIC dataplane software, build automation and CI/CD/GitOps workflows, deploy observability and monitoring, participate in on-call incident response, and collaborate across software, platform, and networking teams to improve reliability and deployments.
Top Skills:
AnsibleCi/CdGitopsKubernetesLinuxPythonSmartnics
Artificial Intelligence • Software
As a Software Engineer in Reliability, you'll architect and manage multi-cloud GPU infrastructure, ensuring performance, security, and scale while debugging complex hardware/software issues.
Top Skills:
AmdAWSBashGoGpuInfinibandLinuxNvidiaOciPythonRdma

2 Months AgoSaved
Cloud • Information Technology • Internet of Things • Professional Services • Software
Design, deploy, and maintain large-scale, highly available cloud-native systems and tooling. Collaborate with application teams to improve reliability, performance, and security; automate operations; run scale, chaos, and failure testing; participate in 24x7 incident response and on-call rotation; and standardize solutions across a multi-region microservice platform.
Top Skills:
ArgocdAWSCncfGoKubernetesLinuxOpentelemetryPrometheusPythonService MeshThousandeyesUnix
Artificial Intelligence • Information Technology • Consulting • Cybersecurity
Ensure reliability, performance, and scalability of client systems by defining KPIs/SLOs, implementing monitoring/alerting, automating operations, creating runbooks/playbooks, performing capacity planning and load testing, establishing disaster recovery, participating in on-call rotations, collaborating with developers, and practicing chaos engineering to prevent incidents.
Top Skills:
AutomationCapacity PlanningChaos EngineeringDod 8140Load TestingMonitoring And AlertingRunbooks And Playbooks
Artificial Intelligence • HR Tech • Professional Services
Design, build, and operate scalable, reliable cloud infrastructure. Maintain AWS/GCP and Linux systems, Kubernetes clusters, CI/CD pipelines, and monitoring (Prometheus/ELK). Automate operations, troubleshoot production issues, run on-call, conduct reviews, and evaluate new technologies to improve availability and performance.
Top Skills:
AnsibleAWSCi/CdElkGCPJenkinsKubernetesLinuxPrometheusPuppetTerraform
Artificial Intelligence • HR Tech • Professional Services
Design, build, and operate reliable, scalable cloud infrastructure. Maintain AWS/GCP and Linux systems, manage Kubernetes clusters, implement IaC (Ansible/Puppet/Terraform), automate CI/CD (Jenkins), monitor with Prometheus/ELK, triage alerts, participate in design/reviews, migrate apps to Kubernetes, and improve operational automation.
Top Skills:
AnsibleAWSC++ElkGCPGoJenkinsKubernetesLinuxPrometheusPuppetRustTerraformTypescript

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies Hiring Site Reliability Engineers
See All






Popular Job Searches
All Software Engineer Jobs
.NET Developer Jobs
Aerospace Thermal Engineering Jobs
AI Engineer Jobs
Android Developer Jobs
Automation Engineer Jobs
Backend Developer Jobs
Blockchain Developer Jobs
C# Jobs
C++ Jobs
Cloud Architect Jobs
Cloud Engineer Jobs
Design Engineer Jobs
DevOps Engineer Jobs
Director Of Engineering Jobs
Electrical Engineering Jobs
Embedded Software Engineer Jobs
Engineering Jobs
Engineering Manager Jobs
Environmental Engineering Jobs
Field Engineer Jobs
Front End Developer Jobs
Full Stack Developer Jobs
Game Developer Jobs
Golang Jobs
Hardware Engineer Jobs
Industrial Engineering Jobs
iOS Developer Jobs
Java Developer Jobs
Javascript Developer Jobs
Linux Jobs
Manufacturing Engineer Jobs
Mechanical Engineering Jobs
Network Engineer Jobs
PHP Developer Jobs
Process Engineer Jobs
Project Engineer Jobs
Prompt Engineering Jobs
Python Jobs
QA Jobs
Robotics Engineer Jobs
Ruby on Rails Jobs
Salesforce Administrator Jobs
Salesforce Developer Jobs
Scala Jobs
Sharepoint Developer Jobs
Site Reliability Engineer Jobs
Software Engineering Manager Jobs
Solutions Architect Jobs
SQL Developer Jobs
Structural Engineer Jobs
System Engineer Jobs
Test Engineer Jobs
Web Developer Jobs
All Filters
Total selected ()
No Results
No Results
