

Maximum of 25 job preferences reached.
Top Site Reliability Engineer Jobs

Artificial Intelligence • Cloud • Information Technology • Consulting
Design, build, and optimize cloud infrastructure and deployment systems. Responsibilities include improving Infrastructure as Code practices, optimizing AWS and GCP environments for scalability, security, and cost, developing cloud operations tools, enhancing FluxCD and Jenkins CI/CD workflows, and strengthening monitoring, alerting, and observability with Prometheus, Grafana, and logging tools.
Top Skills:
AnsibleAWSAws EksCi/CdDebianDockerFluxcdGCPGcp GkeGitopsGoGrafanaInfrastructure As CodeJenkinsKubernetesLinuxPackerPrometheusPythonTerraform

Logistics • Sales • Software • 3PL: Third Party Logistics
Build and operate reliable cloud platforms using Azure, Kubernetes, Docker, CI/CD, infrastructure as code, monitoring, and automation. Responsibilities include designing observability solutions, supporting application development, managing AKS clusters and networking, improving security, conducting incident response and root cause analysis, creating documentation, and participating in on-call rotations.
Top Skills:
.NetAzure Api ManagementAzure DevopsAzure Kubernetes Service (Aks)Azure Managed IdentityAzure Service BusAzure Virtual NetworksChefDnsDockerGithub ActionsJavaKotlinKubernetesAzureNew RelicNode.jsPostgresPuppetPythonRbacRedisSQL ServerTerraformTraefik
Blockchain • Fintech • Payments • Consulting • Cryptocurrency • Cybersecurity • Quantum Computing
Supports enterprise platform operations through maintenance, monitoring, troubleshooting, incident response, deployments, patching, Linux administration, and production-readiness validation. Contributes to automation, observability, dashboards, REST integrations, CI/CD, configuration management, capacity analysis, documentation, and reliability improvements while working with engineering, infrastructure, cybersecurity, and operations teams.
Top Skills:
AnsibleApache NifiAWSAzureBashBitbucketBmc DiscoveryChefCi/CdCmdbDnsDynatraceGitGoHttp/HttpsItsmJavaJenkinsLinuxPowershellPythonRemedyRest ApisSplunkSshSsl/TlsTcp/IpUnixXlr
Blockchain • Fintech • Payments • Consulting • Cryptocurrency • Cybersecurity • Quantum Computing
Supports enterprise platforms throughout their lifecycle, including production monitoring, incident response, patching, vulnerability remediation, releases, capacity planning, and reliability improvements. Develops automation, CI/CD integrations, and infrastructure management solutions while improving observability, operational readiness, and platform stability. Collaborates with engineering and global operations teams, performs root cause analysis, manages production risks, and maintains operational documentation.
Top Skills:
Active DirectoryAPIsArtifact RepositoriesBashCi/CdCmdbDeployment AutomationDevOpsInfrastructure AutomationItsmLdapLinuxMonitoringObservabilityPowershellPythonSource Control SystemsSshUnixWindows

Artificial Intelligence • Big Data • Healthtech • Information Technology • Machine Learning • Software • Analytics
Provides 24/7 production support for identity management applications, coordinating incident resolution, root-cause analysis, issue tracking, quality assurance, and operational process improvement. Develops and maintains cloud-based software, automates common tasks, evaluates tools, and supports CI/CD and containerized platforms. Requires expertise in AWS, Java, Scala, Python, distributed data services, monitoring, Unix, and big-data technologies.
Top Skills:
Amazon CloudwatchAmazon EcsAmazon EmrAmazon RdsAmazon S3Apollo GraphqlAthenaAWSAws LambdaDynamoDBElastic ApmGithub ActionsHadoopHbaseHiveJavaKubernetesMicroservicesMongoDBPythonScalaSpring BootUnix
Cloud • Fintech • Information Technology • Machine Learning • Software • App development • Generative AI
Design, develop, and scale cloud-based backend services and microservices while improving reliability, security, performance, and maintainability. Build CI/CD pipelines, observability, and automated deployment solutions; establish SRE practices including SLIs, SLOs, and incident response. Mentor engineers, support releases, troubleshoot production issues, and drive resilient architecture and continuous engineering improvement across teams.
Top Skills:
.NetAmazon EksAmazon SqsArgocdAWSAzureAzure AksC#CloudFormationCSSDatadogDockerElk StackGCPGithub ActionsGitlab CiGoGrafanaHelmHTMLJavaJavaScriptJenkinsKafkaKubernetesMicroservicesNoSQLOpentelemetryPostgresPrometheusPythonRabbitMQRest ApisSplunkSQLSQL ServerTerraform

Fintech • Information Technology • Payments • Productivity • Software • Travel • Automation
Design, develop, and operate reliable cloud infrastructure, automation, tooling, and deployment systems. Improve system observability, scalability, fault tolerance, and uptime by identifying reliability issues and eliminating operational toil. Establish SLO/SLI and monitoring standards, support blameless postmortems, and use AI-assisted tools to improve autonomous operations and engineering productivity. Collaborate with engineering, security, release, and productivity teams while owning production-quality infrastructure projects.
Top Skills:
Ai Tools And PlatformsAutomationCloud InfrastructureDeployment PipelinesInfrastructure As CodeMonitoringObservabilitySlo/Sli Frameworks
Financial Services
Leads reliability engineering for high-uptime electronic trading infrastructure. Designs and manages infrastructure, improves network reliability, supports sustainable software releases, drives automation and AI-assisted incident analysis, and prevents recurring incidents through scalable solutions. Partners with development teams and stakeholders across the software lifecycle and supports follow-the-sun operations across multiple locations.
Top Skills:
Artificial IntelligenceIncident ManagementInfrastructure AutomationNetwork DesignSite Reliability EngineeringSoftware Development Lifecycle (Sdlc)
7 Days AgoSaved
Artificial Intelligence • Cloud • Information Technology • Consulting
Maintains, deploys, troubleshoots, and optimizes large-scale HPC infrastructure at Oak Ridge National Laboratory. Responsibilities include cluster validation, node failure diagnosis, system and performance tuning, log analysis, application build and configuration support, ticket management, documentation, and development of automation, scripting, and monitoring tools. The role supports high-stakes scientific research and requires onsite work, U.S. citizenship, and high-level security clearance.
Top Skills:
BashC++Cray PeFortranGpusHpcLinuxMpiOpenmpPythonRocmSlurm
7 Days AgoSaved
Artificial Intelligence • Cloud • Information Technology • Consulting
Maintain, deploy, troubleshoot, optimize, and monitor large-scale high-performance computing infrastructure at Oak Ridge National Laboratory. Responsibilities include cluster validation, node failure diagnosis, application builds, log analysis, performance tuning, automation, scripting, and collaboration with researchers and internal technical teams. The role requires Linux, Python, Bash, SLURM, HPC, GPU, MPI, and compiler expertise, along with U.S. citizenship and a minimum Top Secret clearance.
Top Skills:
BashC++Cray PeFortranGpusHigh-Performance Computing (Hpc)LinuxMpiOpenmpPythonRocmSlurm
Financial Services
Leads site reliability engineering initiatives for critical applications and platforms. Responsibilities include resiliency design reviews, reliability and stability improvements, SLI/SLO and error-budget development, major-incident leadership, observability, CI/CD, container orchestration, networking troubleshooting, AI-assisted incident response, and mentoring engineers. The role also establishes guardrails for AI-enabled reliability workflows while ensuring security, auditability, and operational resilience.
Top Skills:
.NetAi-Assisted OperationsBlack-Box MonitoringCi/CdContainer OrchestrationContainerizationJavaNetworkingObservabilityPythonService Level ObjectivesSpring BootTelemetryWhite-Box Monitoring
Financial Services
Improve the reliability, resilience, and performance of mission-critical payment platforms. Responsibilities include coding automation and reliability solutions, incident triage, observability implementation, Kafka pipeline monitoring, toil reduction, cloud infrastructure support, and applying AI-assisted operational analysis. The role requires collaboration across teams to improve service level objectives, root-cause resolution, security, auditability, and operational resilience.
Top Skills:
Ai Agentic ModelsContainersContinuous DeliveryContinuous IntegrationDynatraceGrafanaKafkaLinuxMcp-Based FrameworksOpentelemetrySplunkWindows
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free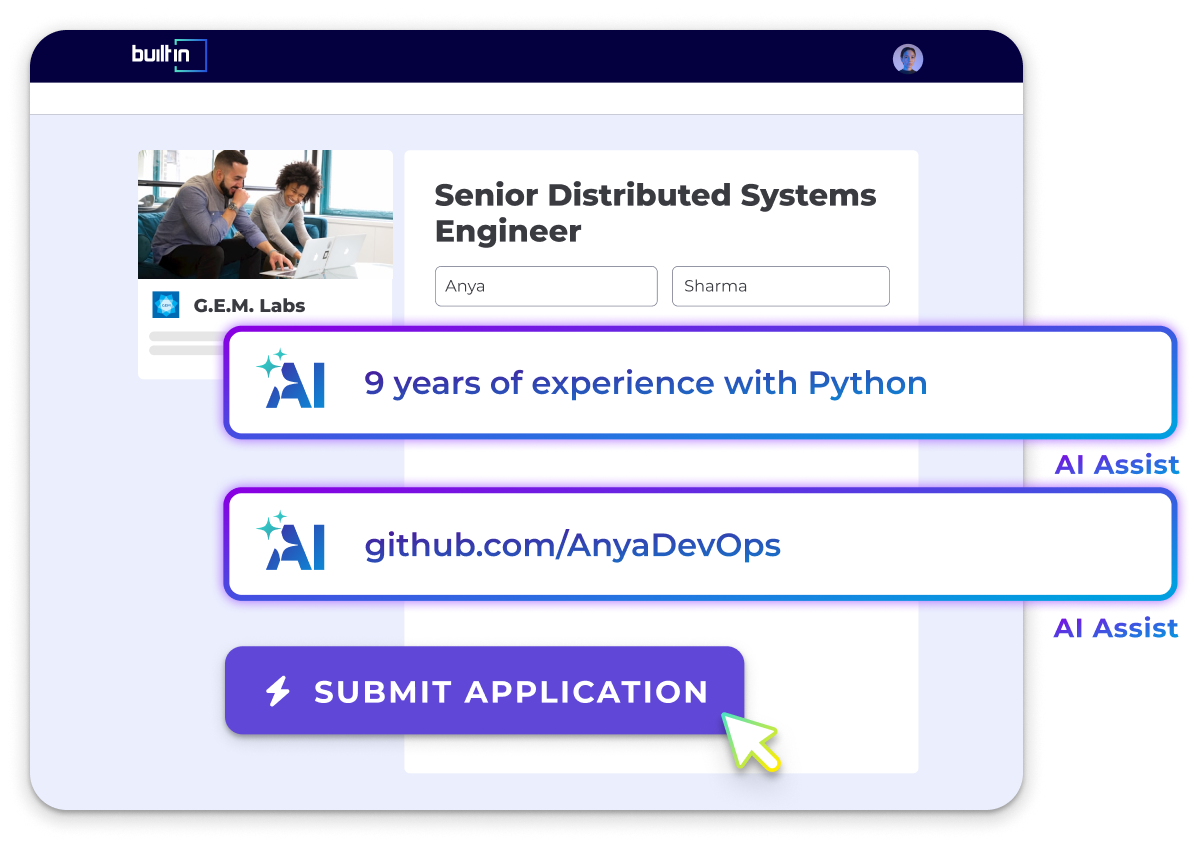
Financial Services
Configure, maintain, monitor, and optimize highly available payment platforms and infrastructure. Build deployment pipelines, infrastructure and network as code, Kafka ingestion reliability, observability, SLOs, incident response, and automated remediation. Collaborate across teams to resolve complex issues, improve operational maturity, and safely apply AI capabilities to reliability workflows.
Top Skills:
.NetAi Agentic ModelsContainer OrchestrationContainersContinuous DeliveryContinuous IntegrationDynatraceGrafanaJavaKafkaMcp-Based FrameworksOpentelemetryPythonSplunkSpring Boot
Fintech • Machine Learning • Payments • Software • Financial Services
Leads reliability architecture and strategy for large-scale production systems, including automation, incident management, root-cause analysis, multi-cloud Infrastructure as Code, SLO governance, capacity planning, FinOps, security governance, and platform optimization. Mentors SRE teams, establishes organization-wide reliability practices, and drives multi-year technical roadmaps across engineering organizations.
Top Skills:
AgileAWSCi/CdGenerative AiGoogle Cloud PlatformHeadless AiInfrastructure As CodeKubernetesAzureObservabilityScrumSecrets ManagementServerlessZero Trust
Financial Services
Leads AWS cloud production management and site reliability engineering across business-critical services. Defines SLI/SLO practices, error budgets, observability, capacity planning, resiliency, infrastructure automation, and cost optimization. Drives major incident response, root-cause analysis, production readiness, disaster recovery, and durable remediation across engineering teams. Establishes responsible AI-assisted development practices and communicates complex technical strategies to leadership in a regulated environment.
Top Skills:
Active-Active ArchitectureAi-Assisted Software Development ToolsAlertingAnomaly DetectionAWSCloud Cost OptimizationDashboardsDisaster RecoveryDistributed TracingInfrastructure As CodeLoggingMetricsMulti-Region ArchitectureObservabilitySre
Fintech • Machine Learning • Payments • Software • Financial Services
Leads reliability engineering for large-scale, multi-cloud production systems. Responsibilities include architectural resilience, automation, incident and crisis management, root-cause analysis, infrastructure-as-code governance, SLO and error-budget programs, mentoring, capacity forecasting, cost optimization, FinOps, observability, security governance, and platform innovation.
Top Skills:
AWSCi/CdGenerative AiGoogle Cloud Platform (Gcp)Infrastructure As Code (Iac)KubernetesAzureSecrets ManagementServerlessZero Trust

Fintech • Financial Services
Provides technical leadership for enterprise workplace technology platforms, focusing on site reliability, observability, incident management, automation, resilience, and continuous improvement. Designs and tests complex infrastructure solutions, develops Python-based automation, analyzes telemetry, and improves recovery and stability. Supports AI-assisted incident triage, root cause analysis, proactive remediation, and self-healing capabilities. The role also addresses cloud security, secrets management, key rotation, risk controls, and operational standards while mentoring engineers and collaborating across teams.
Top Skills:
Agentic AiElasticGenerative AiGrafanaInfrastructure As CodeKubernetesLarge Language ModelsLow-Code/No-Code PlatformsPrometheusPythonRetrieval-Augmented GenerationSplunk
Fintech • Financial Services
Provides technical leadership for enterprise workplace technology platforms, focusing on site reliability, observability, incident management, automation, operational resilience, and continuous improvement. Develops Python-based automation and data solutions, designs infrastructure systems, analyzes cloud security and secrets management, and uses telemetry to reduce incidents and recovery time. Leads AI-assisted triage, root cause analysis, workflow automation, proactive remediation, and self-healing initiatives while mentoring colleagues and managing operational risk.
Top Skills:
Agentic AiAPIsElasticGenerative AiGrafanaInfrastructure As CodeKubernetesLarge Language ModelsLow-Code/No-Code PlatformsPrometheusPrompt EngineeringPythonRetrieval-Augmented GenerationSplunk
Fintech • Financial Services
Provides technical leadership for enterprise workplace technology reliability and infrastructure platforms. Establishes SRE practices across observability, SLIs, SLOs, error budgets, incident management, automation, and operational resilience. Develops Python-based automation and data solutions, analyzes telemetry, improves recovery and stability, and supports AI-assisted incident triage, root cause analysis, proactive remediation, and self-healing capabilities. Designs, tests, documents, and upgrades complex infrastructure systems while managing operational risk and controls.
Top Skills:
Agentic AiApi IntegrationsContainersElasticGenerative AiGrafanaInfrastructure As CodeKubernetesLarge Language ModelsLow-Code/No-Code PlatformsPrometheusPythonRetrieval-Augmented GenerationSplunk
Financial Services
Lead Site Reliability Engineer responsible for building highly available, scalable, and self-healing systems. The role focuses on AWS monitoring, logging, observability, Terraform-based infrastructure automation, security controls, compliance validation, CI/CD, and operational automation. The engineer will troubleshoot critical application and platform components, improve reliability, reduce toil, guide engineering teams, and champion site reliability practices across complex systems.
Top Skills:
AWSAws CloudformationBashCi/CdDevOpsInfrastructure As CodePowershellPythonTerraform
Financial Services
Leads software reliability engineering for cloud applications and infrastructure. Designs CI/CD pipelines, infrastructure as code, observability, monitoring, and scalable production systems. Responds to alerts, provides on-call support, improves service reliability, and promotes SRE practices. Develops data pipelines and coaches teams on secure, responsible AI-assisted engineering, including validation of AI-generated code and recommendations.
Top Skills:
.NetApache AirflowAutosysAWSAws CdkBitbucketCi/CdControl-MDatabricksDatadogDockerDynatraceExadataGitGrafanaJavaJenkinsKubernetesMavenOpentelemetryOraclePl/SqlPrometheusPysparkPythonScalaShell ScriptingSonarSplunkSpring BootSQLTerraformUnix
Financial Services
Leads reliability engineering for enterprise backup and data protection platforms, including Cohesity, Commvault, and NetBackup. Responsibilities include platform administration, disaster recovery, backup policy management, observability, incident response, resiliency design, automation, compliance certification, and AI-assisted operational workflows. The role mentors engineers, establishes service level objectives, improves platform stability, and supports mission-critical infrastructure through scheduled 7x12-hour shifts, including weekends.
Top Skills:
.NetAmazon EcsCohesityCommvaultDatadogDockerDynatraceGitlabGrafanaJavaJenkinsKubernetesNasNetbackupPrometheusPythonSanSplunkSpring BootTerraform

Digital Media • Information Technology • News + Entertainment
Design and operate highly scalable, reliable cloud infrastructure for large-scale distributed systems across AWS and Kubernetes. Develop infrastructure-as-code, configuration management, automation, observability, and incident-resolution tooling. Participate in on-call rotations, handle service escalations, and create system documentation and playbooks for the BuyerCloud and Revenue Science teams.
Top Skills:
AnsibleAWSC++CloudFormationConfiguration ManagementInfrastructure As CodeJavaKubernetesLinuxObservabilityPythonTerraform
Information Technology • Insurance • Software
Ensures high availability, stability, performance, and supportability of Vertafore products. Responsibilities include troubleshooting applications, databases, configurations, and code; resolving escalations; automating support processes and deployment pipelines; coordinating releases; monitoring systems; conducting root-cause analysis; maintaining runbooks; supporting projects; participating in on-call coverage; and mentoring team members.
Top Skills:
AgileC#ItilLinuxMicrosoft .NetWindowsPowershellPythonSQL Server
Financial Services
Build and operate resilient software solutions that improve application availability, scalability, observability, and reliability. Responsibilities include developing CI/CD pipelines, troubleshooting distributed systems, defining SLIs and SLOs, improving telemetry and alerting, automating operational processes, and reducing production risk. The role also applies responsible AI-assisted development practices, collaborates across engineering teams, and contributes to incident prevention, release safety, and continuous improvement.
Top Skills:
.NetAi-Assisted Software Development ToolsAmazon Elastic Container ServiceContinuous DeliveryContinuous IntegrationDatadogDockerDynatraceGitlabGrafanaInfrastructure As CodeJavaJenkinsKubernetesObservabilityPrometheusPythonService Level IndicatorsService Level ObjectivesSplunkSpring BootTerraform

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies Hiring Site Reliability Engineers
See All





Popular Job Searches
All Software Engineer Jobs
.NET Developer Jobs
Aerospace Thermal Engineering Jobs
AI Engineer Jobs
Android Developer Jobs
Automation Engineer Jobs
Backend Developer Jobs
Blockchain Developer Jobs
C# Jobs
C++ Jobs
Cloud Architect Jobs
Cloud Engineer Jobs
Design Engineer Jobs
DevOps Engineer Jobs
Director Of Engineering Jobs
Electrical Engineering Jobs
Embedded Software Engineer Jobs
Engineering Jobs
Engineering Manager Jobs
Environmental Engineering Jobs
Field Engineer Jobs
Front End Developer Jobs
Full Stack Developer Jobs
Game Developer Jobs
Golang Jobs
Hardware Engineer Jobs
Industrial Engineering Jobs
iOS Developer Jobs
Java Developer Jobs
Javascript Developer Jobs
Linux Jobs
Manufacturing Engineer Jobs
Mechanical Engineering Jobs
Network Engineer Jobs
PHP Developer Jobs
Process Engineer Jobs
Project Engineer Jobs
Prompt Engineering Jobs
Python Jobs
QA Jobs
Robotics Engineer Jobs
Ruby on Rails Jobs
Salesforce Administrator Jobs
Salesforce Developer Jobs
Scala Jobs
Sharepoint Developer Jobs
Site Reliability Engineer Jobs
Software Engineering Manager Jobs
Solutions Architect Jobs
SQL Developer Jobs
Structural Engineer Jobs
System Engineer Jobs
Test Engineer Jobs
Web Developer Jobs
All Filters
Total selected ()
No Results
No Results
