

Maximum of 25 job preferences reached.
Top Site Reliability Engineer Jobs

Artificial Intelligence • eCommerce • Retail • Software
Build and maintain CI/CD pipelines, manage and automate cloud infrastructure and configurations, implement monitoring/logging and alerting for reliability, enforce security and compliance practices, and collaborate with development teams to support scaling and operations.
Top Skills:
Soc ISoc Ii

Artificial Intelligence • Machine Learning • Software
Build and lead the Site Reliability Engineering function across cloud, colocation, on-premises labs, and customer-facing services. Establish SLOs, observability, incident management, IaC automation, self-healing infrastructure, FinOps, capacity planning, and shared-storage architecture. Lead SRE and data center teams, hire and develop engineers, manage reliability and technical direction, and serve as the senior incident escalation point.
Top Skills:
AnsibleAWSAzureDatadogGCPGoGrafanaInfinibandItilKubernetesLinuxLsfNasNfsNvlinkPrometheusPythonRoceSanSlurmSmbSplunkTerraform

Healthtech • Software
Provide technical leadership for site reliability engineering, applying software engineering practices to large-scale operations. Design automated, repeatable operational solutions; monitor service objectives, application performance, and business metrics; improve resiliency, efficiency, and cost. Support cloud and on-premise infrastructure, production applications, deployment automation, testing, and vulnerability response. Partner with software development, security, and business teams while promoting Agile practices, change management, training, and operational health.
Top Skills:
AnsibleAzureCC++ChefDockerEcsGithub CopilotGoJavaKubernetesLinuxPerlPuppetPythonRubyTerraformWindows
Artificial Intelligence • Big Data • Healthtech • Software • Biotech
Owns resilience, performance, scalability, and operational cost improvements for a cloud-native platform. Designs and delivers full-stack solutions, builds monitoring and analysis capabilities, performs architectural and code reviews, and resolves complex production issues. The role requires pragmatic modernization judgment, AI-assisted development experience, customer or user accountability, and participation in a weekend on-call rotation.
Top Skills:
Ai-Assisted DevelopmentCloud-Native PlatformsDashboardsFull-Stack Web ApplicationsGrafanaLoggingMonitoring
Healthtech • Software • Analytics
Own and evolve CluePoints’ Azure and Kubernetes platform, including infrastructure, networking, GitOps delivery, observability, managed databases, security controls, disaster recovery, and cost optimization. Lead incident response, on-call operations, technical initiatives, audit preparation, and cross-team platform adoption. Mentor engineers and improve the reliability, security, and efficiency of business-critical SaaS systems supporting clinical-trial software.
Top Skills:
Ai PlatformsAksArgo CdAzureBashCi/CdDnsElasticExternal SecretsFinopsGateway ApiGitopsGoGrafanaIstioKedaKibanaKubernetesLlmMySQLPostgresPrometheusPythonTemporalTerraformTrinoVaultWaf
Artificial Intelligence • Cybersecurity
Own and evolve the company-wide SRE strategy, reliability standards, observability practices, incident management, service ownership, SLOs, and on-call operations. Lead cross-functional reliability initiatives, establish dashboards, alerts, runbooks, and escalation paths, improve production readiness and incident response, and operate large-scale distributed systems across AWS and Kubernetes. Participate in a 24/7 on-call rotation and help shape the SRE function.
Top Skills:
Argo CdAWSDatadogGitlab CiGitopsGrafanaKubernetesNew RelicPythonTerraform

Information Technology • Professional Services • Defense • Manufacturing
Owns the reliability, security, and usability of an ICAM environment while applying SRE practices to delivery platforms. Responsibilities include RHEL, directory, API gateway, and Cassandra administration; workflow automation; monitoring SLOs; incident response; troubleshooting; postmortems; documentation; and collaboration with engineering teams. The role requires experience with observability tools, GitHub, GitHub Actions, infrastructure as code, containers, and Azure or AWS, plus U.S. citizenship and Public Trust eligibility.
Top Skills:
AWSAzureBroadcom Ca Dx DirectoryContainerizationDatadogDatastax Enterprise CassandraGitGithub ActionsInfrastructure As CodeLayer7 Ca Api GatewayLdapRhelSplunkTerraform

Aerospace • Big Data • Fintech • Software • Analytics
Designs, maintains, and improves reliable, scalable production systems and infrastructure. Responsibilities include incident response, post-mortems, SLO and SLI management, Kubernetes administration, automation, capacity planning, performance optimization, documentation, and on-call support. The role partners with development and operations teams to embed reliability practices, reduce operational toil, and improve service availability and performance.
Top Skills:
AnsibleArgocdAWSAzureBashChefCoralogixGCPGithub ActionsGoGrafanaHarnessHelmKubernetesOpentelemetryPrometheusPulumiPuppetPythonTerraform
Other • Retail
Lead and develop an SRE team responsible for the reliability, availability, performance, automation, and observability of Linux-based digital commerce infrastructure. Set SRE and DevOps strategy, modernize Kubernetes and CI/CD practices, establish automation and infrastructure-as-code standards, oversee incident response, and drive SLIs, SLOs, and error budgets. Partner across engineering, architecture, infrastructure, security, networking, and product teams while recruiting, mentoring, and developing SRE talent.
Top Skills:
Apache TomcatCi/CdDatadogDockerError BudgetsF5Github ActionsInfrastructure As CodeJfrog ArtifactoryKubernetesLinuxNginxPuppetPythonSlis/SlosTerraformVMware
One Month AgoSaved
Artificial Intelligence • Cloud • Fintech • Information Technology • Insurance • Financial Services • Big Data Analytics
Leads a cloud SRE shared-services organization supporting AWS application platforms. Responsibilities include managing and mentoring engineers, modernizing infrastructure, governing Terraform modules and AWS patterns, building self-service provisioning and Harness CI/CD automation, establishing SLOs and error budgets, resolving critical incidents, implementing observability, improving resiliency, and planning disaster recovery. The leader also drives GenAI adoption, stakeholder alignment, security, governance, cost optimization, and engineering best practices across technology teams.
Top Skills:
Agentic AiAmazon CloudwatchAWSCi/CdGenerative AiHarnessInfrastructure As CodeJfrogKubernetesNew RelicTerraform Hcl

Healthtech
Develop and support platform reliability practices by helping teams define customer-focused metrics, build monitoring and alerting, create Terraform modules, standardize incident response, and improve SRE adoption. The role supports 24/7 production environments, participates in Agile/Scrum ceremonies, and collaborates with engineering, security, compliance, product, and IT teams.
Top Skills:
AWSAzureBashCi/CdContainer OrchestrationDockerGCPGrafanaKibanaPrometheusPythonTerraform

Digital Media • Information Technology • News + Entertainment
Lead Data SRE responsible for ensuring reliability, scalability, and performance of data platforms. Design monitoring, automate operations, optimize performance, respond to incidents, plan capacity, enforce security/compliance, document systems, and collaborate with engineering, data science, and product teams.
Top Skills:
AerospikeAnsibleApache KafkaAWSAws S3AzureCassandraContainerizationDockerElk StackGCPGoGrafanaHadoopHdfsJavaKubernetesMicroservicesMySQLNoSQLPostgresPrometheusPythonScalaSnowflakeSparkTerraform
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free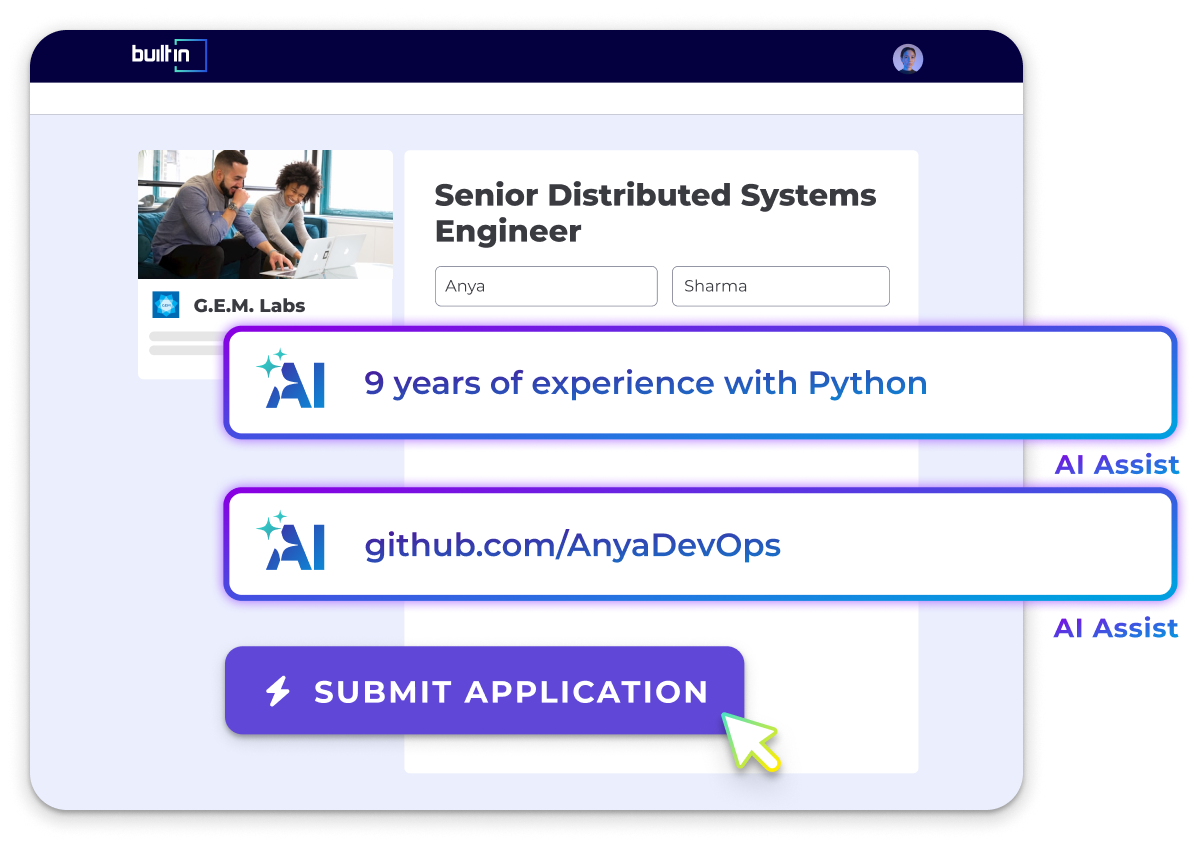

Healthtech • Pharmaceutical
Own the reliability, availability, performance, observability, and security of Ophelia’s GCP telehealth platform. Define SLOs, improve monitoring and incident response, expand Terraform infrastructure, strengthen CI/CD, manage disaster recovery, and address latency and Cloud Run performance. Lead on-call maturity, HIPAA/SOC 2 infrastructure controls, and reliability education for engineers. Use AI-assisted tools for automation and incident triage while partnering with technical and non-technical stakeholders.
Top Skills:
BigQueryClaudeCloud RunFirebaseFirebase AuthenticationFirebase HostingFirestoreGeminiGithub ActionsGoogle Cloud OperationsGoogle Cloud PlatformIamNode.jsPagerdutyPythonReactShell ScriptingSQLTerraformTypescript

Artificial Intelligence • Big Data • Healthtech • Biotech • Pharmaceutical
Build and operate reliable cloud infrastructure, developer platforms, CI/CD systems, observability, and production workloads. Support applications, data systems, ML pipelines, and AI workloads across development, staging, and production. Establish SLOs, monitoring, incident response, automation, infrastructure-as-code practices, and operational standards. Collaborate with Product Engineering, Data Engineering, Data Science, and Security while mentoring engineers and participating in support rotations.
Top Skills:
AWSAzureCi/CdDockerGCPGitInfrastructure As CodeKubernetesOpentofuPythonSnowflakeTerraformTerragruntVercelVirtual Networking

Artificial Intelligence • Blockchain • Software • Cryptocurrency
Operate and improve large-scale AI compute, storage, and networking infrastructure in 24x7 environments. Responsibilities include capacity planning, performance analysis, patching, upgrades, firmware management, automation, incident response, documentation, disaster recovery testing, and L3 escalation support. The role also requires customer collaboration, operations enablement, and participation in an on-call rotation while supporting OpenStack or similar private cloud platforms.
Top Skills:
Automation ScriptingBgpDatabase TechnologiesInfrastructure As CodeLoad BalancingNsxOpenstackOspfRoutingSoftware-Defined NetworkingSwitchingVlanVxlan
Information Technology • Consulting • Defense
Operate and improve reliable Azure Government platforms supporting AI applications, OIGChat, and enterprise data systems. Responsibilities include monitoring, observability, incident response, root-cause analysis, performance and cost optimization, capacity planning, disaster recovery, high availability, deployment readiness, and operational documentation. The role also supports Azure Databricks, data pipelines, AI model endpoints, secure government cloud environments, and mission-critical federal operations.
Top Skills:
Ai/Ml PlatformsApplication InsightsAws GovcloudAzureAzure DatabricksAzure MonitorAzure OpenaiAzure SynapseDevOpsElk StackGrafanaLog AnalyticsPaasPrometheusSre

Security
Own infrastructure reliability across GCP, Kubernetes, PostgreSQL, and hundreds of cloud projects. Build automation and software that eliminate toil, reduce manual on-call work, address latency and reliability trade-offs, and provide system health visibility. Lead infrastructure projects, define service-level objectives with product teams, improve reliability practices, and develop production systems for agent-first applications.
Top Skills:
GCPKubernetesPostgres

Artificial Intelligence • Legal Tech • Software
The Staff Site Reliability Engineer will architect reliability strategies, manage observability, and drive operational excellence across teams, particularly in large-scale production systems.
Top Skills:
Cloud InfrastructureDistributed Systems

Artificial Intelligence • Machine Learning • Software • Analytics
Leads and builds Infinia’s Release Engineering, DevOps, SecDevOps, and SRE functions. Owns release pipelines, CI/CD automation, infrastructure as code, security tooling, reliability standards, observability, incident response, capacity planning, and scaling. Establishes SLOs, SLIs, error budgets, and operational practices while building globally distributed engineering teams. Partners with product, QA, security, and executive leadership to communicate roadmaps, risks, and technical tradeoffs.
Top Skills:
AnsibleCi/CdDastDependency ScanningDockerGithub ActionsGitlab CiGrafanaJenkinsKubernetesOpentelemetryPrometheusPulumiSastSecrets ManagementTektonTerraform
Aerospace • Other
Operate and improve SpaceX’s high-performance computing platform, including Linux systems, infrastructure as code, storage, configuration, observability, and user-facing services. Automate toil, manage node lifecycles and resources, support incident response and on-call operations, conduct capacity planning, and collaborate with HPC systems engineers and internal users to deliver reliable, maintainable infrastructure.
Top Skills:
AnsibleApptainerContinuous DeploymentContinuous IntegrationCudaDockerGitGpu ComputingGrafanaInfrastructure As CodeKubernetesLinuxLsfNagiosPbsPodmanPrometheusPuppetPythonPyTorchSingularitySlurmTensorFlowTerraformVast

Cloud • Fintech • Gaming • Social Media
Supports deployment, configuration, maintenance, and troubleshooting of AI infrastructure, including servers, storage, networking, firmware, Kubernetes, and Slurm environments. Assists with hardware diagnostics, customer environment delivery, incident resolution, documentation, and operational support in secure environments while collaborating with engineering teams.
Top Skills:
BashElkGrafanaKubernetesLinuxPrometheusPythonSlurm

Cloud • Fintech • HR Tech
Build and maintain scalable, secure Kubernetes platforms for Workday Federal Analytics. Develop infrastructure automation, CI/CD pipelines, observability, and deployment solutions using Terraform and Argo CD. Support high availability, troubleshooting, security compliance, documentation, and collaboration across engineering teams. Participate in production on-call operations and help establish reliable analytics services for GovCloud environments.
Top Skills:
SparkArgo CdAWSDockerGoGrafanaKubernetesPrometheusPythonTerraform
Cloud • Fintech • HR Tech
Build and maintain reliable Kubernetes-based platforms for Workday Federal Analytics. Responsibilities include infrastructure automation, CI/CD, observability, monitoring, security, compliance, troubleshooting, and production on-call support. The role uses Terraform, Argo CD, AWS, and programming languages such as Go or Python, while collaborating with engineering teams to support secure, scalable GovCloud deployments.
Top Skills:
SparkArgo CdAWSCi/CdDockerGoGrafanaKubernetesPrometheusPythonTerraform
Aerospace • Hardware • Analytics • Defense
Own the reliability, scalability, and performance of production systems. Design observability, monitoring, alerting, and automation solutions using AWS, Kubernetes, Datadog, and related tools. Define and operate SLIs, SLOs, SLAs, and error budgets; lead incident response and blameless post-incident reviews; improve on-call practices; partner with engineering teams to embed reliability into development; and mentor engineers on SRE principles.
Top Skills:
AWSCi/CdDatabricksDatadogDockerFivetranGithub ActionsGitlab CiGrafanaHolisticsJenkinsKubernetesLgtm StackLokiMicroservicesMimirPrometheusPythonTempoTerraform

Fintech
The Site Reliability Engineer will manage, monitor, scale, and optimize Kubernetes clusters and cloud infrastructure. Responsibilities include maintaining Helm charts, deploying Docker-based microservices, managing AWS/Azure/GCP infrastructure through Infrastructure as Code, implementing monitoring and incident response, automating operational processes, and ensuring security and compliance. The role collaborates with development and operations teams to deliver reliable, scalable infrastructure and data-driven AI solutions.
Top Skills:
AgileAmazon S3AnsibleApache MesosAWSAzureCC++CephCloudFormationDockerGoogle Cloud PlatformHdfsHelmInfrastructure As CodeJavaJavaScriptJenkinsKubernetesLinuxNfsPostgresPythonRubyScrumTerraformYarn

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies Hiring Site Reliability Engineers
See All






Popular Job Searches
All Software Engineer Jobs
.NET Developer Jobs
Aerospace Thermal Engineering Jobs
AI Engineer Jobs
Android Developer Jobs
Automation Engineer Jobs
Backend Developer Jobs
Blockchain Developer Jobs
C# Jobs
C++ Jobs
Cloud Architect Jobs
Cloud Engineer Jobs
Design Engineer Jobs
DevOps Engineer Jobs
Director Of Engineering Jobs
Electrical Engineering Jobs
Embedded Software Engineer Jobs
Engineering Jobs
Engineering Manager Jobs
Environmental Engineering Jobs
Field Engineer Jobs
Front End Developer Jobs
Full Stack Developer Jobs
Game Developer Jobs
Golang Jobs
Hardware Engineer Jobs
Industrial Engineering Jobs
iOS Developer Jobs
Java Developer Jobs
Javascript Developer Jobs
Linux Jobs
Manufacturing Engineer Jobs
Mechanical Engineering Jobs
Network Engineer Jobs
PHP Developer Jobs
Process Engineer Jobs
Project Engineer Jobs
Prompt Engineering Jobs
Python Jobs
QA Jobs
Robotics Engineer Jobs
Ruby on Rails Jobs
Salesforce Administrator Jobs
Salesforce Developer Jobs
Scala Jobs
Sharepoint Developer Jobs
Site Reliability Engineer Jobs
Software Engineering Manager Jobs
Solutions Architect Jobs
SQL Developer Jobs
Structural Engineer Jobs
System Engineer Jobs
Test Engineer Jobs
Web Developer Jobs
All Filters
Total selected ()
No Results
No Results
