

Maximum of 25 job preferences reached.
Top Site Reliability Engineer Jobs

Artificial Intelligence • Big Data • Cloud • Information Technology
Own end-to-end client support, troubleshoot production issues, monitor cloud environments, respond to incidents, automate operational tasks, and lead postmortems. Develop and execute manual and automated QA tests, maintain regression suites, integrate testing into CI/CD, and validate AI-powered features. Build documentation, collaborate with engineering and product teams, and improve reliability for regulated-industry clients.
Top Skills:
Ai/LlmAWSAzureAzure MonitorBashCi/CdCloudwatchKubernetesPlaywrightPowershellPythonSQLTerraform
One Month AgoSaved
Easy Apply
Easy Apply
Cloud • Security • Software • Cybersecurity • Automation
Provide technical direction for GitLab Dedicated, a managed single-tenant SaaS platform. Lead architecture and transformation across resilience, failover, tenant orchestration, change management, automation, and platform integrations. Identify systemic reliability and scalability risks, establish reusable platform patterns, strengthen service ownership, and guide cross-team technical decisions. Mentor senior engineers and advance engineering excellence across the organization.
Top Skills:
Cloud InfrastructureDevsecopsDistributed SystemsGoInfrastructure As CodeObservabilityPythonRuby
Cloud • Information Technology
Architects, deploys, and operates secure, highly available Kubernetes and cloud infrastructure for AI/ML workloads. Builds Terraform-based automation, GitOps workflows, CI/CD pipelines, observability, and security controls across cloud environments. Serves as a customer-facing technical SME, supporting solution architecture, technical scoping, demonstrations, documentation, and client handoffs. Participates in on-call operations, troubleshooting, root-cause analysis, and post-mortems.
Top Skills:
AWSAws GovcloudAzure GovernmentBashCi/CdCis BenchmarksDatadogDockerFedrampGitopsGoGCPGrafanaKubernetesAzureNistPod SecurityPrometheusPythonRbacSplunkTerraform

Fintech • Financial Services
Support enterprise multi-cloud operations across Azure, GCP, AWS, and OCI. Manage Kubernetes, Linux, databases, infrastructure provisioning, observability, vulnerability remediation, incidents, releases, capacity, resiliency, governance, and AI/ML platform services. Automate operational processes with Terraform and scripting languages, maintain documentation, and participate in on-call rotations.
Top Skills:
AksAWSAzureAzure Sql Managed InstanceBashGoogle Cloud PlatformKubernetesLinuxModelopsOracle Cloud InfrastructureOracle DatabasePowershellPythonQualysSplunkTerraformWiz
Fintech • Financial Services
Supports multi-cloud operations across Azure, GCP, AWS, and OCI, including Kubernetes, Linux, databases, infrastructure as code, observability, vulnerability remediation, incident response, releases, capacity management, governance, resilience, and AI/ML platform operations. Automates operational processes using Terraform and scripting languages, maintains documentation, and participates in on-call rotations.
Top Skills:
AksAmazon Web ServicesAzure Sql Managed InstanceBashGoogle Cloud PlatformKubernetesLinuxAzureModelopsOracleOracle Cloud InfrastructurePowershellPythonQualysSplunkTerraformWiz
Fintech • Financial Services
Operate and support BNY’s multi-cloud environment, primarily Azure and GCP, with additional AWS and OCI responsibilities. Manage cloud provisioning, Kubernetes and Linux workloads, databases, observability, vulnerability remediation, incidents, releases, capacity, governance, resilience, and disaster recovery. Automate operational processes using Terraform and scripting languages, maintain runbooks, and participate in on-call rotations while supporting AI/ML infrastructure and ModelOps services.
Top Skills:
AksAWSAzureAzure Sql Managed InstanceBashGoogle Cloud PlatformKubernetesLinuxOracle Cloud InfrastructureOracle DatabasePowershellPythonQualysSplunkTerraformWiz

Digital Media • Gaming • Music • Sports • Virtual Reality
Designs, deploys, automates, and maintains resilient hybrid infrastructure and observability platforms. Responsibilities include monitoring and alerting, application telemetry, infrastructure deployment, incident response, documentation, training, cross-functional collaboration, and technical mentorship. The role supports Windows, Linux, AWS, Azure, Kubernetes, and on-premises environments while improving system reliability through automation, troubleshooting, and continuous learning.
Top Skills:
Amazon Ec2Amazon EksAnsibleAWSAzureBashDockerGrafana LgtmGraphQLHyper-VJavaScriptKubernetesLinuxLogqlPowershellPromqlPulumiTerraformTraceqlTypescriptVMwareWindows Server

Digital Media • Gaming • News + Entertainment • Sports
Lead multiple SRE teams to ensure reliability, scalability, and security across cloud and on-prem systems. Drive observability, automation, CI/CD, infrastructure-as-code, and operational excellence; set strategy, manage resources, mentor leaders, and influence stakeholders for commerce platforms.
Top Skills:
Ai/MlAnsibleAWSAzureCi/CdCloudFormationGCPGitlabHarnessInfrastructure-As-CodeKubernetesServerlessTerraform
Healthtech • Software
Own the reliability, security, availability, backups, disaster recovery, deployments, and hosting of Windows- and Linux-based production environments. Manage servers, networking, access controls, monitoring, vulnerability remediation, high availability, recovery testing, CI/CD support, infrastructure upgrades, and deployment automation. Evaluate cloud and hybrid-cloud modernization strategies while coordinating incidents, vendors, and technology lifecycle activities.
Top Skills:
.NetAWSAzureCi/CdDnsFirewallsGCPIisIso 27001JavaScriptLinuxMicrosoft TfsSQLTcp/IpVpnWindows Server

Cloud • Fintech • HR Tech
Operate and improve service reliability by partnering with development and infrastructure teams. Provide on-call support, troubleshoot distributed systems and cloud infrastructure, implement observability, perform capacity planning and performance optimization, automate operational tasks and infrastructure provisioning, and lead incident management and post-incident analysis.

Information Technology
Lead SRE responsible for reliability, performance, scalability, observability, automation, and incident response across cloud and air-gapped environments. Drive RCA, capacity planning, reliability standards, and tooling while partnering with DevOps, infrastructure, and security teams to reduce operational risk and support highly available services.
Top Skills:
AWSElk StackGrafanaKubernetesLinuxPrometheusPythonTerraformTerragrunt

Artificial Intelligence • Information Technology • Software • Consulting
Leads site reliability engineering for mission-critical production systems. Drives automation, performance optimization, incident response, observability, capacity planning, and scalable self-healing infrastructure. Builds internal tooling, applies SRE principles across cloud platforms, microservices, and Kubernetes environments, and collaborates with technical and non-technical stakeholders to improve operational excellence.
Top Skills:
AWSAzureDynatraceElk StackGCPKubernetesMicroservicesPythonSplunk
New
Track Smarter, Apply Better.
Ditch the spreadsheets. Organize your job search with our freeApplication Tracker.
Use For Free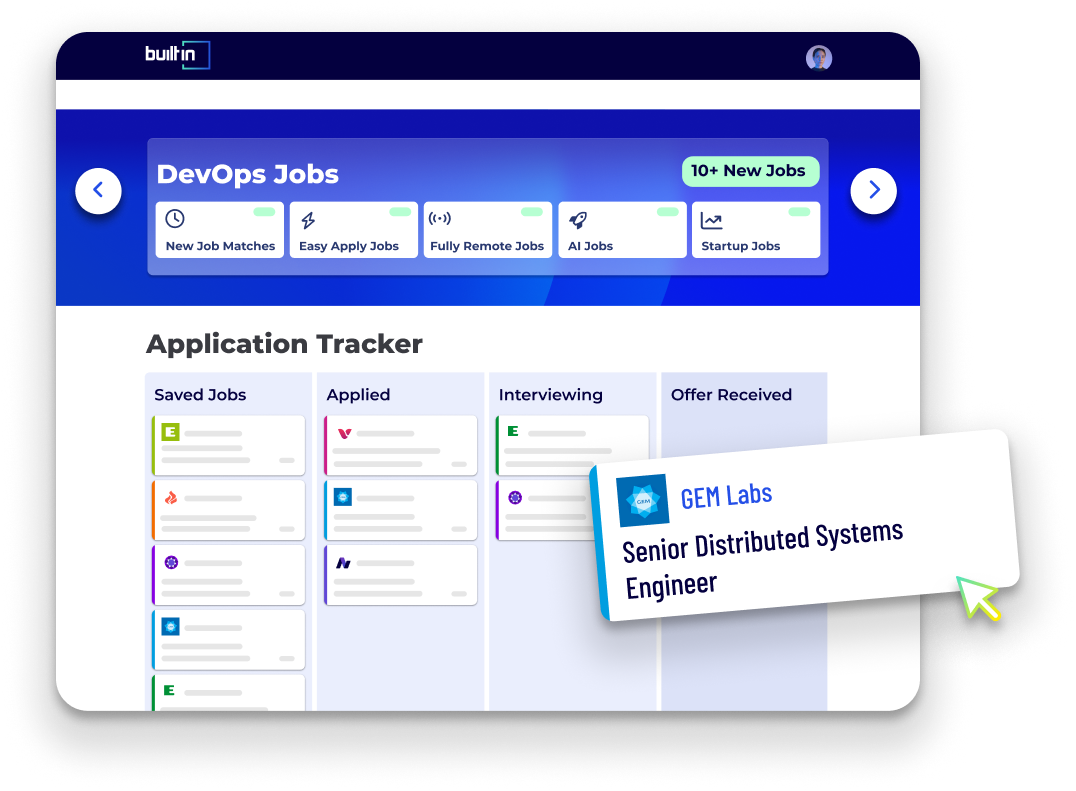
Cloud • Information Technology • Security • Software • Cybersecurity
Own reliability and performance for Zscaler’s high-scale bare-metal and cloud infrastructure. Develop production automation with Python, Go, Bash, and Ansible; manage Linux/BSD fleets and Kubernetes; lead incident response and low-level systems troubleshooting; build observability with Prometheus and OpenTelemetry; enforce SLOs, conduct performance tuning, and improve deployment safety across global infrastructure.
Top Skills:
Ai/MlAiopsAnsibleBashBsdCi/CdDnsFreebsdGdbGoIostatKubernetesLinuxLsofOpentelemetryPrometheusPythonStraceTcp/IpTcpdumpTemporalTlsVmstat

Software • Quantum Computing • Metaverse • Infrastructure as a Service (IaaS)
Designs, develops, and operates reliable, scalable software for Microsoft Office 365 government cloud environments. Responsibilities include distributed systems engineering, telemetry analysis, monitoring, automation, deployment, incident response, performance optimization, capacity planning, and root-cause analysis. The engineer participates in on-call rotations, code and design reviews, and collaborates with product engineering and program management teams to improve availability, security, reliability, and operational efficiency.
Top Skills:
AlertingAutomationCapacity PlanningCloud InfrastructureCloud TechnologiesDistributed SystemsMonitoringOffice 365Software DevelopmentTelemetry
Reposted One Month AgoSaved
Easy Apply
Easy Apply
Cloud • Information Technology • Security • Software • Cybersecurity
As a Staff Site Reliability Engineer, you'll oversee Zscaler production data center services, optimize code, and ensure cloud service availability and performance. Collaborate with cross-functional teams to improve processes and resolve escalated issues.
Top Skills:
BashDnsFirewallsGrafanaHTTPIcmpLoad BalancingNagiosOsi ModelPrometheusPythonTcp/Ip
Information Technology
Designs and maintains reliable, scalable AWS infrastructure for a mission-critical platform. Builds infrastructure automation with CloudFormation, monitors system health, troubleshoots production and containerized distributed systems, and improves resilience through CI/CD, observability, incident response, and operational best practices. Collaborates with development teams to reduce manual effort and strengthen service delivery across Linux, Docker, Kubernetes, and related environments.
Top Skills:
Amazon CloudwatchAmazon RdsAWSBashCi/CdCloudFormationDockerDocker SwarmGitlabKubernetesLinuxOpensearchPythonUnix
Professional Services • Consulting
Own the reliability, security, and delivery of a production cloud platform. Responsibilities include improving infrastructure and deployment processes, managing service-level objectives, incident response, observability, disaster recovery, Kubernetes on AWS, GitOps delivery, compliance evidence, and infrastructure security. The role identifies gaps, develops remediation plans, and drives measurable improvements in uptime and deployment speed.
Top Skills:
AWSDisaster RecoveryGitopsIdentity And Access ManagementKubernetesNetwork PolicyObservabilityPythonSecrets ManagementService MeshTypescript
Healthtech • Software
Staff Site Reliability Engineer responsible for setting infrastructure direction and owning availability, stability, scalability, observability, disaster recovery, and cloud costs for a SaaS platform. The role involves multi-cloud architecture, managed Kubernetes, infrastructure automation, GitOps delivery, incident response, business continuity, technical evaluations, platform migrations, and mentoring engineers. This is a fully remote U.S.-based position with an on-call rotation.
Top Skills:
Cloud ComputingGitopsInfrastructure As CodeKubernetesObservabilityScripting
Aerospace • Hardware • Information Technology • Security • Software • Cybersecurity • Defense
Deploys, monitors, automates, and supports large-scale distributed IaaS, PaaS, and SaaS environments. Responsibilities include infrastructure engineering, service lifecycle management, performance monitoring, incident resolution, continuous service delivery, automation, and cross-functional collaboration. The role requires Juniper networking, cloud and virtualization experience, storage technologies, Ansible or Helm, and the ability to obtain Secret clearance and Security+ certification.
Top Skills:
AnsibleAzure StackCephHelmIaasJdfsJuniperKubernetesNfsOpenstackPaasS3SaaSTerraformVMware
Aerospace • Hardware • Information Technology • Security • Software • Cybersecurity • Defense
Principal Networking Site Reliability Engineer responsible for deploying, monitoring, automating, and supporting large-scale distributed infrastructure and software applications. The role focuses on SRE practices, cloud service lifecycle management, performance monitoring, fault-tolerant systems, infrastructure automation, networking, storage, virtualization, and cross-functional collaboration. Candidates must be able to obtain a Secret clearance and be eligible for TS/SCI clearance.
Top Skills:
AnsibleAzure StackCephHelm ChartsIaasJdfsJuniper NetworkingKubernetesNfsObject Storage (S3)OpenstackPaasSaaSSecurity+TerraformVMware
Aerospace • Hardware • Information Technology • Security • Software • Cybersecurity • Defense
Deploy, monitor, automate, and support large-scale distributed infrastructure and software applications. Build reliable IaaS, PaaS, and SaaS services; implement observability and performance monitoring; scale systems through automation; resolve complex service issues; and collaborate with SRE, DevOps, security, and IT operations teams. The role requires networking, cloud, storage, virtualization, containerization, infrastructure-as-code, and security expertise, along with eligibility for Secret and future TS/SCI clearance.
Top Skills:
AnsibleAzure StackCephHelmIaasJdfsJuniperKubernetesNfsOpenstackPaasS3SaaSSecurity+TerraformVMware
Aerospace • Hardware • Information Technology • Security • Software • Cybersecurity • Defense
Deploys, monitors, automates, and supports large-scale distributed infrastructure and applications across IaaS, PaaS, and SaaS environments. Responsibilities include implementing SRE practices, scaling systems through automation, monitoring production performance, resolving complex service issues, and providing operational engineering support. The role collaborates with Core Services, DevOps, Security, and IT Operations teams and requires networking, cloud, storage, virtualization, infrastructure-as-code, and site reliability expertise.
Top Skills:
Amazon S3AnsibleAzure StackCephHelmIaasInfrastructure As CodeJdfsJuniperKubernetesNfsObject StorageOpenstackPaasSaaSSecurity+TerraformVMware

Artificial Intelligence • Fintech • Software • Financial Services
Own and define Hanover Park’s infrastructure strategy as the company scales. Responsibilities include AWS, PostgreSQL, Supabase, Vercel, and Trigger.dev infrastructure; CI/CD; observability; security; backups; performance; incident response; SLOs and SLIs; and production reliability. The role also requires application coding, architecture decisions, automation, mentoring, and establishing platform engineering practices from the ground up.
Top Skills:
AlertingAWSCi/CdLoggingMonitoringObservabilityPostgresSecrets ManagementSlisSlosSoc 2SupabaseTerraformTracingTrigger.DevTypescriptVercel
Artificial Intelligence • Cloud • HR Tech • Information Technology • Productivity • Software • Automation
Maintain and improve the reliability, scalability, performance, and operability of ServiceNow’s federal cloud infrastructure. Resolve infrastructure issues, automate repetitive work, develop monitoring solutions, reduce incidents and MTTR, and lead reliability initiatives across hardware, networking, systems, applications, and cloud technologies. This third-shift role supports government customers on a Sunday-Wednesday, 10-hour schedule with no on-call rotation.
Top Skills:
AgileAutomationAWSAzureCi/CdDevOpsIp AddressingJavaScriptLinuxMonitoringMySQLNetworkingObservabilityPostgresPythonRoutingRubyScriptingServicenow Platform

Healthtech • Software
Administer and improve reliable, scalable infrastructure across on-premises and Azure/AWS environments. Automate provisioning and operational processes with Terraform, Ansible, and scripting. Manage Linux systems, VMware, storage, hardware, networking, security, monitoring, log aggregation, performance tuning, backups, and disaster recovery. Collaborate with development and IT teams to enhance system uptime, security, and operational excellence. Kubernetes, Kafka, IAM, and Active Directory experience are beneficial.
Top Skills:
AnsibleAWSAzureBashDatadogDebianDell HardwareDnsGrafanaHpe NimbleIscsiKafkaKubernetesLinuxNagiosPerlPrometheusPythonSplunkTcp/IpTerraformUbuntuVMwareWindows Active Directory

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies Hiring Site Reliability Engineers
See All






Popular Job Searches
All Software Engineer Jobs
.NET Developer Jobs
Aerospace Thermal Engineering Jobs
AI Engineer Jobs
Android Developer Jobs
Automation Engineer Jobs
Backend Developer Jobs
Blockchain Developer Jobs
C# Jobs
C++ Jobs
Cloud Architect Jobs
Cloud Engineer Jobs
Design Engineer Jobs
DevOps Engineer Jobs
Director Of Engineering Jobs
Electrical Engineering Jobs
Embedded Software Engineer Jobs
Engineering Jobs
Engineering Manager Jobs
Environmental Engineering Jobs
Field Engineer Jobs
Front End Developer Jobs
Full Stack Developer Jobs
Game Developer Jobs
Golang Jobs
Hardware Engineer Jobs
Industrial Engineering Jobs
iOS Developer Jobs
Java Developer Jobs
Javascript Developer Jobs
Linux Jobs
Manufacturing Engineer Jobs
Mechanical Engineering Jobs
Network Engineer Jobs
PHP Developer Jobs
Process Engineer Jobs
Project Engineer Jobs
Prompt Engineering Jobs
Python Jobs
QA Jobs
Robotics Engineer Jobs
Ruby on Rails Jobs
Salesforce Administrator Jobs
Salesforce Developer Jobs
Scala Jobs
Sharepoint Developer Jobs
Site Reliability Engineer Jobs
Software Engineering Manager Jobs
Solutions Architect Jobs
SQL Developer Jobs
Structural Engineer Jobs
System Engineer Jobs
Test Engineer Jobs
Web Developer Jobs
All Filters
Total selected ()
No Results
No Results
