

Maximum of 25 job preferences reached.
Top Site Reliability Engineer Jobs

Healthtech • Software
Administer and improve reliable, scalable infrastructure across on-premises and Azure/AWS environments. Automate provisioning and operational processes with Terraform, Ansible, and scripting. Manage Linux systems, VMware, storage, hardware, networking, security, monitoring, log aggregation, performance tuning, backups, and disaster recovery. Collaborate with development and IT teams to enhance system uptime, security, and operational excellence. Kubernetes, Kafka, IAM, and Active Directory experience are beneficial.
Top Skills:
AnsibleAWSAzureBashDatadogDebianDell HardwareDnsGrafanaHpe NimbleIscsiKafkaKubernetesLinuxNagiosPerlPrometheusPythonSplunkTcp/IpTerraformUbuntuVMwareWindows Active Directory
Healthtech
Lead the evolution of Azure infrastructure toward Kubernetes-based, microservices-oriented systems. Design reliable and scalable cloud infrastructure, observability, networking, CI/CD pipelines, and Infrastructure-as-Code. Drive incident response, cost optimization, capacity planning, performance improvements, and automation while partnering with engineering and data teams. Document best practices, mentor colleagues, and support platform strategy in a healthcare environment with PHI, access control, and audit requirements.
Top Skills:
.NetAWSAzureAzure Entra IdBashC#DatadogGCPGithub ActionsGitlab Ci/CdGrafanaHelmKubernetesPrometheusPythonTerraform

Artificial Intelligence • Cloud • Social Impact • Software • Wearables
Develop Temporal workflows and Go services to automate cloud operations, build reliable SRE platforms, participate in on-call/incident response, debug distributed systems, and enable self-service through documentation and CI/CD automation.
Top Skills:
AksApmAWSAws CloudformationAzureC#Ci/Cd PlatformsEksGo (Golang)JavaKubernetesLoggingMetricsPythonTemporalTerraform
Artificial Intelligence • Cloud • Social Impact • Software • Wearables
Build and maintain the Zero Touch Platform: develop Temporal workflows and Go services to automate cloud operations, own production systems (SLOs, on-call, incidents), debug cloud-native distributed systems, create CI/CD and IaC automation, and produce documentation to enable self-service across engineering teams.
Top Skills:
AksApmAWSAws CloudformationAzureC#Ci/CdEksGoJavaKubernetesLoggingMetricsPythonTemporalTerraform
Healthtech • Information Technology • Software • Telehealth
Designs and operates observability, automation, infrastructure as code, CI/CD, and reliability practices for distributed AWS systems. Partners with engineering teams to improve service visibility, scalability, performance, networking, deployment safety, incident response, and operational ownership. Participates in on-call rotations, leads incident response when needed, and drives blameless post-mortem remediation. Develops reusable platform standards for containers, service communication, secrets, routing, and production readiness.
Top Skills:
AWSCloudFormationDnsDockerGithub ActionsGitopsGoHttp/HttpsIngress ControllersJavaKubernetesLoad BalancersNtpOpentofuPythonReverse ProxiesRubyTcp/IpTerraformTlsWeb Application Firewalls

Cloud • Information Technology
Principal Site Reliability Engineer responsible for the availability, scalability, durability, and operational reliability of production systems. The role leads observability, incident response, SLO and error-budget practices, automation, infrastructure as code, and long-term service improvements. Responsibilities include designing monitoring and alerting frameworks, supporting Kubernetes and distributed storage environments, improving operational processes, collaborating across engineering and business teams, and mentoring reliability-focused practices. The position requires extensive experience with Linux, cloud infrastructure, containers, scripting, storage systems, and large-scale production environments.
Top Skills:
AnsibleAWSAzureBashCatchpointDockerElkError BudgetsFirehydrantGCPGoGrafanaHashicorp NomadHashicorp VaultIpvsItilJenkinsKubectlKubernetesLinuxMysqlshPrometheusPythonSlisSlosTerraformVitess

Cloud • Information Technology • Internet of Things • Professional Services • Software
Lead the architecture, operation, and reliability of Cisco ThousandEyes’ FedRAMP-compliant US GovCloud platform. Design resilient AWS services using infrastructure as code, maintain high availability and security for large-scale data streams, automate compliance controls and auditing, and collaborate with engineering and security teams on multi-region infrastructure, risk management, incident response, and technical strategy.
Top Skills:
AWSFedrampHipaaKubernetesPci-DssPythonSoc 2Terraform

11 Days AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
Build and operate security infrastructure protecting MongoDB Atlas across AWS, Azure, and GCP. Responsibilities include hardening Linux hosts and containers, implementing Kubernetes security controls, managing CSPM and workload identity platforms, deploying security controls through Terraform and other IaC tools, and creating monitoring and alerting systems. The role leads initiatives from threat modeling and architecture through implementation, rollout, and ongoing production reliability.
Top Skills:
AnsibleApparmorAWSAzureCC++CgroupsCiliumCloudFormationEbpfFalcoGatekeeperGoGoogle Cloud Platform (Gcp)KubernetesLinuxPythonRbacRustSeccompSelinuxTerraformTetragon
Financial Services
Lead site reliability engineering for enterprise infrastructure platforms. Build automated, self-healing systems; define and operationalize SLIs, SLOs, observability, and actionable alerting; own production services, incidents, postmortems, security, performance, and cost. Mentor engineers, lead resiliency reviews, reduce toil, and apply validated enterprise AI capabilities to incident response, SDLC workflows, and operational readiness while maintaining security, traceability, and reliability controls.
Top Skills:
C++Ci/CdDatadogDynatraceGoGrafanaJavaKubernetesPrometheusPythonRustSplunkTerraform
Financial Services
The Site Reliability Engineer II delivers reliable application and infrastructure services, manages incidents and root-cause analysis, defines SLOs and SLIs, and maintains monitoring, alerting, and observability. The role designs Dynatrace instrumentation, supports production environments, and improves reliability through automation and AI-assisted operational analysis. Responsibilities include microservices engineering, cloud and on-premises infrastructure, CI/CD, databases, distributed caching, event-driven systems, and scripting.
Top Skills:
Apache KafkaBashCi/CdDistributed TracingDnsDockerDynatraceGemfireGeneosGeodeJavaJenkinsKubernetesLiquibaseLoad BalancingMicroservicesNode.jsOn-Premises InfrastructureOraclePowershellPublic CloudPythonSplunkSpring BootSQLTcp/IpVpn

AdTech • Digital Media • Marketing Tech
Own the reliability, performance, and scalability of Vue 3 applications, headless WordPress platforms, and advertising technology infrastructure. Responsibilities include managing Cloudflare CDN and Workers, GCP services, Terraform, CI/CD pipelines, Prebid.js monetization, OpenTelemetry monitoring, Core Web Vitals, and incident post-mortems. The role also leads engineering initiatives and supports performance-focused team practices.
Top Skills:
Cloud RunCloudflare CdnCloudflare WafCloudflare WorkersComposition ApiGithub ActionsGitlab CiGkeGoogle Ad ManagerGoogle Cloud PlatformGraphQLLinuxOpentelemetryPrebid.JsTerraformViteVue 3WordpressWp Rest Api

Robotics
Own and scale cloud infrastructure supporting machine learning and robotics teams. Design reliable distributed systems, build observability across monitoring, logging, and tracing, implement infrastructure as code, improve security and incident response, and optimize performance and cloud costs across AWS, GCP, and Azure.
Top Skills:
AWSAzureDatadogGCPKubernetesPrometheusSplunkTerraform
New
Track Smarter, Apply Better.
Ditch the spreadsheets. Organize your job search with our freeApplication Tracker.
Use For Free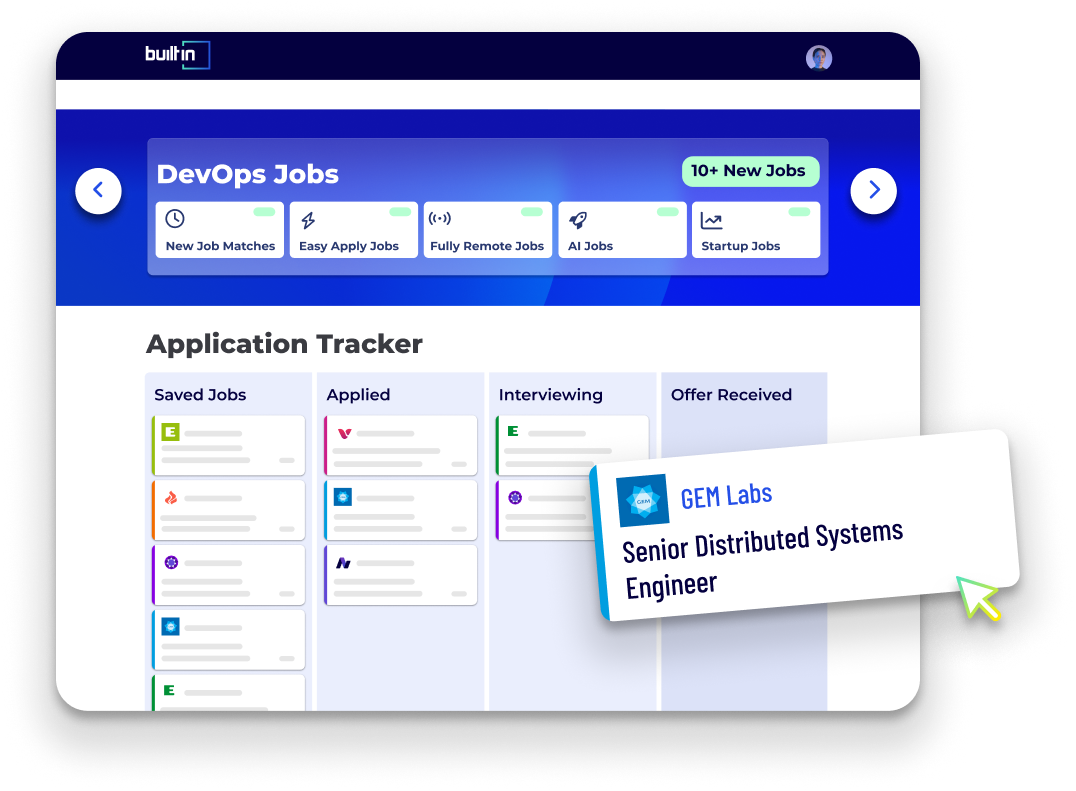

Computer Vision • Software
Build and maintain CI/CD pipelines, deployment automation, and cloud infrastructure across Azure and AWS. Manage observability with Datadog or Dynatrace, improve incident response and MTTR, provision infrastructure with Terraform, and develop automation scripts using Python, Bash, or PowerShell. Collaborate across VA engineering programs, improve platform stability, mentor junior engineers, and establish DevOps standards in a remote Agile environment.
Top Skills:
AgileAWSAzureBashCi/CdDatadogDynatraceGithub EnterprisePowershellPythonTerraformVa PlatformVa.Gov

Artificial Intelligence • Automotive • Semiconductor
Build, standardize, and operate compute and software infrastructure for AI and HPC validation labs. Responsibilities include cluster provisioning, Linux images, drivers, Kubernetes or Slurm orchestration, benchmark harnesses, workload libraries, observability, dashboards, incident response, root-cause analysis, and automation. The role partners with architecture and performance teams to mirror customer deployments and support repeatable validation across AI, networking, memory, and DPU use cases.
Top Skills:
AnsibleBeegfsCC++CephCkaGpfsKubernetesLinuxLustreMlperfNemoPythonPytorch DdpPytorch FsdpRocmSlurmTclTerraformWindows
Artificial Intelligence • Information Technology • Consulting • Cybersecurity
Support reliable and secure systems for a federal government client through site reliability and DevOps practices. Responsibilities involve troubleshooting large datasets, managing databases, Azure and Azure Function Apps, CI/CD pipelines, Git, containerization, virtualization, security compliance, vulnerability scanning, and secure APIs or data handling. The role also includes periodic 24/7 on-call support and incident mitigation across multiple systems.
Top Skills:
APIsAzureAzure DevopsAzure Function AppsBashCC++Ci/CdDockerGitGovernance ToolsJavaK9SKubernetesKustoPythonSQLVirtualizationVulnerability Scanning

Cloud • Information Technology • Consulting
Designs and maintains secure GitLab CI/CD pipelines, automates vulnerability scanning, hardens and signs Docker images, enforces software supply chain security policies, and secures Kubernetes workloads. The role investigates vulnerabilities, manages Linux security and system hardening, and supports compliance with open-source licensing and security standards. Responsibilities include container security, image optimization, dependency checks, Kubernetes configuration security, and automated remediation across the AI inference platform.
Top Skills:
Admission ControllersAlpineAnsibleBashChainguardContainer RegistriesCosignDependabotDistrolessDockerFalcoGitlab Ci/CdGrypeHelmKube-BenchKubernetesKubescapeKyvernoLinuxNetworkpoliciesOpa GatekeeperPod Security StandardsPythonRbacRenovateSbomsSigstoreSlsaTerraformTrivy
Fintech • Payments • Financial Services
Lead reliability strategy and AI-first operational workflows across critical services. Define SLOs, observability, incident response, resilience, and production-readiness standards; command major incidents; reduce on-call toil; build AI-assisted tooling for triage, investigation, runbooks, postmortems, and remediation; guide AWS architecture; and mentor engineers across product, infrastructure, and security teams.
Top Skills:
AIAmazon CloudwatchAmazon DynamodbAmazon EksAmazon RdsAmazon SqsAmazon Web ServicesApache KafkaChatgptClaude CodeCursorDatadogGithub CopilotGoIncident.IoKubernetesLlmsOpentelemetryPythonSlackTerraform

Artificial Intelligence • Healthtech • Software • Telehealth
Design, deploy, and maintain resilient AWS and Kubernetes infrastructure. Build automation, internal tools, CI/CD components, and AI-assisted operational workflows. Establish observability, SLIs, SLOs, and incident-management practices while leading postmortems and reducing toil. Ensure HIPAA compliance, review architecture, identify risks, and mentor engineers on reliability and platform best practices.
Top Skills:
Amazon Ec2Amazon EksAmazon RdsAmazon S3AWSBashDatadogGithub ActionsGoHelmHipaaKubernetesPythonTerraform
Aerospace • Healthtech • Logistics • Transportation
Own the reliability of backend, data, and infrastructure systems supporting live autonomous drone operations. Define service-level objectives, improve monitoring and observability, automate infrastructure with infrastructure-as-code and CI/CD, and lead incident response and post-incident reviews. Operate AWS, Kubernetes, databases, messaging systems, and multi-AZ infrastructure while collaborating with cloud, software, operations, and safety teams.
Top Skills:
AWSCi/CdDockerGrafanaGruntworkInfrastructure As CodeKafkaKubernetesMqttPostgresPrometheusTerraformTerragrunt

AdTech • Marketing Tech
Own production stability, observability, incident response, and reliability for a mission-critical GCP platform. Diagnose distributed-system issues, perform root cause analysis, implement Python fixes, improve monitoring and automation, maintain runbooks, and reduce operational toil. Provide technical leadership to an L2+ support squad while partnering with Product, Engineering, and QA on operational risk, releases, and technical roadmap decisions.
Top Skills:
BashBigQueryCloud FunctionsCloud LoggingCloud MonitoringCloud SqlCompute EngineDockerError ReportingFirestoreGoogle Cloud PlatformGoogle Kubernetes EngineIamKubernetesMySQLPostgresPrometheusPromqlPub/SubPythonTerraformVpc Networking

Reposted 7 Days AgoSaved
Financial Services
Lead reliability and observability initiatives across enterprise applications. Implement monitoring (Splunk, Grafana, Dynatrace, ITSI), define SLIs/SLOs, drive incident response and RCA, build automation and AI-assisted self-healing, partner with engineering/cloud/security for resiliency and performance.
Top Skills:
Amazon QAWSDynatraceGoGrafanaItsiJavaKiroLinuxPythonSplunkUnix

Artificial Intelligence • Big Data • Healthtech • Information Technology • Machine Learning • Software • Analytics
Lead SRE practices for highly available cloud-native platforms across AWS, Azure, and Kubernetes. Build observability, dashboards, alerting, infrastructure automation, CI/CD, GitOps, and self-healing capabilities. Lead incident response, root cause analysis, and remediation while improving reliability, scalability, and operational excellence. Partner with engineering, architecture, security, and platform teams, drive AI-enabled operations, and mentor engineers on SRE and cloud-native best practices.
Top Skills:
AksArgocdAWSAws ApmAzureAzure DevopsBashDatadogDynatraceEksFluxGCPGithub ActionsGitopsGkeGrafanaIamJenkinsKubernetesOpentelemetryPowershellPrometheusPythonSplunkTerraform
Cloud • Information Technology • Internet of Things • Professional Services • Software
Provides technical leadership for reliability, scalability, and operational architecture of Splunk Agent Observability. Defines reliability strategy, leads Kubernetes and deployment infrastructure initiatives, establishes SLOs and resiliency standards, automates operations, builds internal platform tooling, manages production incidents, and drives root-cause remediation. The role also influences architecture across teams, supports cloud and air-gapped deployments, partners with customers, and mentors engineers.
Top Skills:
AWSCi/CdGCPGoKubernetesMlopsPythonTerraform
Cloud • Information Technology • Internet of Things • Professional Services • Software
Build, operate, and improve Kubernetes-based infrastructure and deployment systems for cloud and air-gapped customer environments. Responsibilities include deployment lifecycle management, observability, incident response, root cause analysis, infrastructure automation, performance optimization, database tuning, and production troubleshooting. The role develops internal tooling with Python or Go, manages infrastructure with Terraform, and partners with engineering teams and customers to deliver secure, scalable, reliable architectures.
Top Skills:
AWSCi/CdGCPGoHelmKubernetesMlopsPythonTerraform
Blockchain • Fintech • Payments • Financial Services • Cryptocurrency • Web3
Designs, builds, and operates secure, highly available Kubernetes platforms and cloud infrastructure. Develops Terraform modules, backend services, automation, and CI/CD workflows while improving reliability, scalability, observability, security, and cost efficiency. Partners with engineering and product teams on distributed systems, leads incident response and postmortems, establishes SLOs and disaster-recovery practices, and mentors team members.
Top Skills:
AlertingBlue-Green DeploymentsCanary DeploymentsCi/CdDashboardsDisaster RecoveryDnsDockerError BudgetsGitopsGoHybrid CloudIamJavaScriptKubernetesLoad BalancingLogsMetricsPublic CloudPythonRoutingService NetworkingSlisSlosTerraformTracesTypescript

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies Hiring Site Reliability Engineers
See All






Popular Job Searches
All Software Engineer Jobs
.NET Developer Jobs
Aerospace Thermal Engineering Jobs
AI Engineer Jobs
Android Developer Jobs
Automation Engineer Jobs
Backend Developer Jobs
Blockchain Developer Jobs
C# Jobs
C++ Jobs
Cloud Architect Jobs
Cloud Engineer Jobs
Design Engineer Jobs
DevOps Engineer Jobs
Director Of Engineering Jobs
Electrical Engineering Jobs
Embedded Software Engineer Jobs
Engineering Jobs
Engineering Manager Jobs
Environmental Engineering Jobs
Field Engineer Jobs
Front End Developer Jobs
Full Stack Developer Jobs
Game Developer Jobs
Golang Jobs
Hardware Engineer Jobs
Industrial Engineering Jobs
iOS Developer Jobs
Java Developer Jobs
Javascript Developer Jobs
Linux Jobs
Manufacturing Engineer Jobs
Mechanical Engineering Jobs
Network Engineer Jobs
PHP Developer Jobs
Process Engineer Jobs
Project Engineer Jobs
Prompt Engineering Jobs
Python Jobs
QA Jobs
Robotics Engineer Jobs
Ruby on Rails Jobs
Salesforce Administrator Jobs
Salesforce Developer Jobs
Scala Jobs
Sharepoint Developer Jobs
Site Reliability Engineer Jobs
Software Engineering Manager Jobs
Solutions Architect Jobs
SQL Developer Jobs
Structural Engineer Jobs
System Engineer Jobs
Test Engineer Jobs
Web Developer Jobs
All Filters
Total selected ()
No Results
No Results
