

Maximum of 25 job preferences reached.
Top Data Engineer Jobs in Omaha, NE
Database
Build and maintain FinOps data pipelines, BigQuery and dbt models, cost attribution systems, forecasting and anomaly detection models, and cost-versus-revenue analytics. Identify and implement AWS and GCP savings opportunities, automate governance with Python, Terraform, and Lambda, and partner with Engineering, Finance, Product, and leadership on cloud costs, forecasting, reporting, and architecture decisions.
Top Skills:
AWSAws Cost And Usage ReportsAws Cost ExplorerAws LambdaBashBigQueryCloudzeroDbtGCPGcp Billing ReportsHexLinearNotionPulumiPythonSQLTerraformVantage

Insurance
Designs, develops, maintains, and improves software applications and business processes. Responsibilities include full lifecycle development, troubleshooting, performance and reliability improvements, CI/CD collaboration, requirements analysis, technology research, package maintenance, portfolio planning, and mentoring junior engineers. The role requires independent work, cross-functional collaboration, and strong software development, documentation, and problem-solving skills.
Top Skills:
AdoCi/CdDbtNpmNugetPower BIPythonRSnowflakeSQL Server
Healthtech • Biotech • Pharmaceutical
Designs, develops, maintains, and optimizes complex data systems, SQL/ETL processes, reporting solutions, and .NET applications supporting pharmacy benefit management. Responsibilities include database performance tuning, data warehousing, troubleshooting pharmacy claims, technical specification development, software testing, cloud integration, stakeholder collaboration, Agile participation, and mentoring. The role requires strong SQL Server, dimensional modeling, cloud database, Python, PowerShell, and healthcare data standards expertise.
Top Skills:
.NetAnsi X12AWSAws RdsAzure Sql DatabaseC#CassandraGitlabHadoopHl7JSONMicrosoft Sql ServerMongoDBNcpdpPower BIPowershellPythonRdbmsSparkSQLSsasSsisSsmsSsrsTableauVisual StudioVisualcronXML

Artificial Intelligence • Information Technology • Machine Learning • Generative AI • Big Data Analytics
Designs and optimizes scalable data platforms, architectures, and production pipelines supporting AI and machine learning. Responsibilities include Databricks Lakehouse development, batch and real-time processing, data governance, security, monitoring, performance tuning, infrastructure planning, and collaboration with DevOps, MLOps, and cross-functional teams. The role serves as the AI team’s data engineering subject matter expert and ensures reliable, secure, cost-effective data solutions.
Top Skills:
DatabricksDelta LakeDuckdbGoogle Cloud PlatformInfrastructure As CodeJSONKerasLangchainLangsmithPandasParquetPdfPostgresPysparkPythonPyTorchSQLTensorFlow

Agriculture • Industrial • Manufacturing
Designs, develops, and optimizes enterprise data pipelines and platforms using Snowflake, integrating Oracle Fusion, on-premises databases, and cloud applications. Applies data quality, governance, security, and performance practices while supporting Power BI, AI, and machine learning use cases. Partners with business and technical stakeholders, leads data migrations, translates requirements into sustainable solutions, mentors junior engineers, and guides engineering standards.
Top Skills:
Apache AirflowAzure Blob StorageAzure Data FactoryDbtOci Object StorageOracle EpmOracle ErpOracle FusionPower BIPower Bi CopilotPythonSnowflakeSnowflake CortexSQLSQL Server

Edtech
Leads the design, development, and optimization of scalable data pipelines and analytics platforms. Builds ETL/ELT workflows using Databricks and Spark, integrates and transforms source data into curated models, manages SQL Server data, and maintains documentation and lineage. Collaborates with product, analytics, and engineering teams to deliver reliable data solutions. Applies responsible AI practices and delivers projects independently within established timelines.
Top Skills:
SparkAzureDatabricksDatabricks SqlDaxGitPower BIPysparkPythonSQLSQL Server

Information Technology • Consulting
Design, build, and optimize enterprise ETL/ELT pipelines, cloud data lakes, lakehouse solutions, data models, and semantic layers across AWS and Azure. Ensure data quality, security, performance, reliability, and governance while supporting analytics, reporting, and AI initiatives. Collaborate with product, engineering, IT, and business stakeholders to translate requirements into scalable data solutions, monitor pipeline health, troubleshoot issues, and improve data architecture and practices.
Top Skills:
AWSAws BedrockAzureAzure Data FactoryAzure DevopsAzure FabricCi/CdDatabricksDmsGitGluePower BIRagRedshiftS3SparkSQLSsis

Fintech • Software • Financial Services
Own Step’s analytics data models, transformation pipelines, metric definitions, semantic layer, and data quality practices. Partner with Product, Marketing, Engineering, Risk, Growth, and Finance to establish trustworthy data foundations and enable self-service analysis. Build reusable query, visualization, and code components; apply AI-augmented workflows; and collaborate with data scientists, analysts, and platform engineers. The role requires strong SQL, modeling, pipeline, BI, communication, and independent ownership skills, with occasional travel for team onsites.
Top Skills:
Ai ToolsBigQueryCiData Observability ToolingData PipelinesDbtLookerMixpanelPythonSemantic LayerSQLTableau

Machine Learning • Software
Design, build, and operate end-to-end data pipelines and models for healthcare claims and payer data. Responsibilities include ingestion, canonical and analytical data modeling, legacy process migration, data quality, testing, CI/CD, deployment, operations, incident response, tool integration, documentation, and onboarding new data sources. The role partners across ML, product, analytics, platform, operations, and customer teams while critically evaluating AI-generated engineering work.
Top Skills:
AIAirflowAWSCi/CdCsvDatabricksDbtEdi X12Github ActionsInfrastructure As CodeMcpParquetPythonScalaSftpSnowflakeSpark SqlSQL

Software
Own Mux’s end-to-end data platform, including ingestion, Snowflake administration, dbt transformations, orchestration, data quality, observability, and reverse ETL. Build semantic models supporting AI agents, establish governance and reliability standards, and partner with Engineering, Finance, Product, and GTM. Use AI coding tools to develop and maintain pipelines while validating output quality. The role requires strong SQL, Python, data modeling, cloud warehouse administration, and production data engineering experience.
Top Skills:
AirbyteAWSBigQueryClaude CodeCubeCursorDatabricksDbtDbt Semantic LayerElementaryFivetranGCPHubspotKafkaKinesisLlm AgentsLookmlMcp ServersMetaplaneMetricflowMonte CarloNetSuiteOmniPythonRedisSalesforceSnowflakeSQL

Cloud • Fintech
Designs, builds, and optimizes scalable Databricks-based data platforms, pipelines, integrations, and reusable engineering tools. The role focuses on platform performance, reliability, cost efficiency, security, governance, automation, and cloud infrastructure. It collaborates with engineering, analytics, security, and other stakeholders on architecture, technical planning, production support, and continuous improvement. The position requires hands-on data engineering experience with Databricks, cloud services, Python, SQL, Spark, infrastructure-as-code, and CI/CD practices.
Top Skills:
Apache KafkaSparkAWSAzureCi/CdConfluentDatabricksDelta LakeGCPInfrastructure-As-CodePythonScalaSQL

Edtech
Lead the architecture and development of Penn Foster Group’s Databricks-based cloud data platform. Build scalable batch, streaming, CDC, and API pipelines using Python, SQL, Spark, and Azure; establish engineering standards, governance, observability, and CI/CD practices; develop AI-ready semantic data products; and mentor data engineers. Partner with BI, product, security, governance, and MLOps teams to support analytics, machine learning, generative AI, and self-service reporting.
Top Skills:
Adls Gen2SparkAuto LoaderBusiness ObjectsCi/CdDatabricksDatabricks GenieDatabricks JobsDatabricks ReposDatabricks WorkflowsDbtDelta LakeDelta Live TablesGenerative AiGitGreat ExpectationsInfrastructure As CodeLakeflowLakehouse MonitoringLiquid ClusteringMedallion ArchitectureAzureMicrosoft Entra IdMlflowMlopsPhotonPower BIPysparkPythonRbacSQLSql WarehousesTableauUnity Catalog
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free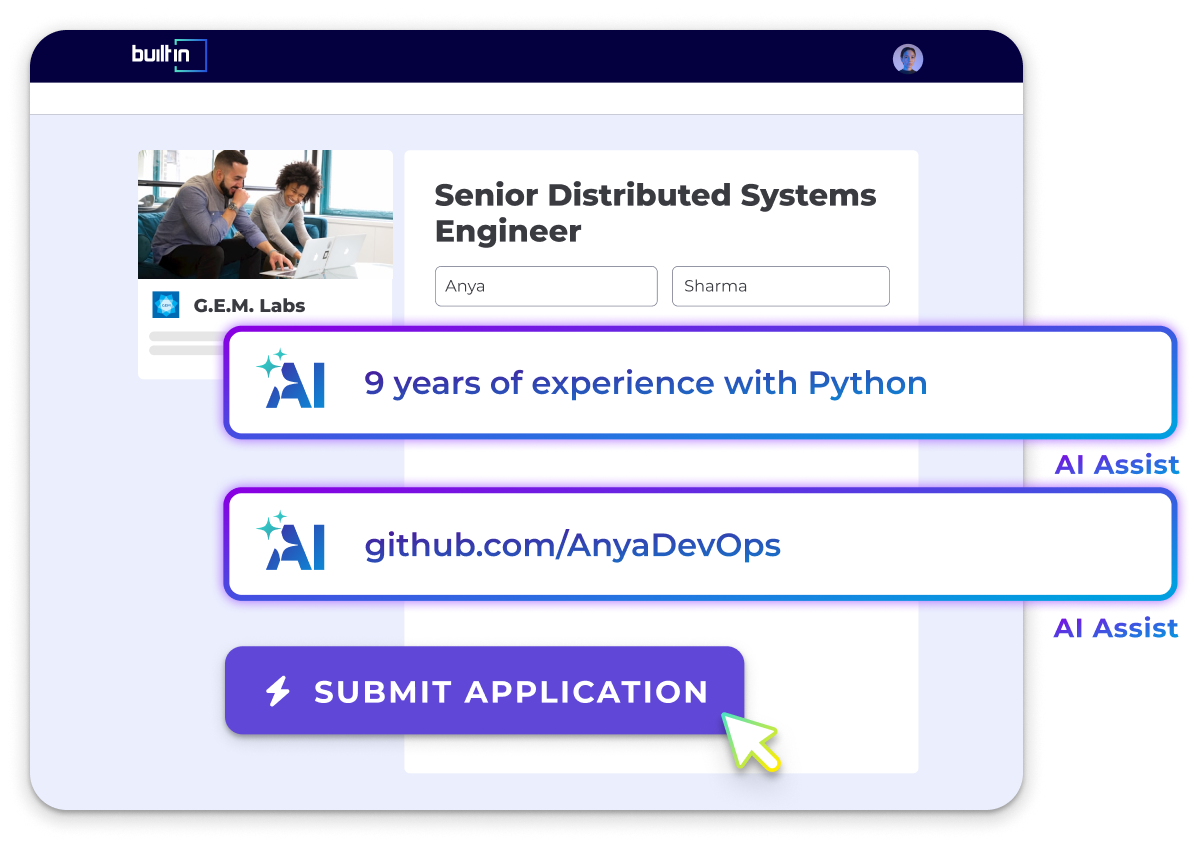
Machine Learning • Software
Own end-to-end client data migrations: reverse-engineer legacy ETL, design and build Airflow DAGs and Spark jobs, validate and reconcile data at scale, document architecture and decisions, and coordinate cross-functional teams through go-live and hypercare.
Top Skills:
Apache AirflowSparkAws S3ClaudeCursorGithub CopilotPythonSQLSQL ServerSsisT-Sql

Other
Designs and leads enterprise data pipelines and integrations across Snowflake, Oracle Fusion, on-premises databases, and cloud applications. Ensures data quality, governance, security, scalability, and performance while supporting Power BI, AI/ML, and self-service analytics. Partners with business and technical stakeholders, leads migrations, mentors engineers, optimizes data platforms, and establishes engineering best practices.
Top Skills:
Apache AirflowAzure BlobAzure Data FactoryDbtOci Object StorageOracle EpmOracle FusionPower BIPower Bi CopilotPythonSnowflakeSnowflake CortexSQLSQL Server

Big Data • HR Tech • Mobile • Software • Database
Designs, builds, deploys, and maintains scalable data pipelines, data lake systems, batch and streaming processing, MLOps frameworks, data documentation tooling, and an agentic data exploration platform. The role supports customer-facing products and enables engineering teams through reliable infrastructure, observability, data discovery, and AI capabilities.
Top Skills:
Amazon Ec2Amazon MskAmazon S3Apache AirflowApache FlinkApache IcebergApache KafkaApache ParquetSparkAWSAws GlueAws IamDelta LakeDockerKubernetesLlmsMlopsSpark Structured Streaming
Big Data • HR Tech • Mobile • Software • Database
Build and operate scalable batch and streaming data pipelines, data lake infrastructure, MLOps frameworks, data documentation systems, and an AI-assisted data exploration tool. The role focuses on reliable data ingestion, large-scale processing, workflow orchestration, observability, and infrastructure supporting customer-facing products and machine learning development.
Top Skills:
Amazon MskApache AirflowApache FlinkApache IcebergApache KafkaSparkAws Ec2Aws GlueAws IamAws S3Delta LakeDockerKubernetesParquetSpark Structured Streaming

Robotics
Build and maintain production data pipelines that transform robot logs and telemetry into reliable, queryable datasets. Design Spark-based ETL workflows, orchestrate processing with Airflow or similar tools, manage gold-layer datasets, and implement data quality, schema evolution, monitoring, and metadata practices. Collaborate with robotics, hardware, reliability, analytics, and ML teams on data modeling, fleet insights, debugging, and root-cause analysis. The role may also contribute to Python, Java, or C++ libraries supporting data capture and consumption.
Top Skills:
Apache AirflowApache IcebergSparkAvroAWSC++DagsterData Catalog SystemsData ModelingData OrchestrationData QualityDelta LakeETLJavaMedallion ArchitectureMetadata ManagementParquetPrefectPythonScalaSchema Evolution
Database
Designs and leads production-grade batch, incremental, streaming, and real-time data pipelines across Microsoft Fabric and Azure. Builds Delta Lake medallion architectures, dimensional and Data Vault models, CDC and incremental-loading solutions, CI/CD automation, governance, security, observability, and data-quality controls. Supports migrations to Fabric, prepares governed data for AI and RAG workloads, and leads client-facing engineering workstreams, estimates, risk management, mentoring, and operational handover.
Top Skills:
SparkAzure Data FactoryAzure DevopsAzure SynapseBicepData Vault 2.0Dataflows Gen2DaxDelta LakeGenaiGitGitKqlLakehouseAzureMicrosoft FabricMicrosoft PurviewOnelakePower BIPysparkPythonRagRest ApisSpark SqlSQL ServerSsasSsisT-SqlTerraform

Fitness
Own PushPress’s data platform, including ingestion, orchestration, cloud warehouse performance, governance, privacy, data quality, monitoring, and AI-ready data foundations. Build reliable pipelines integrating product, payment, and third-party data; establish data contracts, access controls, auditability, and semantic definitions; support real-time analytics and trustworthy reporting. Partner with Engineering, Data, and AI teams while maintaining infrastructure, incident response, documentation, and operational runbooks.
Top Skills:
Ai AgentsAirflowCcpaCdcCi/CdClickhouseDagsterElementaryEvent-Driven ArchitecturesFivetranGdprHevoMonte CarloPciPosthogPythonRbacRetrieval-Augmented GenerationRudderstackSegmentSemantic LayersSnowplowSQLStreamingTerraformTypescript

13 Days AgoSaved
Information Technology • Professional Services
Build and own production data infrastructure for a healthcare AI platform. Responsibilities include REST API ingestion, Azure Event Hubs streaming into Databricks, Delta Lake medallion pipelines, entity resolution, semantic metrics, data-quality instrumentation, reconciliation, schema-drift handling, and troubleshooting source-to-warehouse discrepancies. The role requires strong Python and SQL skills, independent pipeline ownership, and experience with Databricks, Spark, PySpark, streaming, and healthcare-related data is a plus.
Top Skills:
SparkAuto LoaderAzure Data FactoryAzure Data Lake StorageAzure Event HubsAzure Key VaultDatabricksDbt MetricsDelta LakeDelta Live TablesHolistics Aml/AqlKafkaKinesisLookmlPysparkPythonRest ApisSpark SqlSQLStructured Streaming

Professional Services • Retail • Design • Manufacturing
The Senior Data Engineer will design, implement, and manage data pipelines for real-time analytics and ML training datasets, ensuring efficient data flow and quality in a hybrid environment.
Top Skills:
Apache AirflowSparkAWSClickhouseKafkaMongoDBNatsPostgresPythonRayRedis StreamsSQL

AdTech • Automotive • Big Data • Consumer Web
Administer and enhance Edmunds’ Databricks data platform and AWS infrastructure. Build and maintain ETL pipelines, infrastructure-as-code tooling using Terraform or CDK, and operational dashboards, alerts, and reports. Collaborate with business, engineering, analytics, security, and infrastructure teams to support data platform users and AI solutions. Evaluate new technologies, troubleshoot platform issues, and improve operational, cost, and security visibility.
Top Skills:
SparkAWSAws CdkDatabricksInfrastructure As Code (Iac)PythonScalaSQLTerraform

Automotive • Insurance • Machine Learning • Mobile • Software
Build and guide data platform capabilities supporting marketing, finance, analytics, and data science. Develop data collection, integration, scoring, experimentation, analytics, and infrastructure solutions; contribute code, lead cross-functional technical initiatives, improve system resiliency through incident response, and establish engineering standards. Partner with business and technical stakeholders to define strategy and long-term roadmaps.
Top Skills:
Apache AirflowSparkAWSDbtPythonSQLTerraform
Big Data • Healthtech • Database • Analytics
Builds business-critical dashboards, scorecards, reports, and ad hoc analyses using SQL, Python, Excel, Power BI, and Tableau. Analyzes KPIs, identifies trends and root causes, automates recurring reporting, validates data, and translates complex findings into actionable insights for stakeholders and leadership. The role collaborates with data engineers and cross-functional teams to improve reporting workflows, data pipelines, and decision-making.
Top Skills:
ExcelHubspotPower BIPythonSalesforceSQLTableau
Automotive • Insurance • Machine Learning • Mobile • Software
Lead financial data engineering initiatives involving commissions, incentive programs, and backend financial systems. Build scalable, accurate, and reliable data pipelines, platform tooling, partner integrations, analytics infrastructure, and data science infrastructure. Shape technical strategy and roadmaps, collaborate with Finance, Product, Data Science, and Engineering, mentor engineers, contribute code, lead incident response, and establish engineering standards.
Top Skills:
Amazon RedshiftApache AirflowApache IcebergSparkAWSDbtPythonSQLTerraform

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies in Omaha, NE Hiring Data Engineers
See All






Popular Omaha, NE Job Searches
Tech Jobs & Startup Jobs in Omaha
Remote Jobs in Omaha
Content Jobs in Omaha
Customer Success Jobs in Omaha
IT Jobs in Omaha
Cyber Security Jobs in Omaha
Tech Support Jobs in Omaha
Data & Analytics Jobs in Omaha
Analysis Reporting Jobs in Omaha
Analytics Jobs in Omaha
Business Intelligence Jobs in Omaha
Data Engineer Jobs in Omaha
Data Science Jobs in Omaha
Machine Learning Jobs in Omaha
Data Management Jobs in Omaha
UX Designer Jobs in Omaha
Software Engineer Jobs in Omaha
Android Developer Jobs in Omaha
C# Jobs in Omaha
C++ Jobs in Omaha
DevOps Jobs in Omaha
Front End Developer Jobs in Omaha
Golang Jobs in Omaha
Hardware Engineer Jobs in Omaha
iOS Developer Jobs in Omaha
Java Developer Jobs in Omaha
Javascript Jobs in Omaha
Linux Jobs in Omaha
Engineering Manager Jobs in Omaha
.NET Developer Jobs in Omaha
PHP Developer Jobs in Omaha
Python Jobs in Omaha
QA Jobs in Omaha
Ruby Jobs in Omaha
Salesforce Developer Jobs in Omaha
Scala Jobs in Omaha
Finance Jobs in Omaha
HR Jobs in Omaha
Internships in Omaha
Legal Jobs in Omaha
Marketing Jobs in Omaha
Operations Jobs in Omaha
Office Manager Jobs in Omaha
Operations Manager Jobs in Omaha
Product Manager Jobs in Omaha
Project Manager Jobs in Omaha
Sales Jobs in Omaha
Account Executive (AE) Jobs in Omaha
Account Manager (AM) Jobs in Omaha
Sales Leadership Jobs in Omaha
Sales Development Representative Jobs in Omaha
Sales Engineer Jobs in Omaha
Sales Operations Jobs in Omaha
All Filters
Total selected ()
No Results
No Results
