

Maximum of 25 job preferences reached.
Top Site Reliability Engineer Jobs
Fintech
The Principal Site Reliability Engineer designs , improves software and tools for performance, scalability, and availability, while leading incident management and collaborating with development teams.
Top Skills:
AuroraAWSChefDockerDynamo DbGitGoJavaJenkinsJmsKafkaKubernetesMavenMemcachedOraclePythonRedisSqsSwarm
Artificial Intelligence • Machine Learning • Natural Language Processing • Software • Generative AI
The Site Reliability Engineer will develop, deploy, and operate AI infrastructure, focusing on high-performance and scalable machine learning systems using Kubernetes and cloud platforms.
Top Skills:
AWSAzureC++GCPGoKubernetesOci
Fintech
Lead design and implementation of highly available, fault-tolerant platform architectures. Define SLOs/SLAs, drive incident and problem management, build observability and automation, mentor engineers, and partner with stakeholders to improve reliability, performance, and compliance.
Top Skills:
AWSAzureCi/CdDevOpsIncident Management ToolingMonitoringObservability (LoggingSlo/Sli FrameworksTracing)

Healthtech • Insurance
Design, build, and operate scalable, resilient cloud infrastructure and SRE tooling. Lead cross-team technical projects, mentor engineers, define SLOs and incident management, automate CI/CD and IaC, reduce failure domains, and own medium-to-large infrastructure features from design through delivery.
Top Skills:
ArgocdAWSCi/CdGCPGithub ActionsGrafanaIamIstioKubernetesPrometheusTerraformVpc Peering
Healthtech • Insurance
Lead design, development, and operation of cloud infrastructure and SRE-focused systems. Own medium-to-large infrastructure projects, build resilient platforms, and drive cross-team technical delivery. Mentor engineers, define SLOs, reduce failure domains, and build tooling for automated, secure CI/CD and production reliability.
Top Skills:
ArgocdAWSGCPGithub ActionsGrafanaIamIstioKubernetesPrometheusTerraformVpc Peering
Healthtech • Insurance
Design, build, and operate resilient cloud infrastructure and platform services. Lead cross-team projects, mentor engineers, define SLOs, automate CI/CD and IaC, improve reliability, and own medium-to-large infrastructure features.
Top Skills:
ArgocdAWSGCPGithub ActionsGrafanaIamIstioKubernetesPrometheusTerraformVpc Peering
Healthtech • Insurance
Lead design, implementation, and reliability of cloud infrastructure and SRE practices. Own medium-to-large infrastructure projects, mentor engineers, define SLOs, reduce failure domains, build resilient systems, and collaborate cross-team to deliver secure, automated, scalable CI/CD and production environments.
Top Skills:
ArgocdAWSCi/CdGCPGithub ActionsGrafanaIamIstioKubernetesPrometheusTerraformVpc Peering
Healthtech • Insurance
Design, build, and operate resilient cloud infrastructure and SRE tooling. Lead cross-team projects, mentor engineers, define SLOs and runbooks, automate CI/CD and deployments, improve reliability, and own medium-to-large infrastructure features from design through completion.
Top Skills:
ArgocdAWSCi/CdGCPGithub ActionsGrafanaIamIstioKubernetesPrometheusTerraformVpc Peering
Energy
Build, transition, operate, and improve a multi-cloud production platform across Azure, GCP, AWS, and Kubernetes. Responsibilities include infrastructure as code, GitOps and CI/CD, managed Kubernetes operations, troubleshooting, incident response, observability, reliability improvements, disaster recovery, automation, and cost control. The role partners with architects and global teams to ensure platforms are secure, scalable, recoverable, and supportable.
Top Skills:
AksAnsibleAWSAzureCi/CdEksGitopsGkeGoGoogle Cloud PlatformKubernetesLinuxMongoDBMySQLNetworkingOpentofuPostgresPythonShell ScriptingTerraformTerragrunt
Artificial Intelligence • Healthtech • Information Technology • Software
As a Site Reliability Engineer, you will manage the production environment, focusing on infrastructure design, automation, and optimizing deployment pipelines to ensure high availability.
Top Skills:
HelmKafkaKubernetesPostgresPythonRedisTerraformTypescript

Agency • Marketing Tech • Software • Consulting
Lead and maintain performance, security, and reliability of client hosting environments across multi-cloud platforms. Architect resilient infrastructure, manage IaC and CI/CD, administer Windows/IIS and WP Engine environments, handle SSL/DNS/SSO, participate in on-call rotations, and engage with clients as senior escalation and trusted advisor.
Top Skills:
App ServicesApplication InsightsAWSAzureAzure DevopsAzure SqlCi/CdDnsEc2IamIisKey VaultsPowershellRdsS3Ssl/TlsSsoTerraformVulnerability ManagementWindows ServerWp Engine
Artificial Intelligence • Cloud • Software
The Senior Site Reliability Engineer will automate operations, optimize workflows for teams, manage secure infrastructure, and participate in on-call duties.
Top Skills:
AristaAWSBashCephChefCifsCiscoDnsDockerElk StackFortinetHpHTTPIcmpIscsiJenkinsKubernetesLinux/Debian Family/UbuntuMesosphereNfsNode.jsPivotal GreenplumPostgresPythonRabbitMQRubyS3ScyllaSshSslSupermicroTcpTls
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free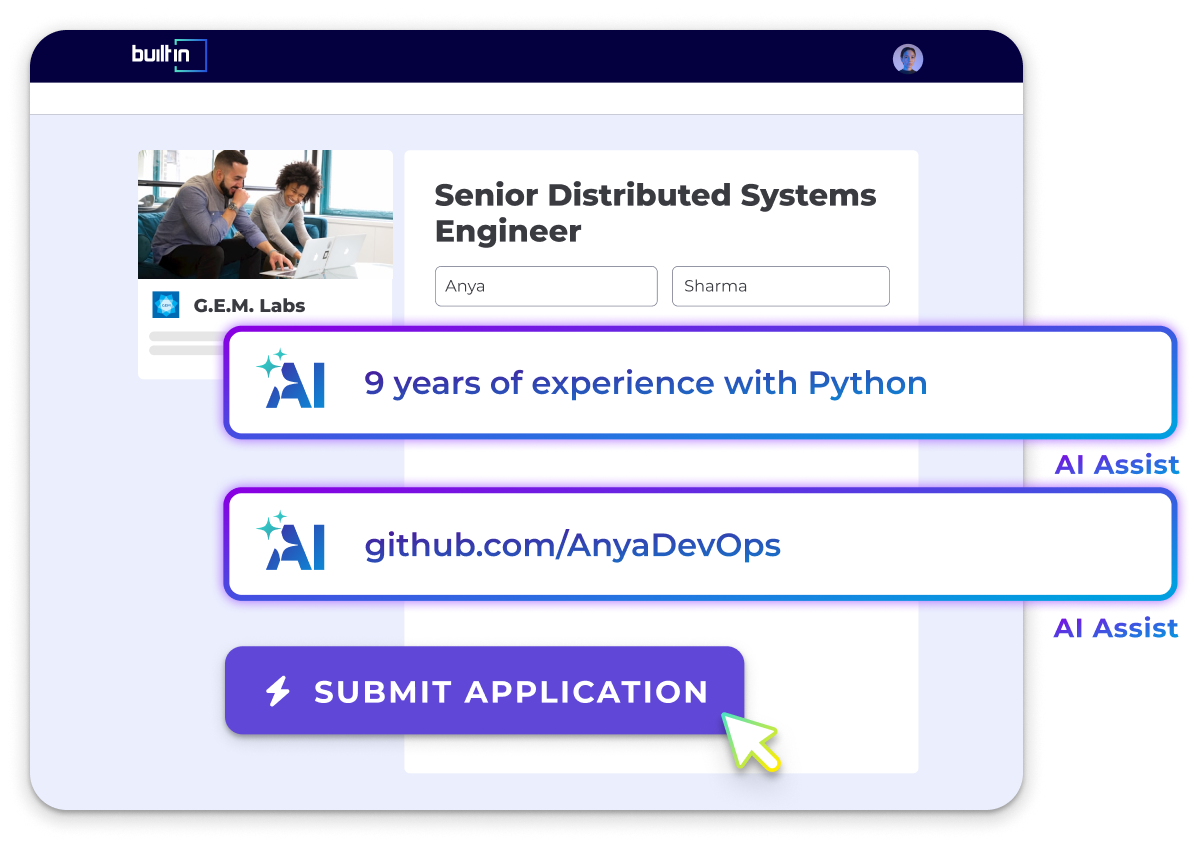

Artificial Intelligence • Machine Learning • Security • Database • Analytics • Big Data Analytics
As a Site Reliability Engineer, you'll ensure the availability and performance of AI applications, maintain infrastructure, automate tasks, and troubleshoot issues in high-scale environments.
Top Skills:
AnsibleAWSAzureBashCircleCICloudFormationDatadogDockerDynatraceEc2Elk StackGCPGitlab CiGoGrafanaJenkinsKubernetesLambdaLinuxPrometheusPythonS3TerraformUnix

Artificial Intelligence • Robotics • Automation • Manufacturing
Lead the Platform & SRE team to design and operate a unified deployment platform spanning cloud and on-premise. Architect Pulumi/Kubernetes-based deployments, package software for industrial hardware, build GitHub Actions CI/CD (including HIL), and define observability with Prometheus, Grafana, and OIDC.
Top Skills:
AWSAzureCertificate ManagementCnisGCPGithub ActionsGoGrafanaHelmHilKubernetesLinux NetworkingMulti-Cluster ManagementOidcPrometheusPulumiTerraform

Artificial Intelligence • Information Technology • Cybersecurity • Defense
The Forward Deployed Site Reliability Engineer ensures the reliability of a mission-critical platform, manages incident response, defines SLIs and SLOs, and liaises between engineering and government customers.
Top Skills:
AWSBashDockerGrafanaLokiMimirPrometheusPythonTerraform

Artificial Intelligence • Machine Learning • Biotech • Generative AI
The Site Reliability Engineer will manage digital infrastructure, ensuring access to compute resources, automating processes, and maintaining resource visibility for researchers.
Top Skills:
AnsibleDockerGrafanaKubernetesPrometheusPythonTailscaleTalos Linux

Big Data
Lead and operate cloud infrastructure and SRE practices, focusing on IaC, CI/CD, observability, incident response, and production-grade agentic AI/LLM systems. Architect, build, and run scalable platforms, drive reliability and SLOs, author runbooks/ADRs, mentor engineers, participate in on-call rotations, and reduce toil via automation and platform tooling.
Top Skills:
Agent OrchestrationAgentic AiAWSAzureDockerFluxcdGCPGithub ActionsGitopsGoGrafanaJavaJenkinsKubernetesLinuxLlmLlm GatewayLokiOpentofuPrometheusPythonSentrySignozTcp/IpTerraform
Reposted 2 Months AgoSaved
Artificial Intelligence
The Deployment Engineer will build and operate AI inference clusters, ensure scalable deployments, optimize allocation, and maintain infrastructure. Responsibilities include software updates, telemetry development, and collaborative improvements with teams.
Top Skills:
DockerGrafanaInfluxdbK8SLinuxPrometheusPython

AdTech • Big Data • Internet of Things • Marketing Tech • Mobile • Software • Analytics
Senior Site Reliability Engineer responsible for improving platform availability, scalability, resilience, and observability. The role manages AWS and EKS infrastructure with Terraform, builds CI/CD pipelines using GitHub Actions, expands GitOps through ArgoCD and Helm, strengthens disaster recovery, supports incident response, and develops monitoring, alerting, dashboards, and SLOs. The engineer partners with product teams, leads infrastructure initiatives, troubleshoots Kubernetes, and supports high-availability distributed systems.
Top Skills:
Amazon EksAmazon RdsAmazon VpcArgocdAWSAws IamCluster AutoscalerCrossplaneDatadogGithub ActionsGoHelmKarpenterKubernetesOpentofuPrometheusPythonShell ScriptingTerraform
Artificial Intelligence • Cloud • Software
The Senior Site Reliability Engineer will automate operations, improve workflows, manage secure infrastructure, and participate in on-call rotation for an AI-driven company.
Top Skills:
AristaAWSBashCephChefCifsCiscoDnsDockerElk StackFortinetHpHTTPIcmpIpIscsiJenkinsKubernetesLinux/DebianMesosphereNfsNode.jsPivotal GreenplumPostgresPythonRabbitMQRaidRubyS3ScyllaSshSslSupermicroTcpTlsUbuntu

Social Media
Operate, scale, and harden an AWS- and Kubernetes-based platform using GitOps. Build CI/CD and infrastructure-as-code (Terraform/Terragrunt), manage ArgoCD/Helm deployments, improve observability, automate toil reduction, lead incident response and post-incident remediation, and partner with application, security, and platform teams to improve reliability and delivery.
Top Skills:
ArgocdAWSBashContainersEksGithub ActionsGitopsHelmIamKubernetesLinuxPythonRbacTerraformTerragrunt

Information Technology • Automation
The SRE/Infrastructure Engineer will architect and manage secure, scalable systems for automated penetration testing, optimizing reliability, and enhancing infrastructure based on customer demand. Responsibilities include maintaining production environments, leading technical discussions, and promoting high coding standards.
Top Skills:
AWSAzureCloudFormationElkGCPNew RelicOpentelemetryPostgresPrometheusTerraform

HR Tech • Information Technology • Professional Services • Software • Business Intelligence • Consulting • Automation
Seeking a Site Reliability Engineer with expertise in Unix/Linux, scripting languages, and experience in containerization, cloud platforms, and application monitoring tools.
Top Skills:
AnsibleApache TomcatAWSCassandraChefCoradiantDockerDynatraceElasticGomezGCPJenkinsKafkaLinuxMq SeriesOraclePuppetPythonShell ScriptingSplunkTealeafUnixVagrantWebsphere

Software
Operate and improve reliability across Retool Cloud, managed, BYOC, and self-hosted deployments. Automate provisioning, upgrades, migrations, and secret rotations. Build observability and safer deployment/rollback workflows, partner with product teams, and produce runbooks, docs, and migration guides to reduce customer toil and scale operations.
Top Skills:
AWSDocker ComposeGoHelmJavaKubernetesPostgresPythonRubyTerraformTypescript
Artificial Intelligence • Cloud • Information Technology • Software
Contribute to the reliability and performance of Mithril's GPU orchestration platform through automation, observability, and infrastructure management. Collaborate with the team to ensure scalability across multi-cloud environments while maintaining systems stability and implementing SLOs.
Top Skills:
AWSAzureGCPGoGrafanaKubernetesLinuxOpentelemetryPrometheusPulumiPythonTcp/IpTerraform

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.






Popular Job Searches
All Software Engineer Jobs
.NET Developer Jobs
Aerospace Thermal Engineering Jobs
AI Engineer Jobs
Android Developer Jobs
Automation Engineer Jobs
Backend Developer Jobs
Blockchain Developer Jobs
C# Jobs
C++ Jobs
Cloud Architect Jobs
Cloud Engineer Jobs
Design Engineer Jobs
DevOps Engineer Jobs
Director Of Engineering Jobs
Electrical Engineering Jobs
Embedded Software Engineer Jobs
Engineering Jobs
Engineering Manager Jobs
Environmental Engineering Jobs
Field Engineer Jobs
Front End Developer Jobs
Full Stack Developer Jobs
Game Developer Jobs
Golang Jobs
Hardware Engineer Jobs
Industrial Engineering Jobs
iOS Developer Jobs
Java Developer Jobs
Javascript Developer Jobs
Linux Jobs
Manufacturing Engineer Jobs
Mechanical Engineering Jobs
Network Engineer Jobs
PHP Developer Jobs
Process Engineer Jobs
Project Engineer Jobs
Prompt Engineering Jobs
Python Jobs
QA Jobs
Robotics Engineer Jobs
Ruby on Rails Jobs
Salesforce Administrator Jobs
Salesforce Developer Jobs
Scala Jobs
Sharepoint Developer Jobs
Site Reliability Engineer Jobs
Software Engineering Manager Jobs
Solutions Architect Jobs
SQL Developer Jobs
Structural Engineer Jobs
System Engineer Jobs
Test Engineer Jobs
Web Developer Jobs
All Filters
Total selected ()
No Results
No Results
