

Maximum of 25 job preferences reached.
Top Site Reliability Engineer Jobs

Reposted 2 Months AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
The Senior Site Reliability Engineer will develop and support distributed storage services, ensuring reliability and operational safety, with a focus on automation and efficiency.
Top Skills:
AWSAzureDnsGoGoogle Cloud PlatformKubernetesLinuxPythonTcp/IpTls

Fintech • Financial Services
Leads the organization’s Platform Site Reliability Engineering strategy, operating model, governance, and AI-enabled automation. Builds resilient, self-healing systems; improves observability, incident response, availability, MTTR, technology risk, vulnerability remediation, cloud cost optimization, and operational readiness. Establishes SLOs, SLIs, error budgets, and reliability metrics while developing high-performing engineering teams. Provides executive leadership during major incidents and influences enterprise technology priorities.
Top Skills:
Agentic AiAiopsAPIsCi/CdCloud ComputingDevops AutomationGenerative AiInfrastructure As CodeObservabilityPolicy As CodeSite Reliability EngineeringTest Automation
One Month AgoSaved
Cloud • Software
Design and operate Procore’s next-generation cloud compute and data platform in a FedRAMP-compliant environment. Build and support distributed, highly available systems; manage Kubernetes clusters, cloud-native infrastructure, and infrastructure as code; participate across the software development lifecycle; run technical proofs of concept; and collaborate with product, UX, IT, and engineering teams to shape platform capabilities and roadmap.
Top Skills:
Amazon Ec2Amazon RdsAmazon S3AWSAws IamCloudFormationKubernetesTerraform

Cloud • Information Technology • Security • Virtual Reality • Cybersecurity
Support reliability, security, scalability, and performance of the TAK CI/CD pipeline and critical infrastructure. Monitor system health, respond to incidents, patch systems, optimize performance and costs, improve DevOps practices, automate operations, and maintain technical documentation. Requires systems and network administration experience, Linux and cloud expertise, containerization, CI/CD knowledge, Zero Trust implementation experience, Security+ certification, and an active T3 investigation.
Top Skills:
AWSCi/Cd PipelinesContainerizationLinuxZero Trust

Aerospace • Information Technology • Security • Cybersecurity • Defense
Designs and implements automation, infrastructure improvements, monitoring, observability, and infrastructure-as-code solutions for mission-critical applications and systems. Manages SLOs and SLIs, supports incident response and root cause analysis, optimizes performance and reliability, and collaborates across software, operations, and security teams in cloud and hybrid-cloud environments.
Top Skills:
AnsibleAWSAzureCephCiliumCloud ComputingConfiguration ManagementDesired State ConfigurationDockerHelmHybrid CloudInfrastructure As CodeKubernetesLinuxLoad BalancingMinioMonitoringObservabilityPortworxPowershellPythonRancherRookS3Terraform
Aerospace • Information Technology • Security • Cybersecurity • Defense
Designs and implements automation for large-scale distributed systems, develops tools for monitoring and system administration, manages cloud environments, supports system integration and testing, conducts incident and postmortem analysis, and improves operational reliability and visibility. The role supports distributed and massively parallel data environments in a mission-critical national security setting.
Top Skills:
AccumuloAWSBigtableCassandraElasticHadoopHbaseKubernetesPerlPuppetPythonRubySaltScality
Information Technology • Legal Tech • Analytics
Leads ICIS’s operational reliability function, managing SRE team leaders and engineers while improving production resilience, observability, automation, incident response, disaster recovery, and service reliability. The role sets operational priorities, oversees post-mortems and corrective actions, balances operational and security work, communicates risks across technology and business teams, and advances AI-enabled operations. Participation in on-call support and major incident response is expected.

eCommerce
This internship supports Tradeweb’s Reliability and Observability Engineering team. Responsibilities include building telemetry pipelines, developing React/TypeScript monitoring tools with Python and Kotlin services, managing Terraform infrastructure, deploying to AWS Kubernetes environments, creating dashboards and alerts, expanding monitoring coverage, analyzing telemetry costs and performance, and participating in code reviews and agile ceremonies.
Top Skills:
ArgocdAWSCC++GitGitlab CiJavaKotlinKubernetesLinuxPythonReactSQLTerraformTypescript

Automotive
Design and implement scalable cloud infrastructure, monitor performance, automate processes, ensure security and compliance, and lead a DevOps team.
Top Skills:
AWSBashCi/CdDockerElk StackGCPGrafanaKubernetesPrometheusPythonTerraform
Security • Software
Operate and improve reliable, scalable cloud services through monitoring, incident management, alerting, automation, and infrastructure administration. Develop C# .NET and Python tools, support high availability and SLA commitments, improve deployment and serviceability, and collaborate with R&D, Support, Product, Marketing, and Customer Success. Document operational procedures, maintain standards, and communicate service health, incidents, upgrades, and performance to internal and external stakeholders.
Top Skills:
.NetAmazon Web ServicesAutomated TestingC#Ci/CdGoogle Cloud PlatformJavaAzurePython
Cloud • Information Technology • Security • Software • Cybersecurity
The role involves creating scalable solutions using Linux and Kubernetes, troubleshooting performance issues, maintaining security, and writing automation tools.
Top Skills:
AnsibleBashDockerFirewall TechnologiesGoKubernetesKvmLinuxMulti-Factor AuthenticationOpenstackPgpPkiPythonSshUnix

Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Leads the technical vision, architecture, and roadmap for reliability across NVIDIA’s AI Platform Runtime. Designs resilient distributed platforms, establishes SLOs and reliability standards, advances observability and AI-driven automation, leads critical incident response, and drives cross-functional initiatives. The role requires mentoring senior engineers, influencing technical strategy across organizations, and delivering measurable improvements in availability, scalability, performance, and engineering productivity.
Top Skills:
Ai AgentsAnalyticsAnomaly DetectionAWSAws CdkAws CloudformationAzureCapacity ManagementCloud InfrastructureContinuous DeliveryCrossplaneDatabasesDistributed SystemsGCPGoGpu InfrastructureHigh-Performance ComputingInference SystemsInfrastructure As CodeJavaJavaScriptKubernetesLinuxLoggingMetricsNetworkingObservabilityOpentelemetryProfilingPythonSite Reliability EngineeringTerraformTracingTypescript
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free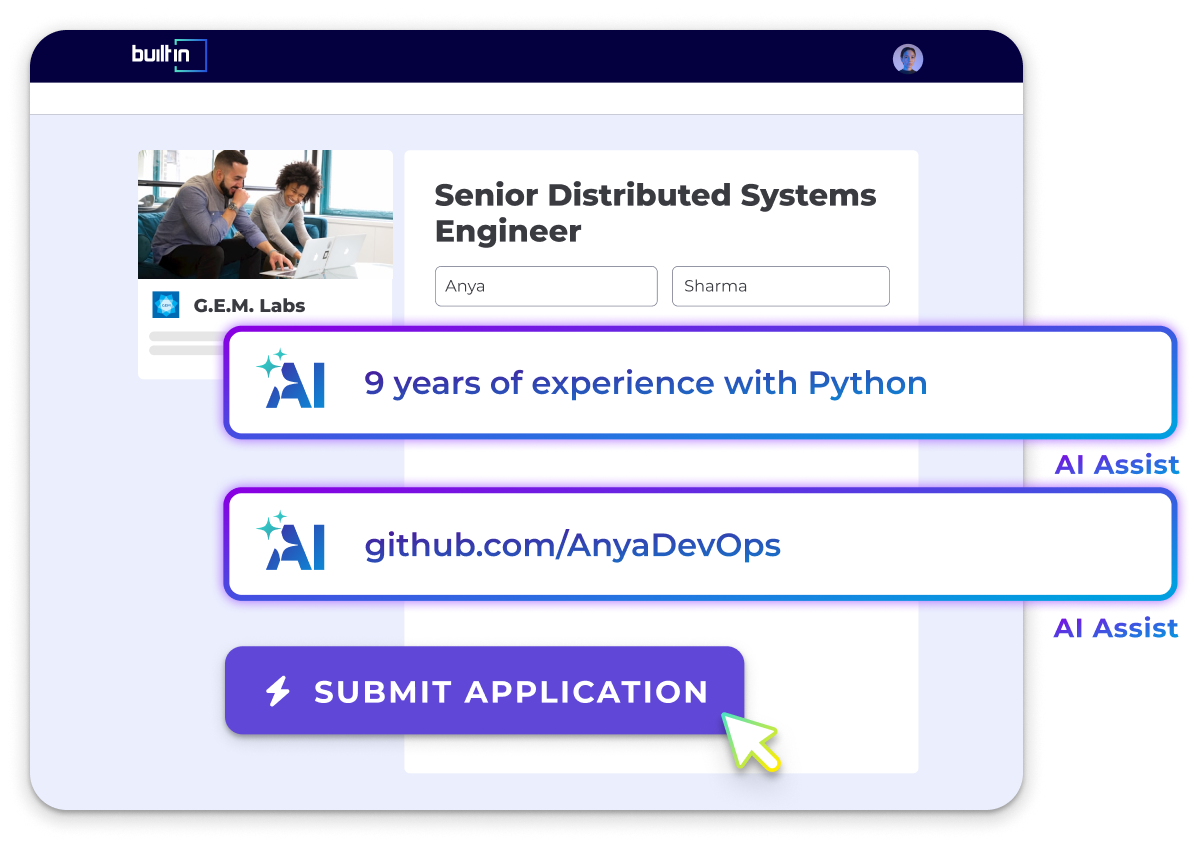

Cloud • Fintech • HR Tech
Responsible for designing, building, automating, and maintaining a secure, highly available Kubernetes-based analytics platform for federal deployments. Improve CI/CD, observability, provisioning (Terraform, Argo CD), troubleshooting, on-call incident response, and collaborate across teams to deliver Workday Prism Analytics in GovCloud.
Top Skills:
SparkArgo CdAWSCi/CdDockerGoGovcloudGrafanaKubernetesObservabilityPrism AnalyticsPrometheusPythonTerraformTracing
Information Technology • Software • Financial Services • Quantitative Trading
The Site Reliability Engineer will provide support and diagnose issues within a real-time, distributed environment, focusing on large-scale application and infrastructure management, with basic required skills in UNIX/Linux, networking, SQL, and scripting languages.
Top Skills:
BashPythonSQLTcp/IpUdpUnix/Linux

Fintech
Embed with product teams to improve reliability, observability, performance, and operational preparedness. Establish on-call, monitoring, alerting, runbook, SLO, and incident-response practices; conduct game days; implement reliability improvements in Haskell and TypeScript applications; identify observability gaps; participate in on-call rotations; and champion reliability through design and code reviews.
Top Skills:
AlertingDevOpsGrafanaHaskellHoneycombMonitoringObservabilityOn-CallOpentelemetryPostgresRunbooksSlosSreTemporalTypescript

Analytics • Consulting
Supports the reliability and performance of Gallup’s global technology platform through observability, dashboards, alerting, automation, and incident response. The intern will use tools including AWS, Dynatrace, PagerDuty, Slack, and infrastructure automation technologies while collaborating with site reliability, DevOps, and software engineering teams. The position is a full-time, on-site summer internship with potential part-time school-year work.
Top Skills:
Amazon EcsAWSBashDockerDynatraceGitGrafanaLinuxPagerdutyPowershellPythonSlackTerraformWindows

Automotive • Retail
Own reliability, availability, scalability, and performance for customer-facing eCommerce microservices. Define SLOs, SLIs, and error budgets; build observability and resiliency systems; lead incident response and postmortems; automate toil and remediation; perform root-cause analysis, capacity planning, and production readiness reviews; and mentor engineers while partnering across product, security, and platform teams.
Top Skills:
AkamaiAmazon EksAnsibleAWSAzureAzure AksBashCloudFormationDockerDynatraceElasticsearchElkEndecaGoogle Cloud PlatformGoogle GkeGroovyJ2EeJavaJIRAKubernetesLuceneNoSQLPerlPowershellPythonQuantum MetricRdbmsReactRubySolrSplunkSpring BootTealeafTerraform

Artificial Intelligence • HR Tech • Professional Services • Software
Evaluate AI-generated documents, spreadsheets, and presentations for accuracy, rigor, domain quality, and presentation quality in incident management, reliability, and SRE. Apply specialized rubrics, identify factual and aesthetic errors, and provide structured written feedback. This is a fully remote, flexible independent-contractor engagement requiring at least five years of relevant professional experience, English fluency, and proficiency with Microsoft Office and Google Workspace.
Top Skills:
Google SlidesGoogle WorkspaceMS OfficePowerPoint

Artificial Intelligence • Big Data • Healthtech • HR Tech • Machine Learning • Software • Big Data Analytics
Own the reliability, performance, resilience, observability, and security of AWS and Kubernetes infrastructure supporting products and AI/ML workloads. Define SLOs, lead incident response and root-cause analysis, build Terraform automation, optimize cloud costs, reduce operational toil, and establish deployment standards that help engineers ship reliably. Participate in on-call rotations and maintain HIPAA-compliant infrastructure.
Top Skills:
AWSClaudeDatadogGitlabGoHipaaIstioKubernetesNatsPostgresPythonSoc 2TerraformTypescript

Other
Own the architecture, reliability, scalability, security, and cost management of Cricut’s AWS platform infrastructure. Lead infrastructure-as-code practices, monitoring, incident response, SLO/SLI development, and blameless postmortems. Partner with engineering teams on platform strategy, evaluate AI/ML infrastructure, mentor engineers, and participate in 24/7 SRE on-call coverage.
Top Skills:
.NetAi/Ml InfrastructureAWSClaude CodeCloudFormationCursorDatadogEc2Github CopilotIamInfrastructure As CodeKinesisLlm OperationsModel ServingOpentelemetryRdsS3TerraformVector DatabasesVpc
eCommerce • Fintech • Information Technology • Payments • Financial Services
Operate and improve cloud-native financial platforms through automation, observability, incident response, reliability engineering, and infrastructure hardening. Responsibilities include building deployment and remediation automation, managing monitoring and alerting, defining SLIs and SLOs, handling on-call incidents and root-cause analysis, forecasting capacity, troubleshooting production issues, and collaborating with international cross-functional teams.
Top Skills:
AnsibleDatadogGitGithub ActionsGoGoogle Cloud Platform (Gcp)Google Kubernetes Engine (Gke)GrafanaHaproxyHttp/HttpsJavaKubernetesPrometheusPuppetPythonShell ScriptingTerraform
Information Technology • Software
The Senior Site Reliability Engineer will scale and maintain VETRO’s cloud-based FiberMap platform. Responsibilities include improving reliability, observability, incident response, automation, CI/CD, infrastructure performance, security, disaster recovery, developer tooling, and cloud cost efficiency. The role requires troubleshooting distributed systems, supporting AWS infrastructure, optimizing databases and spatial data services, participating in on-call rotations, and applying AI-enabled operational improvements.
Top Skills:
AWSBashCi/CdGisGoInfrastructure As CodeLinuxNatsNode.jsPostgisPostgresPythonSoc 2Terraform
Artificial Intelligence • Information Technology
Own the reliability, performance, and uptime of large-scale post-training and reinforcement learning systems. Debug distributed failures across accelerators, networking, storage, schedulers, and training frameworks; build monitoring, alerting, recovery, checkpointing, and scheduling tools; improve cluster utilization and fault tolerance; support production model runs through on-call rotations and postmortems; and partner closely with research teams during active training runs.
Top Skills:
C++DpoGoGpuInfinibandKubernetesLinuxNcclPpoPythonPyTorchRayRdmaRlhfSlurmTpu
Artificial Intelligence • Information Technology
Owns end-to-end reliability for Tinker, including CI/CD, observability, service-level objectives, incident response, multi-tenant isolation, resource scheduling, and vulnerability remediation. The role designs monitoring for distributed training systems, improves recovery and checkpointing, and operates Kubernetes clusters supporting heterogeneous GPU workloads. It collaborates closely with platform, security, engineering, and research teams to improve production resilience and utilization.
Top Skills:
Ci/CdCloud InfrastructureDistributed SystemsGpu WorkloadsKubernetesLoraProduction Observability
Information Technology • Legal Tech • Analytics
Build and operate reliable, scalable platforms and services across AWS environments. Responsibilities include infrastructure automation with Terraform, CI/CD development, observability, incident response, disaster recovery testing, AI service deployment, security, infrastructure documentation, and developer enablement. The role partners with engineering teams to improve availability, performance, recovery, and operational self-service.
Top Skills:
Acm/TlsAlbAWSAws CliBashCloudwatchDockerDynamoDBEcrEcsFargateGitGithub ActionsIamKmsLambdaLinuxOidcPythonRdsRoute53S3Secrets ManagerSqsTerraformVpc

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies Hiring Site Reliability Engineers
See All






Popular Job Searches
All Software Engineer Jobs
.NET Developer Jobs
Aerospace Thermal Engineering Jobs
AI Engineer Jobs
Android Developer Jobs
Automation Engineer Jobs
Backend Developer Jobs
Blockchain Developer Jobs
C# Jobs
C++ Jobs
Cloud Architect Jobs
Cloud Engineer Jobs
Design Engineer Jobs
DevOps Engineer Jobs
Director Of Engineering Jobs
Electrical Engineering Jobs
Embedded Software Engineer Jobs
Engineering Jobs
Engineering Manager Jobs
Environmental Engineering Jobs
Field Engineer Jobs
Front End Developer Jobs
Full Stack Developer Jobs
Game Developer Jobs
Golang Jobs
Hardware Engineer Jobs
Industrial Engineering Jobs
iOS Developer Jobs
Java Developer Jobs
Javascript Developer Jobs
Linux Jobs
Manufacturing Engineer Jobs
Mechanical Engineering Jobs
Network Engineer Jobs
PHP Developer Jobs
Process Engineer Jobs
Project Engineer Jobs
Prompt Engineering Jobs
Python Jobs
QA Jobs
Robotics Engineer Jobs
Ruby on Rails Jobs
Salesforce Administrator Jobs
Salesforce Developer Jobs
Scala Jobs
Sharepoint Developer Jobs
Site Reliability Engineer Jobs
Software Engineering Manager Jobs
Solutions Architect Jobs
SQL Developer Jobs
Structural Engineer Jobs
System Engineer Jobs
Test Engineer Jobs
Web Developer Jobs
All Filters
Total selected ()
No Results
No Results
