

Maximum of 25 job preferences reached.
Top Remote Data Engineer Jobs

Artificial Intelligence • Information Technology • Software • Consulting
Define and lead enterprise data platform architecture across ingestion, storage, processing, governance, and consumption. Establish data modeling, security, lifecycle, and platform standards; architect lakehouse, warehouse, and streaming solutions; integrate governance and catalog tools; design scalable pipelines, disaster recovery, and high availability; optimize costs; guide architecture reviews; partner with ML, BI, and product teams; and mentor data engineers and architects.
Top Skills:
AlationApache FlinkApache HudiApache IcebergApache KafkaSparkAtlanAWSBigQueryCollibraCubeDatabricksDatahubDbt Semantic LayerDelta LakeGoogle Cloud PlatformLookmlAzureRedshiftSnowflakeUnity Catalog

Automation • Manufacturing
Designs and implements scalable software solutions, develops maintainable features, resolves bugs, optimizes performance, and writes automated tests. Participates in architecture discussions, code reviews, Agile planning, CI/CD, observability, and adoption of AI-assisted engineering tools. Collaborates with QA, Product Management, and DevOps to deliver software across web, desktop, cloud, and IoT environments. The role is remote for candidates in the Seattle or Los Angeles metropolitan areas, with quarterly travel to Los Angeles.
Top Skills:
Amazon Api GatewayAmazon S3Automated TestingAWSAws LambdaC#Ci/CdClaude CodeGitGraphQLJavaScriptPythonRestSQL
News + Entertainment
Lead the Ads Signals & Measurement data engineering team across conversion and attribution, measurement foundations, audience onboarding, and identity. Set cross-organizational technical direction, resolve scalable data architecture decisions, mentor engineers, and partner on platform-wide initiatives. The role requires expertise in modern data stacks, advertising technology data flows, privacy and governance, distributed systems, and emerging AI technologies.
Top Skills:
Agentic TechnologiesAIColumnar StoresKafkaSpark

Big Data • Consumer Web • eCommerce • Enterprise Web • Software • Analytics • Big Data Analytics
Develop and optimize large-scale data systems, ETL pipelines, storage, entity-resolution products, and data automation infrastructure. Build and integrate ingestion and processing pipelines using AWS, Airflow, Spark, PySpark, and EMR. Create testing and monitoring components, develop analytical tools, support data governance and quality, collaborate with data science teams, and document technical solutions.
Top Skills:
Amazon DynamodbAmazon EmrAmazon S3Apache AirflowSparkAWSData PipelinesDimensional Data ModelingDistributed SystemsElasticsearchETLPysparkPythonSchema DesignSQL
Artificial Intelligence • Consumer Web • Information Technology • Real Estate • Software • PropTech
Own and evolve end-to-end data pipeline architecture across ingestion, transformation, modeling, and serving. Lead platform improvements for cost efficiency, reliability, access control, observability, orchestration, CI/CD, and developer experience. Drive complex cross-team initiatives, resolve production issues, influence architectural decisions, mentor engineers, and build automation incorporating AI into data engineering workflows.
Top Skills:
Apache AirflowCi/CdContainerized InfrastructureDatadogKubernetes

Fitness • Healthtech • Retail • Pharmaceutical
Designs and implements data models, schemas, and ETL/ELT pipelines supporting analytics, reporting, and machine learning. Optimizes query performance, partitioning, and clustering; establishes data quality, governance, and security standards; integrates data with BI and machine learning tools; documents workflows; and mentors junior engineers. Collaborates with data scientists, analysts, and product owners to architect cloud-based analytical infrastructure and data marts.
Top Skills:
AWSAzureEtl/EltGCPOmopPythonSQLTuva

Security • Software
Design, build, deploy, and support production data pipelines and enterprise data solutions in Databricks and GCP. Develop data models and layered architectures, ensure data quality, security, and governance, integrate multiple sources, and support analytics, AI/ML, reporting, and operational decision-making while collaborating with technical teams and federal stakeholders.
Top Skills:
APIsBigQueryCi/CdDatabricksDelta LakeGoogle Apps ScriptGoogle Cloud PlatformJavaScriptPythonSQLUnity Catalog

Software
Build and scale resilient ingestion, catalog, and derived data pipelines powering core infrastructure datasets. Own data contracts, schema governance, quality gates, automated testing, observability, and pipeline reliability. Modernize legacy systems into scalable platform architecture, including a graph database layer. Partner with global engineering, data science, ML, intelligence, and trust teams to support matching, confidence scoring, and automated workflows.
Top Skills:
Amazon KinesisAmazon NeptuneApache FlinkAWSDbtGreat ExpectationsKafkaMonte CarloNeo4JPostgresPythonSodaSQL
Artificial Intelligence • Information Technology • Software • Consulting
Designs, builds, and operates large-scale Hadoop-based data pipelines and analytics platforms. Responsibilities include ingesting, transforming, and analyzing structured and unstructured data; developing Spark applications; managing streaming workflows; working with relational and NoSQL stores; orchestrating pipelines; troubleshooting distributed systems; and supporting reliable, scalable production data platforms.
Top Skills:
AirflowApache AtlasApache HudiApache IcebergSparkAws EmrAzure HdinsightCi/CdCollibraDatabricksDelta LakeFlinkHadoopHbaseHdfsHiveInfrastructure As CodeJavaKafkaKubernetesNoSQLOoziePythonScalaShellSpark StreamingSQLSqoopTrino

Automotive • Big Data • Insurance • Software • Transportation
Designs, builds, and maintains scalable ETL/ELT pipelines and finance data models using Snowflake, AWS, dbt Core, Python, and SQL. Develops Medallion architecture data marts, integrates ERP systems, and partners with stakeholders on financial workflows. Implements data governance, RBAC, automated quality testing, observability, documentation, CI/CD, and secure deployments. Monitors Snowflake costs and optimizes queries while supporting Oracle EBS integrations and the migration to Workday.
Top Skills:
AWSCi/CdDbt CoreGitOracle EbsPythonSnowflakeSQLWorkday

Artificial Intelligence • Big Data • Healthtech • Information Technology • Machine Learning • Software • Analytics
The Principal Data Engineer will lead data engineering efforts on public cloud, design scalable solutions, build data pipelines, and drive deliverables with a high level of technical expertise in relevant technologies.
Top Skills:
AdfAzureCi/CdContainersDatabricksDelta LakeDockerJenkinsKafkaSnowflakeSparkTerraform

Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Owns architecture, roadmap, development, and production operations for major components of NVIDIA’s distributed data platform. Builds batch and streaming pipelines, data products, shared platform capabilities, quality standards, and operational practices using Python, SQL, Databricks, and Spark. Leads cross-team technical delivery, production investigations, architectural changes, mentoring, and adoption of reliable, secure, scalable data systems supporting GPU fleet health, capacity, utilization, cost, and operational decisions.
Top Skills:
SparkAWSAzureCi/CdDatabricksDelta LakeElasticsearchGCPKafkaKubernetesOpensearchPysparkPythonSlurmSpark SqlSQLUnity Catalog
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free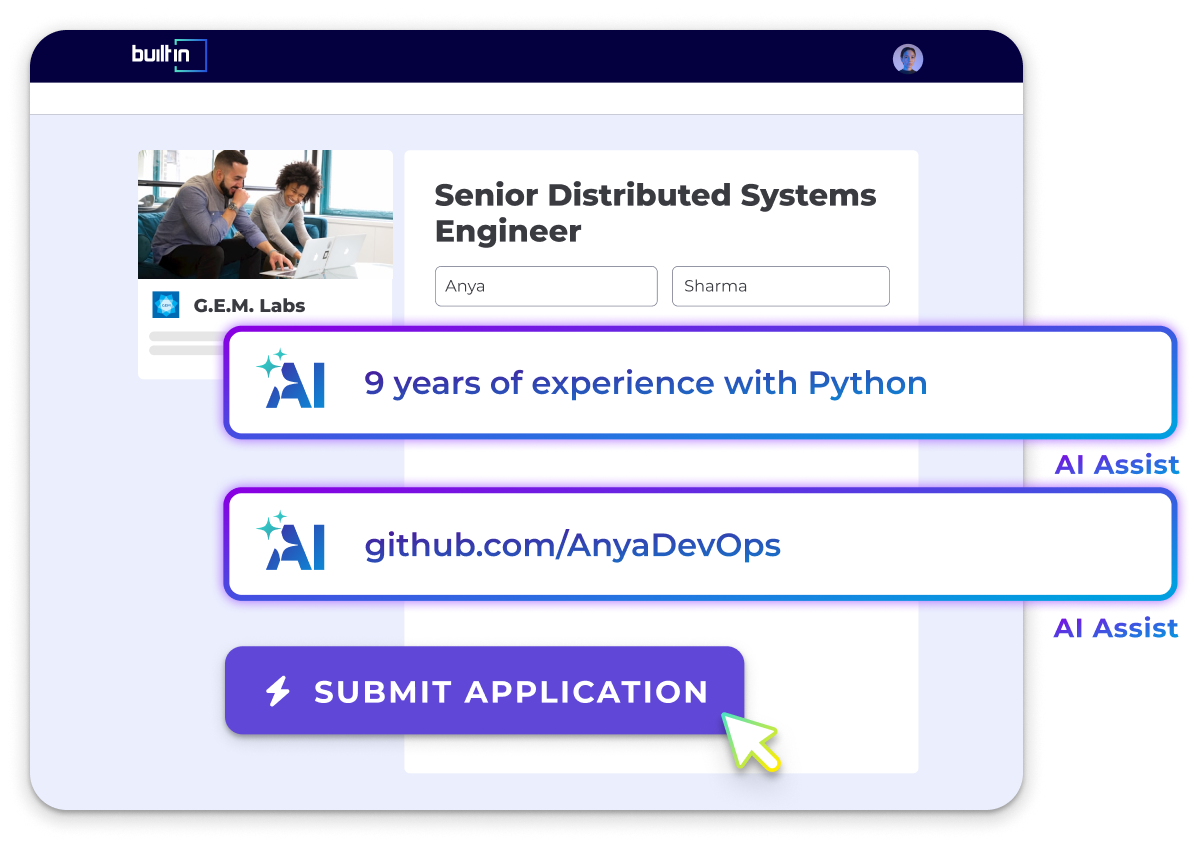
Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Build and operate NVIDIA DGX Cloud’s data platform, including batch and streaming pipelines, distributed data workloads, data products, quality monitoring, security, observability, and self-service consumption. Own systems from architecture through deployment and incident response. Improve platform reliability, scalability, and engineering practices while mentoring teammates. Work primarily with Python and SQL across cloud infrastructure, databases, Spark, telemetry, and operational data.
Top Skills:
Ai AgentsSparkAWSAzureCi/CdDatabricksDelta LakeElasticsearchGCPKafkaKubernetesLlmsOpensearchPysparkPythonSlurmSpark SqlSQLUnity Catalog

Biotech
Leads architecture and hands-on development of scalable data pipelines, governed data models, semantic layers, analytics products, and AI workflows. Writes production SQL and Python, establishes engineering standards, mentors engineers, and drives design reviews. Builds agentic and LLM solutions using retrieval and managed AI services while ensuring data quality, observability, reliability, privacy, and regulatory compliance for PHI and genomic data. Partners with stakeholders, platform teams, and governance forums to deliver trustworthy business solutions.
Top Skills:
AirflowAWSAws BedrockDagsterDbtEhrLaboratory Information SystemsLangchainLanggraphLlmsLookerPower BIPrefectPythonRagSalesforceSigmaSnowflakeSnowflake CortexSnowparkSQLTableauTerraform

Fintech • Financial Services
Designs and develops complex cloud-native data solutions, scalable batch and real-time pipelines, APIs, data models, and enterprise data platforms. Implements data governance, quality, lineage, security, observability, CI/CD, automated testing, and operational reporting capabilities. Collaborates with architects, product owners, analysts, governance, security, and platform teams on technology strategy and cloud modernization. Mentors engineers, leads technical design discussions, presents recommendations, and supports AI-ready data products and emerging development tools.
Top Skills:
Ai FoundryAlationApache AirflowApi ManagementAWSAzureAzure Ai SearchAzure Container AppsAzure Data FactoryAzure DatabricksAzure DevopsAzure FunctionsAzure OpenaiAzure PurviewAzure SqlAzure StorageBigQueryCi/CdCollibraCopilot StudioCosmos DbEltErwinETLEvent HubsGCPGitGit FlowGitGithub CopilotInformatica MdmInfosphereJavaMcpMicrosoft FabricPythonScalaSnowflakeSQLTrunk-Based Development

Aerospace • Information Technology • Security • Cybersecurity • Defense
Build and maintain production data ingestion, transformation, and pipeline systems for a governed federal data and AI platform. Develop data products, contribute to Terraform infrastructure and CI/CD, monitor quality and reliability, troubleshoot issues, and apply governance and access controls. Support data science and ML teams while operating within FedRAMP, NIST 800-171, and CUI requirements. Collaborate with engineers and document pipelines and processes.
Top Skills:
AirflowAWSAzureCi/CdCuiDatabricksDbtDeltaFedramp ModerateGCPNist 800-171PythonSnowflakeSparkSQLTerraform

Insurance • Cybersecurity
Owns the architecture and technical direction of Coalition’s enterprise data platform. Builds scalable Snowflake and dbt infrastructure, governed data models, batch and streaming pipelines, data products, semantic layers, observability, security controls, and AI/ML data foundations. Partners across engineering, product, underwriting, actuarial, security, and business teams while mentoring engineers and establishing technical standards.
Top Skills:
AirflowAmazon KinesisAtlanDagsterDatahubDbtDbt-ExpectationsDynamic TablesElementaryEmbeddingsEvidently AiFeastGithub ActionsKafkaLookerLookmlOpenlineagePrefectPythonRagSnowflakeSnowflake CortexSnowpipe StreamingSQLTerraformVector Search

Information Technology • Design
Designs, builds, and operates scalable data pipelines, warehouses, lakes, and integrations supporting analytics, products, and production AI/ML systems. Responsibilities include data modeling, schema design, validation, monitoring, orchestration, real-time processing, governance, and observability. The role contributes to architecture decisions, collaborates across analytics, AI, and product teams, communicates technical tradeoffs, and owns data engineering work end to end.
Top Skills:
Ci/CdClaudeContainer OrchestrationCursorData LakesData ModelingData ObservabilityData ValidationData WarehousesDistributed SystemsEmbeddingsEtl/EltFeature StoresMlopsPythonReal-Time Data ProcessingRetrieval-Augmented Generation (Rag)ScalaSQLStreaming PlatformsVector Stores
Artificial Intelligence • Information Technology • Software • Consulting
Designs and supports enterprise data platforms, scalable ETL/ELT pipelines, distributed processing systems, data lakes, and cloud-native data solutions. The role covers data architecture, modeling, warehousing, batch and streaming processing, database optimization, deployment, troubleshooting, governance, and operational support. The engineer collaborates with data scientists, analysts, software engineers, architects, DevOps teams, and business stakeholders in an Agile environment.
Top Skills:
Apache AirflowApache FlinkApache KafkaApache NifiAWSAzureCassandraCi/CdDatabricksDockerGitGoogle Cloud PlatformHelmJavaKubernetesMongoDBMySQLOraclePostgresPythonRabbitMQScalaSnowflakeSparkSQLSQL ServerTerraformTerraform

Financial Services
Designs and maintains scalable Databricks data pipelines on AWS, covering ingestion, transformation, streaming, data quality, and analytics-ready dataset delivery. Builds medallion architecture layers using Spark, Python, SQL, Delta Lake, and AWS services. Responsibilities include source-to-target mapping, unit testing, CI/CD deployment, anomaly analysis, and compliance with FISMA High and multi-tenant governance requirements. Collaborates in Agile teams and uses AI automation tools to accelerate pipeline development and validation.
Top Skills:
Amazon CloudwatchAmazon KinesisAmazon RdsAmazon S3SparkAWSAws Database Migration ServiceAws GlueAws IamAws LambdaAws Step FunctionsCi/CdCloudFormationDatabricksDatabricks Auto LoaderDelta LakeGitlabKafkaPandasPysparkPythonRSpark Structured StreamingSQLTerraform

Information Technology • Consulting
Designs and operates data infrastructure for a clinical trial platform. Builds pipelines that extract, normalize, validate, and link information from clinical documents and publications into Aurora and GraphDB. Develops embeddings, vector search, RAG workflows, data-serving APIs, lineage tracking, and regulatory audit trails. The role also requires AWS-based orchestration, clinical data quality controls, biomedical knowledge graph modeling, and deployment automation using infrastructure-as-code and containerization.
Top Skills:
AirflowAmazon Aurora PostgresqlAmazon S3Amazon SnsAmazon SqsAngularSparkAWSAws CdkAws IamAws LambdaAws Step FunctionsCypherDatabricksDbtDockerFastapiGitGraphdbLangchainLanggraphNeo4JNeptuneOpensearchPdfplumberPgvectorPineconePostgresPrefectPymupdfPythonRagSparqlTemporalTerraformUnstructured.Io

Information Technology • Other • Software
Designs and maintains scalable data pipelines, warehouse models, and analytics solutions. Builds natural-language data interfaces using GenAI and LLM techniques, optimizes SQL, improves data quality and observability, and supports distributed data platforms on AWS or GCP. Partners with engineering, analytics, business, and product teams, contributes to shared codebases, establishes development standards, and participates in production on-call and incident response.
Top Skills:
AirflowAmazon RedshiftSparkAWSCubeDatabricksGCPGenaiKafkaLlmMetabasePythonReactRuby On RailsSnowflakeSQLStarrocksTrino
Artificial Intelligence • Information Technology • Software • Consulting
Designs, executes, and supports enterprise data migrations into SAP S/4HANA. Responsibilities include data extraction, transformation, validation, reconciliation, cutover, replication, system refreshes, troubleshooting, and documentation. The role requires collaboration with functional teams, business owners, and infrastructure stakeholders while ensuring data accuracy, completeness, compliance, and governance across large-scale SAP implementations.
Top Skills:
ETLSap Data ServicesSap HanaSap LtmcSap LvmSap S/4HanaSap SltSQL

Artificial Intelligence • Cloud • Software • Cybersecurity
Manage the health, performance, reliability, and cost of customer Snowflake and Databricks environments. Responsibilities include customer onboarding, account and warehouse setup, permissions, data ingestion, query optimization, cost reporting, incident response, escalation support, and automation using Python and Terraform. The role also advises customers and internal teams on data platform best practices and participates in on-call rotations.
Top Skills:
AWSAzureDatabricksGCPGrafanaPythonSentrySnowflakeSQLTerraform

Financial Services
Build and maintain data lakes, data warehouses, and modern data pipelines for a multi-tenant SaaS platform. Design end-to-end data processes, write pipeline and infrastructure code, conduct design reviews, optimize performance, monitor systems, support data governance, and troubleshoot scalability and security issues. Collaborate with technical and business stakeholders, mentor junior engineers, evaluate technologies, document platform architecture, automate testing, and participate in on-call rotation.
Top Skills:
AthenaAWSAws CloudformationCassandraCi/CdDynamoDBEksEmrGlueGreenplumInfrastructure As CodeKafkaKinesisKubernetesLambdaMongoDBMskPostgresPythonRdsRedshiftS3SQLSQL ServerTerraform

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies Hiring Remote Data Engineers
See All






Popular Remote Job Searches
Remote Analytics Engineer Jobs
Remote Analytics Manager Jobs
Remote Business Analyst Jobs
Remote Business Intelligence Analyst Jobs
Remote Business Systems Analyst Jobs
Remote Compliance Analyst Jobs
Remote Data Analyst Jobs
Remote Data Architect Jobs
Remote Database Administrator Jobs
Remote Database Engineer Jobs
Remote HRIS Analyst Jobs
Remote Machine Learning Engineer Jobs
Remote Pricing Analyst Jobs
Remote Program Analyst Jobs
Remote Research Jobs
Remote Senior Business Analyst Jobs
Remote Senior Data Analyst Jobs
All Filters
Total selected ()
No Results
No Results
