

Maximum of 25 job preferences reached.
Top Remote Data Engineer Jobs
Information Technology
Designs, develops, and supports analytics data solutions for clients, including Snowflake and dbt ingestion and transformation pipelines, data marts, validation, monitoring, governance, and documentation. Manages multiple consulting projects, budgets, timelines, quality assurance, troubleshooting, client communication, and implementation planning. Requires strong data engineering experience, regulated-industry knowledge, stakeholder communication, and willingness to travel.
Top Skills:
AWSDbtSnowflakeSQL
Artificial Intelligence • Healthtech • Machine Learning • Natural Language Processing • Biotech • Pharmaceutical
Build and operate production data pipelines supporting analytics, AI, and agentic workflows. Responsibilities include implementing canonical data models, maintaining Databricks or Snowflake platforms, monitoring reliability, responding to incidents, validating healthcare data mappings, improving performance and cost, and documenting architecture. Requires strong SQL and Python skills, cloud data platform experience, ETL/ELT orchestration expertise, and healthcare or pharmaceutical data experience.
Top Skills:
Ai/Ml WorkflowsDatabricksEltETLHedisOmopPythonSnowflakeSQL

AdTech • Automotive • Big Data • Consumer Web
Administer and enhance Edmunds’ Databricks data platform and AWS infrastructure. Build and maintain ETL pipelines, infrastructure-as-code tooling using Terraform or CDK, and operational dashboards, alerts, and reports. Collaborate with business, engineering, analytics, security, and infrastructure teams to support data platform users and AI solutions. Evaluate new technologies, troubleshoot platform issues, and improve operational, cost, and security visibility.
Top Skills:
SparkAWSAws CdkDatabricksInfrastructure As Code (Iac)PythonScalaSQLTerraform

Artificial Intelligence • Cloud • Payments • Software • Business Intelligence • Generative AI • Automation
Define and govern enterprise-scale data architecture across batch, streaming, warehouse, lakehouse, transactional, and AI use cases. Establish standards for data quality, lineage, access, cataloging, governance, observability, and SLAs. Architect AI-enabled workflows, resolve complex architecture issues, influence roadmaps, and mentor engineers through hands-on technical leadership. The role requires 15+ years of software, data engineering, or architecture experience and expertise in large-scale data platforms and modeling.
Top Skills:
AIBatch ProcessingBigQueryData CatalogsData WarehousesDbtFeature StoresGCPLakehousesOlapOltpStreaming ArchitecturesVector Stores

Fintech • News + Entertainment • Software • Database • Financial Services
Lead the architecture and development of scalable AWS-based data ingestion, transformation, and orchestration pipelines. Build reliable data infrastructure using Python, SQL, Airflow, Lambda, ECS, SQS, and Terraform. Establish data modeling, quality, lineage, monitoring, testing, and observability practices while partnering with analysts, scientists, and backend engineers. Mentor senior engineers, guide technical decisions, and provide hands-on leadership for complex data platform initiatives.
Top Skills:
Amazon EcsAmazon KinesisAmazon RedshiftAmazon S3Amazon SqsApache AirflowApache FlinkAWSAws GlueAws LambdaBeautifulsoupCi/CdDatabricksDockerGreat ExpectationsKafkaMonte CarloMwaaPythonScrapySnowflakeSQLTerraform

Artificial Intelligence • Cloud • Computer Vision • Hardware • Internet of Things • Software
Design, build, and maintain scalable Spark-based ETL pipelines and computed tables in a central data lake. Integrate structured and unstructured IoT, sensor, and external data for analytics, model training, and dashboards. Collaborate with Data Science, Analytics, and ML teams to ensure reliable, high-quality customer-facing datasets.
Top Skills:
AirflowAWSAzureDagsterData LakeDatabricksDelta LakeETLGCPGitGitPrefectPysparkPythonRest ApisSparksqlSQL

AdTech • Consumer Web • Digital Media • eCommerce • Marketing Tech • SEO
Build and support scalable data platforms and pipelines, leading migrations such as Snowflake to BigQuery and transitioning reporting to Looker. Responsibilities include data architecture, ETL/ELT, API and marketing integrations, data quality, production troubleshooting, warehousing, performance optimization, and platform modernization. The role partners with analytics and business teams, owns projects through production, documents solutions, and provides technical guidance.
Top Skills:
AWSAzureBigQueryConfluenceDraw.IoGCPGitJIRAKafkaLookerLucidchartMiroModeNotionPower BIPythonSnowflakeSparkSQLTableauTalend

Artificial Intelligence • Information Technology • Professional Services • Software • Analytics • Generative AI • Big Data Analytics
Configure and maintain Adobe Experience Platform and Real-Time CDP data pipelines, XDM schemas, datasets, identity resolution, Profile enablement, segmentation readiness, and destination activation. Validate data quality, troubleshoot ingestion and identity issues, manage sandboxes, and implement privacy, consent, governance, and access controls. Partner with architects, data engineers, consultants, analysts, data scientists, and marketing teams to support reporting, personalization, and machine learning readiness.
Top Skills:
Adobe AnalyticsAdobe Experience PlatformAdobe I/O RuntimeAdobe Journey OptimizerAdobe Real-Time CdpAdobe Source ConnectorsAdobe TargetAPIsAWSAzureBatch IngestionBigQueryCcpaData PrepEltETLGCPGdprJavaScriptPythonQuery ServiceRedshiftSalesforce CdpSegmentSnowflakeSQLStreaming IngestionWeb SdkXdm

Healthtech • Information Technology • Mobile • Productivity • Software • Analytics • Telehealth
Design and build maintainable data pipelines, ETL processes, and data architecture standards. Collaborate with product managers, analysts, and machine learning engineers to translate requirements into automated, scalable solutions. Apply software engineering best practices, asynchronous systems, APIs, streaming, testing, monitoring, and Python and SQL expertise. Help prioritize data initiatives based on business impact and communicate complex technical concepts to technical and non-technical stakeholders.
Top Skills:
APIsArtificial IntelligenceETLGitMachine LearningMultithreadingPythonSQLStreaming
Healthtech • Social Impact • Software • Telehealth
Build scalable, secure data pipelines, models, platforms, and governance systems that enable AI applications to access trusted enterprise data. Partner with analytics, marketing, and product teams to translate requirements into technical solutions, independently deliver projects through production, and support sensitive-data security and access controls. Preferred experience includes LLM architectures, cloud data platforms, infrastructure as code, regulated environments, and technical leadership.
Top Skills:
Apache IcebergApache KafkaSparkAWSLarge Language Models (Llms)Model Context Protocols (Mcps)PythonSemantic LayersSnowflakeSQLTerraform

Information Technology • Productivity • Software • Infrastructure as a Service (IaaS)
Design and scale lakehouse architecture, including Bronze, Silver, and Gold data layers. Build reliable streaming and batch pipelines with Kafka, Spark, and Airflow; manage Iceberg, Delta, and Hudi table formats; optimize Trino, Starburst, and Databricks queries; and improve platform reliability, data quality, and performance. Collaborate with data scientists, analysts, and product teams to deliver scalable data platform solutions.
Top Skills:
Apache AirflowApache HudiApache IcebergApache KafkaSparkDatabricksDelta LakeLakehouse ArchitectureMedallion ArchitecturePythonSQLStarburstTrino
Information Technology • Productivity • Software • Infrastructure as a Service (IaaS)
Design and scale lakehouse architecture, streaming and batch pipelines, and reliable data platforms using Kafka, Spark, Airflow, Iceberg, Databricks, and related technologies. Build Medallion-layer data systems, manage open table formats, optimize distributed queries, monitor platform reliability, resolve data quality issues, and collaborate with analysts, data scientists, and product teams.
Top Skills:
Apache AirflowApache HudiApache IcebergApache KafkaSparkDatabricksDelta LakePythonSQLStarburstTrino
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free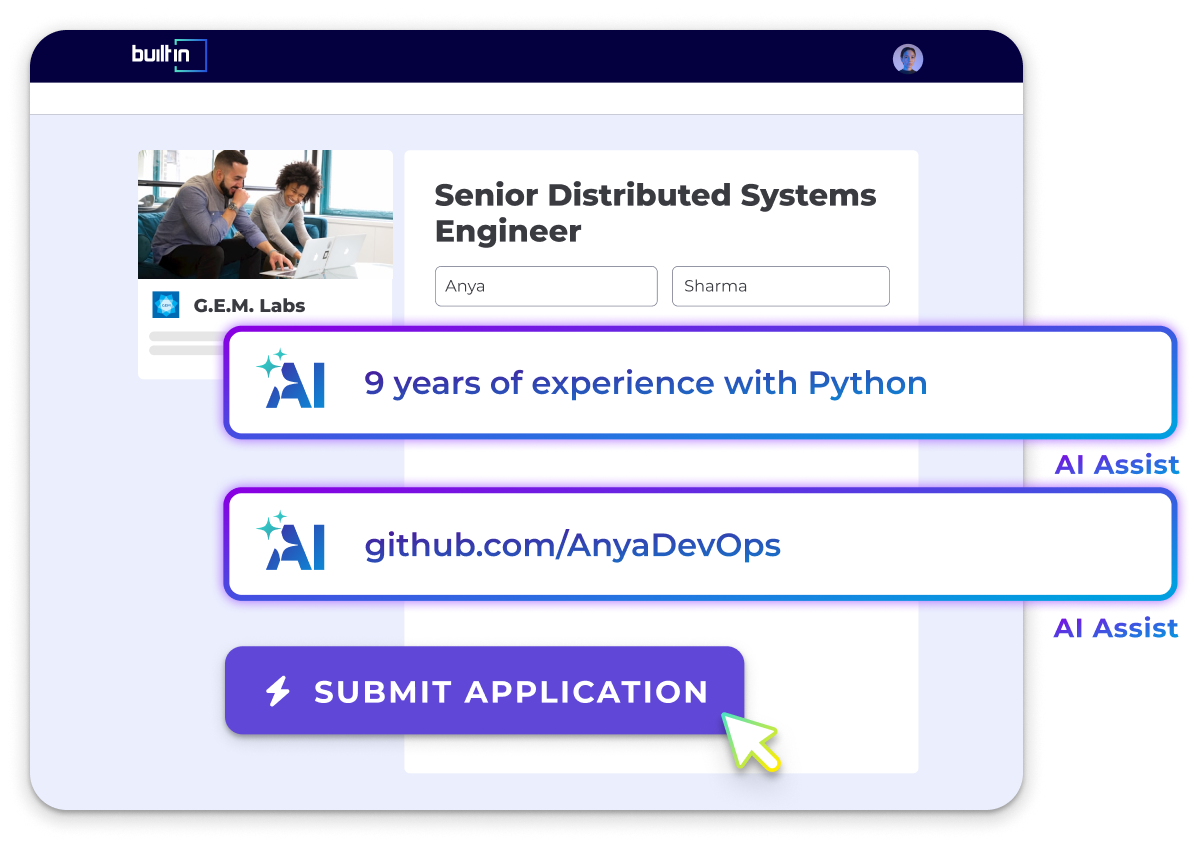
Information Technology • Productivity • Software • Infrastructure as a Service (IaaS)
Build and maintain scalable ETL/ELT pipelines and data foundations using Databricks, dbt, and AWS. Transform raw structured and unstructured data into reliable datasets for product analytics and data science, including telemetry, streaming data, and feature engineering. Develop dashboards in Tableau and Databricks, optimize workflows, and collaborate with Product, Engineering, analytics, and data science stakeholders to support product health, adoption, and performance insights.
Top Skills:
AWSDatabricksDbtPythonSQLTableau
Cloud • Insurance • Payments • Software • Business Intelligence • App development • Big Data Analytics
Build, model, and maintain scalable BigQuery-based data solutions on GCP. Implement performant data models, storage partitioning/clustering, ETL improvements, data validation, and documentation. Collaborate with architects, data scientists, and engineers to deliver governed, high-quality data for reporting and AI initiatives.
Top Skills:
Ansi SqlBigQueryBigquery SqlConfluenceGCPJIRAPythonSQL
Information Technology • Professional Services • Consulting
Build and maintain large-scale data processing pipelines using Apache Spark (PySpark/Scala) and Python. Design ETL workflows, implement distributed data processing, use version control (Git), and work with cloud platforms (GCP/AWS/Azure).
Top Skills:
SparkAWSAzureETLGCPGitPysparkPythonScala
Artificial Intelligence • Cloud • Machine Learning
Designs and maintains cloud data ingestion, ETL/ELT, transformation, integration, synchronization, and data quality processes in Microsoft Fabric. Builds Bronze, Silver, and Gold lakehouse layers; integrates enterprise systems and Ed-Fi REST APIs; performs data mapping, profiling, reconciliation, migration, and troubleshooting. Develops SQL, Python, and PySpark logic, documents pipelines, and collaborates with architects, analysts, governance teams, and source-system owners. Supports Ed-Fi migration planning and operational transition activities.
Top Skills:
Azure Data FactoryBronze-Silver-Gold Medallion ArchitectureEd-Fi Data StandardEd-Fi Ods/ApiMicrosoft FabricMicrosoft Fabric LakehousePysparkPythonRest ApisSQL

Aerospace • Information Technology • Cybersecurity • Defense
Designs, builds, deploys, and maintains scalable data architectures, databases, ETL/ELT pipelines, API integrations, and cloud data solutions in AWS GovCloud. Migrates on-premises databases to cloud platforms, optimizes data models and performance, implements governance and security controls, and supports reporting and analytics. Collaborates with architects, data scientists, and stakeholders while documenting systems and conducting integration, validation, cost, and risk assessments.
Top Skills:
Amazon AuroraAmazon RedshiftApache HadoopApache KafkaSparkAWSAws GovcloudAws RdsCi/CdDebeziumErwin Data ModelerGitlabGoJavaLiquibaseMicrostrategyMySQLOracle Pl/SqlPentahoPostgresPythonRabbitMQScalaSecurity+SQL

Healthtech • Information Technology • Consulting
Designs, builds, and maintains cloud data pipelines and ETL/ELT processes supporting VA healthcare analytics. Responsibilities include patient matching, record linkage, data harmonization, quality management, documentation, performance optimization, and pipeline support. Collaborates with analysts and stakeholders to develop scalable solutions and Power BI reports using Databricks SparkSQL. The role requires federal healthcare data experience, strong SQL or Spark SQL skills, and the ability to obtain a VA Public Trust clearance.
Top Skills:
AnsibleAzure DatabricksFhirHl7OpenshiftPower BIPysparkPythonRed HatSalesforceSpark SqlSQL
Digital Media • Fintech • Information Technology • Machine Learning • Financial Services • Cybersecurity • Automation
Entry-level data engineering development program involving three rotations, cloud-native data platforms, batch and real-time pipelines, distributed systems, ETL/ELT, data modeling, AI platforms, and enterprise data products. Participants use AWS, Spark, Java, Python, SQL, Snowflake, Kafka, and related technologies while gaining experience with LLM architectures, APIs, microservices, and secure production deployments.
Top Skills:
Apache BeamApache FlinkApache KafkaSparkAPIsAWSDjangoEmbeddingsFastapiHadoopJavaLlmsMicroservicesPythonRagSnowflakeSQLVector Databases
3 Days AgoSaved
Digital Media • Fintech • Information Technology • Machine Learning • Financial Services • Cybersecurity • Automation
Data Engineer Interns will gain hands-on experience building batch and real-time data pipelines using AWS, Spark, Java, Python, and SQL. They will learn data modeling, ETL/ELT, distributed systems, streaming technologies, and AI platforms, including LLM, RAG, vector database, and agentic AI architectures. Interns will collaborate with data engineers, contribute to secure data and AI solutions, and participate in mentorship and professional development activities.
Top Skills:
Apache BeamApache FlinkApache KafkaSparkAWSDjangoEltETLFastapiHadoopJavaLlmsMicroservicesPythonRagSnowflake PipeSQLVector Databases
Security
Develops and enhances web-based tools and content management systems through architecture updates, scripting, frontend development, automation, integrations, testing, debugging, and system troubleshooting. The role supports HTML/CSS/JavaScript interfaces, Java and server-side logic, dashboards, search, AI-related features, and data flow between backend and frontend. It also involves customer interaction, IRS feedback analysis, documentation review, and collaboration within Agile teams.
Top Skills:
AgileContent Management SystemsCSSHTML5JavaJavaScriptExcelMicrosoft PowerpointMicrosoft SharepointMicrosoft TeamsMicrosoft VisioMicrosoft Word
Security
Lead the modernization of a healthcare data platform from an MSSQL XML object store to a scalable AWS architecture. Evaluate AWS storage and query services, design SQL reporting layers, architect data migration and metadata strategies, optimize performance and cost, and build CI/CD and infrastructure-as-code pipelines. Partner with business stakeholders, analysts, and C#/.NET engineers to deliver accessible data models and reliable integrations. Document architecture, data flows, and migration processes while supporting healthcare data and compliance requirements.
Top Skills:
Amazon AthenaAmazon AuroraAmazon CloudwatchAmazon DynamodbAmazon OpensearchAmazon RedshiftAmazon S3AWSAws CdkAws CloudformationAws CodebuildAws CodedeployAws CodepipelineAws GlueAws IamAws LambdaC#/.NetEntity FrameworkFhirGitGitHl7JIRAJSONKanbanMicrosoft Sql ServerQuicksightScrumSQLTerraformX12 EdiXML
Software
Supports the design and development of scalable end-to-end data pipelines and cloud data platforms. Responsibilities include improving data reliability and quality, implementing data management practices, supporting automation and process improvements, ensuring secure and cost-effective solutions, and recommending system enhancements. The intern collaborates with global teams and gains hands-on experience in data engineering, project coordination, and innovation management.
Top Skills:
SparkCloud ComputingEltETLNoSQLPower BIPythonRdbmsSQL

Insurance
The Principal Data Engineer designs and builds scalable cloud-native data platforms, pipelines, frameworks, and governed data products supporting analytics, reporting, AI, and operational workloads. Responsibilities include Databricks, Spark, Delta Lake, Azure, SQL Server, batch and streaming processing, data integration, performance optimization, governance, modernization, troubleshooting, architecture reviews, and mentorship. The role provides senior technical leadership without direct people management and supports insurance-domain data across policy, claims, billing, finance, and regulatory functions.
Top Skills:
SparkAzureAzure Data FactoryAzure DevopsAzure Event HubsAzure StorageCi/CdDatabricksDatabricks AssistantDataopsDelta LakeGitGithub CopilotInfrastructure As CodePysparkSQL ServerT-Sql

Healthtech
Design, build, and maintain data pipelines and a Microsoft Fabric data lakehouse to ingest, transform, and secure large datasets. Collaborate with analysts and Power BI developers, ensure data quality, troubleshoot issues, and optimize cloud-based ETL/ELT and warehousing solutions.
Top Skills:
AzureAzure SynapseDatabricksMicrosoft FabricPower BIPysparkPythonSpark

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies Hiring Remote Data Engineers
See All






Popular Remote Job Searches
Remote Analytics Engineer Jobs
Remote Analytics Manager Jobs
Remote Business Analyst Jobs
Remote Business Intelligence Analyst Jobs
Remote Business Systems Analyst Jobs
Remote Compliance Analyst Jobs
Remote Data Analyst Jobs
Remote Data Architect Jobs
Remote Database Administrator Jobs
Remote Database Engineer Jobs
Remote HRIS Analyst Jobs
Remote Machine Learning Engineer Jobs
Remote Pricing Analyst Jobs
Remote Program Analyst Jobs
Remote Research Jobs
Remote Senior Business Analyst Jobs
Remote Senior Data Analyst Jobs
All Filters
Total selected ()
No Results
No Results
