

Maximum of 25 job preferences reached.
Top Data Engineer Jobs in Gurgaon

Reposted 22 Days AgoSaved
Agency • Information Technology
Design and implement data federation and lakehouse architectures (Starburst/Trino), build scalable ETL/ELT pipelines using Python and Spark, optimize Spark and federated queries, manage Delta/Iceberg/Hudi tables, and enforce governance, access control, and data masking for analytics and AI use.
Top Skills:
AdlsApache IcebergSparkAws EmrAzure DatabricksDbtDelta LakeDremioGCPGlueHudiKubernetesMedallion ArchitecturePrestoPulumiPysparkPythonS3Snowflake SchemaSQLStar SchemaStarburst EnterpriseTerraformTrino

AdTech • Marketing Tech
Design, deploy, and monitor data collection pipelines (Adverity). Build ETL/DBT transformations in Google Cloud Platform, implement data quality checks, troubleshoot automated jobs, support dashboards (Google Data Studio/PowerBI), translate business needs to technical specs, mentor junior staff, and manage third-party data provider relationships.
Top Skills:
AdverityDbtETLFacebookGoogle Cloud PlatformGoogle Data StudioGoogle Marketing PlatformPower BIPythonSQLTiktok

Agency • Digital Media • eCommerce • Social Media
Build, operate, and scale ingestion pipelines for marketing data (ad platforms, ecommerce, analytics). Normalize and transform data into shared schemas, ensure multi-tenant reliability, observability, and security, and partner with AI/data-science teams to expose clean data for agents.
Top Skills:
AirflowBigQueryCloud RunDagsterDbtGa4GCPGoogleKlaviyoLangfuseMetaOauthPgvectorPostgresPythonRedshiftShopifySnowflakeSQLTiktok

Healthtech • HR Tech • Insurance • Consulting
Support design, development, and implementation of application and A2A integrations; migrate legacy processes to a centralized platform; build data integration pipelines and workflows using tools like ADF, Boomi, Snaplogic, or Workato; assist with data mapping, profiling, validation, automation, CI/CD, and adherence to data governance and security standards.
Top Skills:
AWSAzureAzure Data FactoryAzure FabricBoomiCi/CdGCPPythonRelational DatabasesSnaplogicSQLWorkato

Cloud • HR Tech • Information Technology
Design, build and maintain high-volume ETL/ELT pipelines across Hadoop and AWS. Develop distributed PySpark/Scala data processing, implement serverless data architectures (Glue, Lambda, Step Functions), optimize workflows (partitioning, file formats), ensure data governance/security, orchestrate jobs (Airflow/Control-M), troubleshoot Spark performance, and collaborate with stakeholders to deliver scalable data warehousing solutions.
Top Skills:
AirflowAws Step FunctionsCi/CdClouderaControl-MDockerEcsEksEmrGitGitGlueHadoopHdfsHiveHiveqlImpalaKafkaKinesisLambdaOrcParquetPysparkPythonRedshiftS3ScalaShell ScriptingSparkSpark Sql
Healthtech • HR Tech • Insurance • Consulting
Lead design and implement Microsoft Fabric-based data architecture and Lakehouse patterns. Own ingestion, pipeline design, bronze/silver/gold layers, data quality, profiling, validation, and analytics-ready feature datasets. Partner with actuarial teams, provide technical direction and code reviews, coordinate Fabric configuration and security, and document data models, transformation logic, and operational procedures.
Top Skills:
Azure Data ServicesGCPLakehouseMicrosoft FabricNotebooksOnelakePipelinesPythonSparkSQL

Security • Software • Cybersecurity
Designs and operates scalable data and machine learning platforms using Databricks, Python, SQL, Spark, and PySpark. Builds batch, streaming, and production ML pipelines; manages Delta Lake, Unity Catalog, Workflows, MLflow, governance, data quality, observability, and model deployment. Partners with data scientists and business teams, optimizes performance and costs, contributes to platform architecture, mentors engineers, and documents operational practices.
Top Skills:
Ai FunctionsAmazon KinesisSparkAWSAzureCdcCi/CdDatabricksDatabricks Asset BundlesDatabricks Feature StoreDatabricks WorkflowsDbtDelta LakeFeastGCPGenieGitGreat ExpectationsKafkaLlmMlflowMonte CarloPysparkPythonRagSpark Structured StreamingSQLTectonTerraformUnity Catalog

Marketing Tech • Software
The Senior Data Engineer will design, build, and maintain data platforms and pipelines, ensuring data security and efficiency while collaborating with stakeholders.
Top Skills:
Azure FabricDatabricksHadoopKafkaPythonSnowflakeSparkSQL
Agency • Information Technology
Design, build and maintain cloud-oriented big data solutions for ingestion, processing, cleaning and exposition. Improve data quality, implement ETL and data-warehouse architectures, and collaborate with DDS/Data Foundation teams to ensure platform reliability.
Top Skills:
Data WarehousingETLHadoopJavaLinuxPythonScalaSparkSQLUnix
Agency • Information Technology
Design, implement, and optimize Apache DolphinScheduler workflows and ETL pipelines. Integrate with Hadoop, Spark, Flink, Hive, and Kafka. Develop custom plugins, troubleshoot performance and scalability issues, monitor job execution and resource allocation, and maintain CI/CD, version control, and infrastructure automation while collaborating with data engineers and DevOps teams.
Top Skills:
Apache DolphinschedulerCi/CdDevOpsFlinkHadoopHiveJavaKafkaPythonScalaSparkVersion Control
Agency • Information Technology
Design, build, and optimize PySpark applications and ETL pipelines to process large-scale datasets from relational, NoSQL, file, and streaming sources. Ensure data quality, implement error handling, and collaborate with analysts, scientists, and architects to deliver performant data solutions.
Top Skills:
Apache AirflowSparkData LakeLuigiNoSQLPysparkPythonSQLStreaming Platforms
New
Track Smarter, Apply Better.
Ditch the spreadsheets. Organize your job search with our freeApplication Tracker.
Use For Free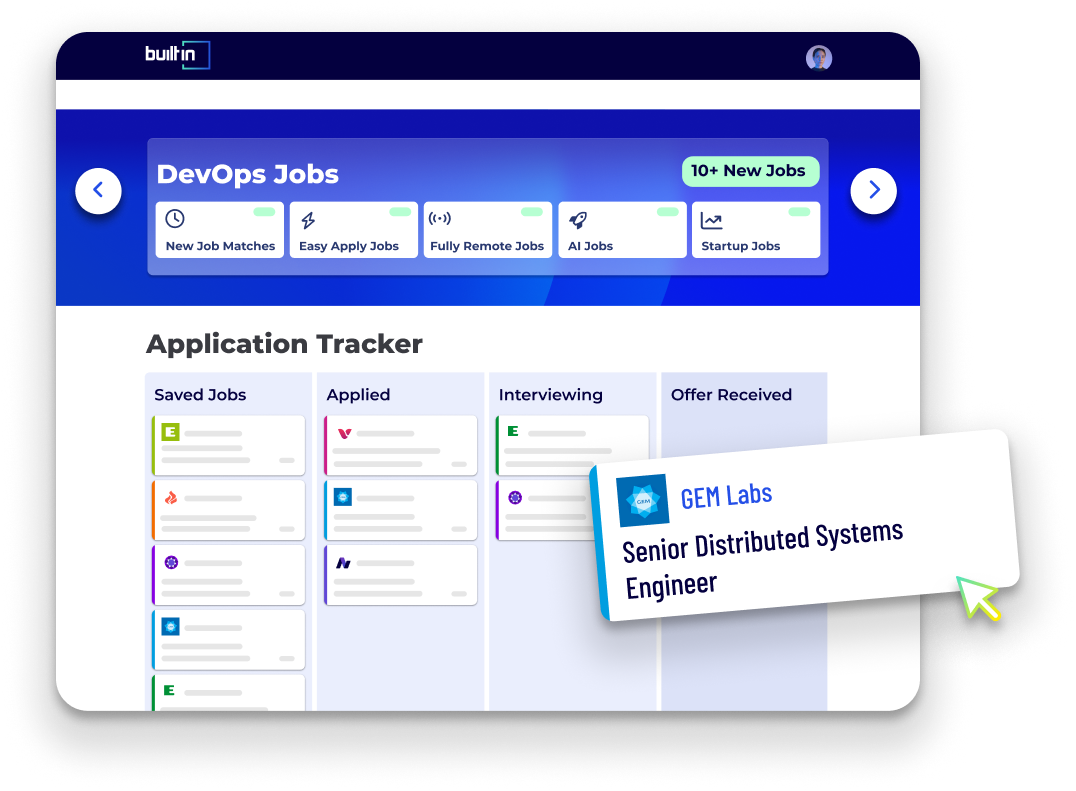
Agency • Information Technology
Design, develop, test, and deploy high-performance Spark/Scala data processing applications and ETL pipelines on Cloudera (CDH). Optimize Spark and Cloudera platform performance, integrate HDFS/Hive/Impala/HBase/Kafka, ensure data integrity/security, and implement version control and CI/CD for production pipelines.
Top Skills:
SparkCloudera CdhFlumeGitGitlabHbaseHdfsHiveImpalaJenkinsKafkaNifiOoziePostgresScalaSpark SqlSQLSqoop

Software
Lead the design, build, and ownership of a greenfield data platform and scalable batch and real-time pipelines. Embed AI across the data lifecycle, ensure data quality and governance, optimize pipeline performance, document best practices, and lead and mentor a team of data engineers while collaborating with cross-functional stakeholders.
Top Skills:
Apache AirflowApache FlinkApache IcebergApache ParquetAws AthenaAws EmrAws GlueAws KinesisAws S3Change Data Capture (Cdc)Delta LakeHudiKafka StreamsNoSQLPysparkPythonSQL

Software
As a Senior Engineer for Strategic Data Solutions, you will manage data warehousing, reporting, and analytics for internal operations and external partners. Responsibilities include collaborating with business units, providing insights, and ensuring high-quality data reporting.
Top Skills:
JIRALookerMetabasePythonSQLStriim TqlTableau
Healthtech • HR Tech • Insurance • Consulting
The Data and Application Integration Engineer will design and implement application integrations, migrate legacy processes, manage data quality, and support CI/CD pipelines.
Top Skills:
Azure CloudAzure Data FactoryBoomiPythonSnaplogicSQLWorkato

Artificial Intelligence • Insurance • Software • Automation
Design and own end-to-end data platform architecture, build ingestion and transformation pipelines, model multi-tenant datasets, optimize Postgres and ClickHouse performance/cost, implement orchestration and observability, define data quality and reconciliation standards, and mentor data/product engineers.
Top Skills:
AirflowClickhouseDagsterPostgresPythonSQLTemporal
Software
As a Data Engineer, you will design and develop data pipelines, ensuring data quality and scalability. You'll collaborate with teams to meet business needs and mentor junior members.
Top Skills:
Apache AirflowApache FlinkApache IcebergApache ParquetAws Data ServicesDelta LakeHudiKafka StreamsPysparkSQL

Greentech • Energy • Solar • Renewable Energy
Own and automate end-to-end incentive calculation pipelines, translate business rules into auditable data workflows, build monitoring and reconciliation dashboards, ensure accuracy and auditability across multiple products and countries, and partner with Sales, Finance, and field teams to resolve discrepancies and support escalations.
Top Skills:
AirflowBitbucketGitLookerPythonRedshiftSQLTableau

Big Data • eCommerce
Build and maintain end-to-end data pipelines using PySpark and SQL on Databricks/Delta. Establish data modeling and pipeline best practices, create AI-ready analytical datasets, troubleshoot pipeline issues, and collaborate with stakeholders to embed business logic and optimize reliability, efficiency, and performance.
Top Skills:
AirflowDatabricksDbtDeltaDelta LakeETLPysparkSnowflakeSparkSQL

Software
As a Data Engineer, you'll build and monitor large-scale data pipelines, develop the DBT setup for data transformation and solve customer problems using your SQL skills.
Top Skills:
Big DataDbtSQL

Big Data • Marketing Tech
Design, build, and optimize high-volume data pipelines using Python, Databricks and Spark on Azure. Create and maintain automation test suites (Azure DevOps), perform manual/load/exploratory testing, collaborate with BAs and developers to meet sprint goals, and assist with sprint estimation and delivery.
Top Skills:
Ai/MlSparkAzureAzure DevopsCi/CdDatabricksDevOpsPysparkPython

eCommerce • Marketing Tech • Software
Design, build, and operate scalable data engineering services and ingestion pipelines (CDC/streaming). Develop and optimize a centralized analytics warehouse, data models, and aggregation strategies. Build APIs, enforce multi-tenant security and data governance, monitor pipeline health, improve automation and observability, and ensure production reliability through strong engineering practices.
Top Skills:
Amazon RedshiftBigQueryCdcClickhouseDataflowDebeziumFlinkGCPGoKafkaPostgresPulsarPythonSnowflakeSQLTerraformTimescaledb

Analytics
The Senior Data Scientist & Engineer will build and manage data infrastructure, analyze product usage, build models, track metrics, run experiments, and communicate insights to guide product decisions.
Top Skills:
AirflowBigQueryDagsterDatabricksDbtLlmPythonSnowflakeSparkSQL

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Gurgaon Companies Hiring Data Engineers
See All






Popular Job Searches in Gurgaon
Tech Jobs in Gurgaon
IT Jobs in Gurgaon
Cyber Security Jobs in Gurgaon
Technical Support Jobs in Gurgaon
Business Analyst Jobs in Gurgaon
Business Intelligence Jobs in Gurgaon
Data Analyst Jobs in Gurgaon
Data Engineer Jobs in Gurgaon
Data Science Jobs in Gurgaon
Android Developer Jobs in Gurgaon
Artificial Intelligence Jobs in Gurgaon
C++ Jobs in Gurgaon
DevOps Jobs in Gurgaon
Engineering Manager Jobs in Gurgaon
Front End Developer Jobs in Gurgaon
Golang Jobs in Gurgaon
iOS Developer Jobs in Gurgaon
Java Developer Jobs in Gurgaon
Linux Jobs in Gurgaon
Machine Learning Jobs in Gurgaon
.NET Developer Jobs in Gurgaon
PHP Developer Jobs in Gurgaon
Python Developer Jobs in Gurgaon
QA Jobs in Gurgaon
React Developer Jobs in Gurgaon
Ruby on Rails Jobs in Gurgaon
Salesforce Developer Jobs in Gurgaon
Software Engineer Jobs in Gurgaon
Operations Manager Jobs in Gurgaon
Product Manager Jobs in Gurgaon
Project Manager Jobs in Gurgaon
More Tech Jobs in India
Tech Jobs & Startup Jobs in India
Software Engineer Jobs in India
Data Science Jobs in India
Machine Learning Jobs in India
Artificial Intelligence Jobs in India
Product Manager Jobs in India
Front End Developer Jobs in India
QA Engineer Jobs in India
Remote Jobs in India
Tech Jobs & Startup Jobs in Bangalore
All Filters
Total selected ()
No Results
No Results
