It all started when engineer Fred Luddy wrote code that automated a tedious task for his coworker, Phyllis. She cried tears of joy. That moment inspired Fred to build a company that could do that for everyone—freeing people from busywork so they could focus on meaningful work. Today, ServiceNow is the AI control tower for business reinvention. Our ServiceNow AI platform brings together any AI, any data, and any workflow— helping 85% of the Fortune 500® work smarter, faster, and better. We're building an AI-native culture where technology and talent are unstoppable together. And we're just getting started.
Join us to put AI to work for people.
Job Description
Team:
Our Site Reliability Engineering (SRE) team consists of highly skilled engineers responsible for maintaining and enhancing the reliability, scalability, and performance of the ServiceNow infrastructure. Our SRE’s are empowered to resolve technical issues across the entire technology stack, from hardware to applications. Additionally, they work to improve the platform's operability, aiming to reduce the number of incidents and minimize Mean Time to Recovery (MTTR). To achieve this, the team combines software development, networking, database, and systems engineering skills to tackle complex problems, striving to maintain our platform operating for our customers.
Role:
We are looking for a Director of Site Reliability Engineering to lead the next phase of our reliability transformation as ServiceNow modernizes toward a cloud-agnostic, cloud-ready production platform.
This leader will own key elements of the SRE operating model across Reliability Engineering, Service Enablement, Service Registry, SLI/SLO standards, reliability governance, automation, AI-enabled operations, and production readiness. The role will lead a global engineering organization and partner across Product Engineering, Infrastructure, Architecture, Security, Release Engineering, and Customer Support to establish consistent reliability practices across ServiceNow products and services.
The Director will play a critical role in evolving the organization from reactive operations toward an engineering-led SRE model focused on prevention, automation, resilience, and continuous improvement.
What you get to do in this role:
- Define and execute the SRE strategy and operating model across reliability engineering, service enablement, observability, automation, incident learning, and production readiness.
- Lead and develop a global organization of engineering managers, technical leaders, and SREs.
- Establish enterprise reliability standards for service ownership, tiering, golden signals, SLIs/SLOs, error budgets, alerting, on-call practices, and service health reviews.
- Lead the Service Enablement strategy by establishing minimum reliability requirements and maturity standards for critical services.
- Own the Service Registry strategy, improving service ownership, dependency visibility, maturity tracking, and impact-aware operational decision-making.
- Drive adoption of SLIs, SLOs, error budgets, and burn-rate alerting across critical services, ensuring teams consistently use reliability signals to manage customer impact.
- Build a culture of engineering away toil by turning recurring operational work and incident patterns into automation, self-service, and systemic fixes.
- Establish the AI-enabled SRE roadmap, including change-risk assessment, operational insights, remediation recommendations, and policy-driven automation.
- Drive reliability and production-readiness strategy across AWS, Azure, and GCP by establishing cloud-agnostic patterns while addressing hyperscaler-specific operational requirements.
- Partner with product and platform engineers to design, launch, and operate reliable services throughout the production lifecycle.
- Establish launch and production-readiness practices that validate availability, latency, performance, capacity, dependencies, rollback, and recovery before customer impact.
- Drive sustainable operations by scaling self-service capabilities, automation platforms, and systemic reliability improvements across engineering teams.
- Lead incident response, blameless postmortems, and corrective actions that convert production failures into lasting reliability improvements.
- Measure reliability through SLIs, SLOs, error budgets, golden signals, change failure rate, MTTR, capacity health, and toil reduction.
- Influence architecture and platform direction to simplify operating models and improve reliability across ServiceNow's global infrastructure.
- Partner with executive and engineering leaders to prioritize reliability investments and drive adoption beyond the direct SRE organization.
To be successful in this role you have:
- Experience in leveraging or critically thinking about how to integrate AI into work processes, decision-making, or problem-solving. This may include using AI-powered tools, automating workflows, analyzing AI-driven insights, or exploring AI's potential impact on the function or industry.
- 12 years of significant leadership experience in Site Reliability Engineering, Production Engineering, Platform Engineering, Cloud Infrastructure, or large-scale distributed systems with a Bachelor's degree; or 8 years and a Master's degree; or a PhD with 5 years experience; or equivalent experience.
- Proven success leading managers and senior technical leaders across geographically distributed engineering organizations.
- Demonstrated success leading SRE, infrastructure, or reliability transformation at scale.
- Strong understanding of SLIs/SLOs, error budgets, observability, incident management, reliability governance, and on-call practices.
- Experience with service catalogs, service registries, service ownership models, Backstage, CMDB, dependency mapping, or service topology.
- Strong background in cloud infrastructure and modernization across AWS, Azure, and/or GCP.
- Understanding of Kubernetes, distributed systems, networking, databases, infrastructure automation, and cloud-native architecture.
- Experience driving automation through orchestration, Infrastructure as Code, self-service platforms, and auto-remediation.
- Familiarity with AI-assisted operations, autonomous remediation, or agentic technologies is highly desirable.
- Experience establishing production-readiness practices for releases, resilience, disaster recovery, infrastructure changes, and cloud migrations.
- Ability to use incident, reliability, and operational data to prioritize engineering work and drive systemic improvements.
- Strong cross-functional influence and executive communication skills.
- Ability to operate effectively through ambiguity, organizational transformation, and large-scale technical change.
For positions in this location, we offer a base pay of $221,200 - $387,100, plus equity (when applicable), variable/incentive compensation and benefits. Sales positions generally offer a competitive On Target Earnings (OTE) incentive compensation structure. Please note that the base pay shown is a guideline, and individual total compensation will vary based on factors such as qualifications, skill level, competencies, and work location. We also offer health plans, including flexible spending accounts, a 401(k) Plan with company match, ESPP, matching donations, a flexible time away plan and family leave programs. Compensation is based on the geographic location in which the role is located and is subject to change based on work location.
Additional InformationWork Personas
We approach our distributed world of work with flexibility and trust. Work personas (flexible, remote, or required in office) are categories that are assigned to ServiceNow employees depending on the nature of their work and their assigned work location. Learn more here. To determine eligibility for a work persona, ServiceNow may confirm the distance between your primary residence and the closest ServiceNow office using a third-party service.
Equal Opportunity Employer
ServiceNow is an equal opportunity employer. All qualified applicants will receive consideration for employment without regard to race, color, religion, sex, sexual orientation, national origin, age, disability, gender identity, veteran status, or any other category protected by law. In addition, all qualified applicants with arrest or conviction records will be considered for employment in accordance with legal requirements.
Accommodations
We strive to create an accessible and inclusive experience for all candidates. If you require a reasonable accommodation to complete any part of the application process, or are unable to use this online application and need an alternative method to apply, please contact [email protected] for assistance.
Export Control Regulations
For positions requiring access to controlled technology subject to export control regulations, including the U.S. Export Administration Regulations (EAR), ServiceNow may be required to obtain export control approval from government authorities for certain individuals. All employment is contingent upon ServiceNow obtaining any export license or other approval that may be required by relevant export control authorities.
From Fortune. ©2026 Fortune Media IP Limited. All rights reserved. Used under license.
Skills Required
- Experience integrating or critically evaluating AI in work processes, decision-making, or problem-solving
- 12 years of significant leadership experience in Site Reliability Engineering, Production Engineering, Platform Engineering, Cloud Infrastructure, or large-scale distributed systems with a Bachelor's degree; 8 years with a Master's degree; 5 years with a PhD; or equivalent experience
- Experience leading managers and senior technical leaders across geographically distributed engineering organizations
- Success leading SRE, infrastructure, or reliability transformation at scale
- Strong understanding of SLIs/SLOs, error budgets, observability, incident management, reliability governance, and on-call practices
- Experience with service catalogs, service registries, service ownership models, Backstage, CMDB, dependency mapping, or service topology
- Strong background in cloud infrastructure and modernization across AWS, Azure, and/or GCP
- Understanding of Kubernetes, distributed systems, networking, databases, infrastructure automation, and cloud-native architecture
- Experience driving automation through orchestration, Infrastructure as Code, self-service platforms, and auto-remediation
- Familiarity with AI-assisted operations, autonomous remediation, or agentic technologies
- Experience establishing production-readiness practices for releases, resilience, disaster recovery, infrastructure changes, and cloud migrations
- Ability to use incident, reliability, and operational data to prioritize engineering work and drive systemic improvements
- Strong cross-functional influence and executive communication skills
- Ability to operate effectively through ambiguity, organizational transformation, and large-scale technical change
What the Team is Saying




ServiceNow Compensation & Benefits Highlights
-
Healthcare Strength — Health coverage is described as comprehensive with multiple plan choices and strong perceived coverage, alongside mental-health resources and wellbeing support. Company materials and employer-verified summaries also note inclusive care options and supportive programs.
-
Parental & Family Support — Parental leave and family-planning support are characterized as generous, with fully paid leave and resources such as fertility, caregiving, and adoption assistance. Backup care and other family-focused programs are also highlighted as part of the package.
-
Equity Value & Accessibility — Equity components like RSUs and an employee stock purchase plan are presented as meaningful, widely available parts of total rewards. Many role and benefits overviews emphasize equity’s role in boosting overall compensation alongside bonuses.
ServiceNow Insights

What We Do
As the AI platform for business transformation, we're putting AI to work across organizations — freeing people for work that matters. Making old tech work with new tech. Reaching across departments, from the front office to the back office and every office in between. Our ambition? To become the AI defining enterprise software company of the 21st century (or "AI DESCO21C," as we like to call it). With more than 8,400+ customers, we serve approximately 90% of the Fortune 500®, and we're proud to be a Fortune 100 Best Companies to Work For® and World's Most Admired Companies™. Explore your future career with us, visit www.careers.servicenow.com From Fortune. ©2026 Fortune Media IP Limited. All rights reserved. Used under license.
Why Work With Us
By joining ServiceNow, you are part of an ambitious team of change-makers who have a restless curiosity and a drive for ingenuity. We're committed to helping our people do their best work and live their best lives so we can fulfill our purpose together. At the fastest-growing enterprise software company, you can grow your career faster.
Gallery



ServiceNow Offices
Hybrid Workspace
Employees engage in a combination of remote and on-site work.
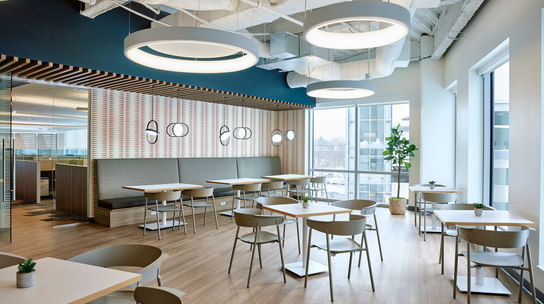
At ServiceNow, we lead with flexibility and trust. For some, home is the primary workplace. For those who come into a ServiceNow workplace, you are empowered to make team-guided and individual-led decisions on how and when you use the workplace.