

Maximum of 25 job preferences reached.
Top Artificial Intelligence DevOps & Platform Engineering Jobs

Aerospace • Artificial Intelligence • Robotics • Defense
Build telemetry and observability across AI training, data, infrastructure, models, agents, and missions. The role establishes shared telemetry schemas, instruments distributed workloads and agent workflows, connects mission context to model behavior, and develops service objectives, alerts, reliability mechanisms, capacity and cost visibility, and incident tooling. Success requires correlating operational, scientific, and AI-system signals to diagnose failures and support safe deployments.
Top Skills:
APIsCloud InfrastructureDistributed InferenceDistributed TrainingEdge DeploymentsEventsGeospatial PipelinesGpu WorkloadsIncident ToolingInfrastructure AutomationLogsMetricsMl ObservabilityMlopsModel ServingProduction Ai PlatformsReinforcement-Learning EnvironmentsStreaming SystemsTelemetryTime-Series SystemsTraces

Artificial Intelligence • Healthtech
Lead and grow the platform engineering team responsible for infrastructure, developer productivity, deployment, observability, reliability, security, and cost optimization. Set technical direction, guide architecture, contribute to production code and automation, improve CI/CD and engineering workflows, build AI-native development tooling, lead incident response, and hire and coach engineers.
Top Skills:
Application Load BalancerAWSCi/CdCloudfrontCloudwatchDockerDocumentdbEcrEcsGithub ActionsIamInfrastructure As CodePythonRdsRedisS3Secrets ManagerShellTerraformTerragrunt

Artificial Intelligence • Fintech • Software
Build and own developer infrastructure including deployment pipelines, environments, infrastructure-as-code, observability, security, internal tooling, and AI tool hosting. Improve deployment safety, environment parity, developer productivity, incident management, and platform standards. Partner directly with engineers to create reliable self-service systems and shared infrastructure using AWS, containers, Terraform/OpenTofu, CI/CD, and observability tools.
Top Skills:
AWSClickhouseContainersDatadogDockerEcrEcsGithub ActionsIamInngestLinuxMcpNode.jsOpentofuPostgresPythonRdsS3SpaceliftTerraformTypescript
Artificial Intelligence • Information Technology • Software
Build and operate AWS infrastructure using Terraform and Kubernetes, develop reusable infrastructure modules, create reliable CI/CD workflows, and improve autoscaling, observability, incident response, and deployment safety. The role partners with application and AI engineers to support latency-sensitive voice services, manage costs, and enable secure provisioning and debugging. Nice-to-have experience includes GitOps, real-time audio systems, databases, GPU workloads, AI inference, and SOC 2 support.
Top Skills:
Amazon EksArgo CdAWSCi/CdGoHelmIamKubernetesLinuxPostgresPythonRedisSipTerraformTypescriptWebrtc
Artificial Intelligence • App development
Lead the GPU cluster infrastructure team while remaining at least 50% hands-on. Own technical direction, architecture, scheduling, storage, security, infrastructure as code, observability, incident response, and platform roadmap. Manage hiring, coaching, project prioritization, and provider and researcher escalations. Operate production Kubernetes GPU clusters across multiple providers and improve performance, reliability, fault tolerance, and workload isolation for large-scale AI research.
Top Skills:
AnsibleArgocdC++CephDcgmFirecrackerGoGpusGvisorHelmInfinibandKataKubernetesKueueLinuxLustreNcclNvidia Gpu OperatorPrometheusPythonPyTorchRbacRoceRustSlurmTerraformVastVolcanoWeka
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free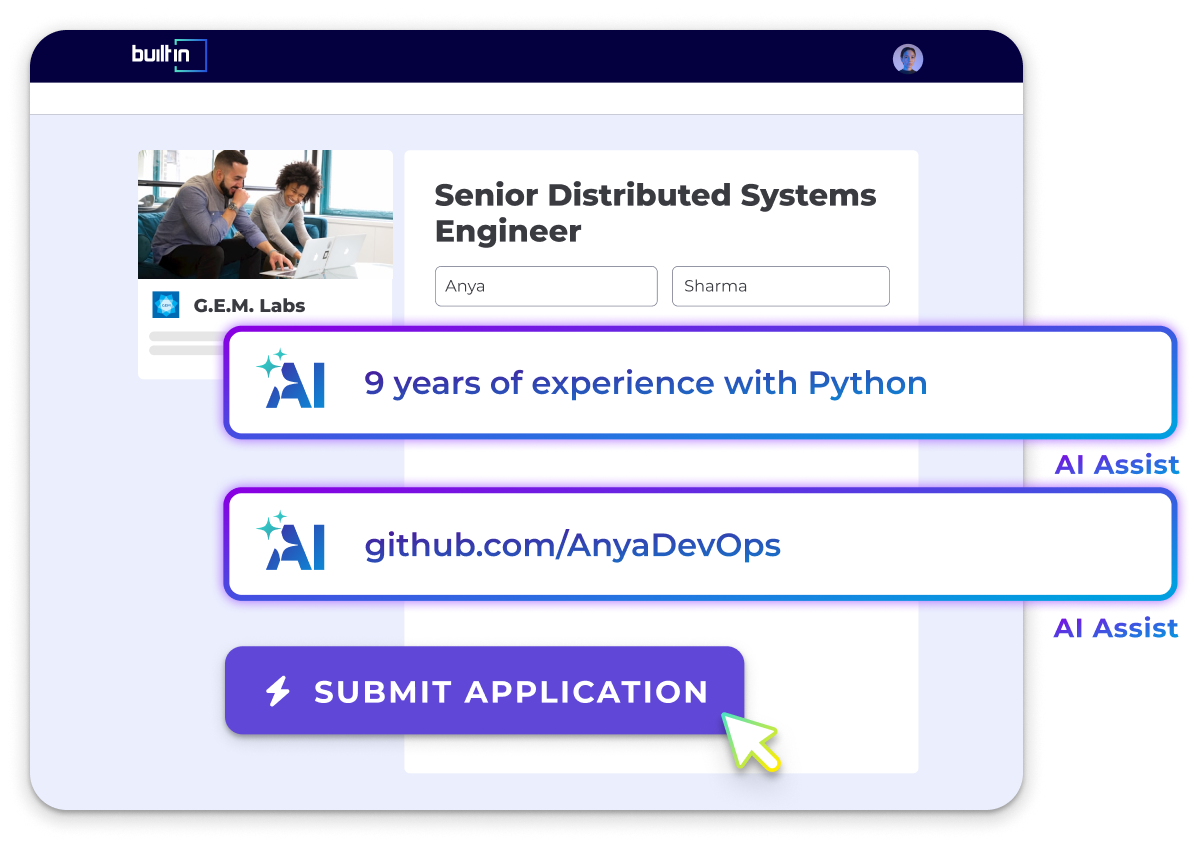
Artificial Intelligence • Cloud • Information Technology • Internet of Things • Software
Monitor and maintain enterprise and operational technology networks, troubleshoot faults, resolve incidents, support telecom and microwave backhaul systems, administer Linux environments, coordinate vendors, perform maintenance and configuration changes, and produce incident and root cause documentation. This onsite, shift-based role supports high availability across critical infrastructure and requires participation in on-call operations.
Top Skills:
Centralized Traffic ControlDhcpDnsFirewallsLinuxMicrowave RadioNagiosNetwork Monitoring ToolsPositive Train ControlPrtgRoutersRouting & SwitchingScada/OtSolarwindsSwitchesTcp/IpTelecom Backhaul SystemsVlansVpnsWanZabbix
Artificial Intelligence • Semiconductor
Design, build, and maintain backend services, platform infrastructure, and cloud deployments. Debug distributed production systems, architect IaC and networking, provision on-prem hardware, support customer deployments and integrations, and collaborate with research, product, and customer success to deliver reliable, scalable production software.
Top Skills:
AWSAzureCloudFormationDockerGCPGoIacJavaKubernetesPulumiTerraformTypescript

Artificial Intelligence • Software
Build and operate CrewAI’s cloud and enterprise infrastructure across AWS, Azure, and GCP. Develop CI/CD pipelines, deployment automation, observability, security controls, self-hosted installation tooling, and reliability processes. Support containers, Kubernetes, databases, queues, networking, secrets, and production workloads. Participate in incident response and on-call operations while partnering with runtime and product engineering teams to improve deployment safety, scalability, and customer production environments.
Top Skills:
AWSAzureBashCeleryCi/CdDockerEcrEcsFastapiGCPGithub ActionsGoHelmIamKubernetesOpentelemetryPostgresPythonRuby on RailsRedisRubySentrySolid QueueTerraform

Artificial Intelligence • Computer Vision • Machine Learning • Analytics
Design and scale infrastructure for cloud and on-premises deployments supporting enterprise AI workloads. Build containerized systems, Kubernetes and Docker Compose deployments, Helm charts, CI/CD pipelines, infrastructure automation, monitoring, and security solutions. Support customer production deployments, troubleshoot distributed systems, improve developer productivity, mentor engineers, and establish infrastructure standards across engineering teams.
Top Skills:
AnsibleAWSAzureBashCi/CdDockerDocker ComposeGCPGithub ActionsGkeGoogle Cloud BuildHelmIamKubernetesMongoDBNoSQLPythonTerraformVpc
Artificial Intelligence • Healthtech • Robotics
Lead and mentor infrastructure and web platform engineers while contributing hands-on to cloud infrastructure, DevOps, compliance, and internal web tools. Define technical direction, standardize Terraform across AWS environments, oversee SOC2 and HIPAA compliance, support manufacturing and service workflows, and improve security, observability, automation, scalability, and availability. Collaborate with engineering, clinical, product, hardware, and regulatory stakeholders.
Top Skills:
AWSCloudwatchLinuxPrometheusSplunkTerraform

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies Hiring Engineering Roles
See All






All Filters
Total selected ()
No Results
No Results
