


As a Data Scientist on the AI & ML (Data Collection) team, you will own AI-powered solutions that extract structured information from PitchBook's reports, news, and other content. You will apply data analysis, machine learning, natural language processing (NLP), and generative AI to improve the quality, coverage, and timeliness of PitchBook data.
You will take end-to-end responsibility for data science initiatives, from problem definition, data exploration, and success metrics through model development, evaluation, production deployment, monitoring, and continuous improvement. Your work may include large language models (LLMs), retrieval-augmented generation (RAG), agentic workflows, and other information-extraction techniques.
You will collaborate with Product Managers, Machine Learning Engineers, Software Engineers, and domain experts to deliver scalable solutions. You will remain accountable for model quality and business impact after launching by evaluating performance, investigating regressions, and guiding improvements through data and experimentation. You will also contribute through peer reviews, reproducible work, documentation, and knowledge sharing.
You will join a multidisciplinary team of Data Scientists and Machine Learning Engineers developing AI and ML capabilities for PitchBook's data collection pipelines. Data Scientists own the analytical and modeling lifecycle and partner with engineering teams to operationalize, scale, and maintain successful solutions.
Primary Job Responsibilities:
- End-to-End Data Science Ownership: Own extraction and enrichment problems from discovery through production and continuous improvement. Define the problem, select data and methods, establish success criteria, evaluate results, and monitor outcomes
- Problem Formulation & Data Strategy: Translate business requirements into measurable data science problems. Explore structured and unstructured data, identify quality and source-variability issues, and define training, validation, test, and labeling requirements with domain partners
- Model Development & Experimentation: Design and optimize NLP, machine learning, and LLM solutions for document understanding and information extraction
- Extraction Solution Development: Build extraction workflows using document parsing, preprocessing, chunking, feature engineering, embeddings, RAG, prompt engineering, fine-tuning, and agentic approaches
- Evaluation & Error Analysis: Create representative evaluation datasets and metrics such as precision, recall, F1, field-level accuracy, coverage, confidence, and business impact. Use error analysis to guide model, prompt, data, and workflow improvements
- Productionization & Model Ownership: Develop robust, testable model components and partner with ML Engineers to integrate solutions into production. Monitor quality, investigate regressions or drift, and prioritize improvements based on customer and business impact
- Technical Trade-offs & Quality: Evaluate accuracy, coverage, latency, scalability, robustness, and cost. Recommend approaches using empirical evidence, write maintainable code, and document datasets, assumptions, experiments, limitations, and results
- Collaboration & Innovation: Partner with Product, Data Collection, Engineering, Platform, and domain teams. Evaluate advances in NLP, generative AI, LLMs, and information extraction, and apply methods that deliver measurable value
Skills and Qualifications:
- Bachelor's or Master's degree in Data Science, Computer Science, Statistics, Mathematics, Economics, Engineering, or a related quantitative field
- 2+ years of experience in applied data science, machine learning, NLP, or information extraction
- Demonstrated experience taking a data science or machine learning solution from problem definition and experimentation through production launch and ongoing improvement
- Experience analyzing large, complex structured and unstructured datasets, including exploration, preprocessing, feature engineering, sampling, labeling, and dataset construction
- Hands-on experience developing document intelligence or information-extraction solutions using techniques such as transformers, embeddings, RAG, LLMs, prompt engineering, fine-tuning, or agentic workflows
- Strong understanding of experimental design, statistical reasoning, model evaluation, error analysis, and metrics such as precision, recall, F1, field-level accuracy, confidence, and coverage
- Proficiency in Python and SQL, with experience using pandas, NumPy, scikit-learn, and PyTorch or TensorFlow
- Experience with Hugging Face, LangChain, or comparable NLP and LLM frameworks; ability to write maintainable, testable model and data-processing code
- Familiarity with cloud ML environments, version control, automated testing, model monitoring, containers, or data orchestration tools is beneficial
- Strong communication and collaboration skills, including the ability to explain model behavior, limitations, trade-offs, and recommendations; experience with financial data, document intelligence, or large-scale data collection is a plus
Working Conditions
The job conditions for this position are in a standard office setting. Employees in this position use PC and phones on an ongoing basis throughout the day. Limited corporate travel may be required to remote offices or other business meetings and events.
Morningstar's hybrid work environment gives you the opportunity to collaborate in-person each week as we've found that we're at our best when we're purposely together on a regular basis. In most of our locations, our hybrid work model is four days in-office each week. A range of other benefits are also available to enhance flexibility as needs change. No matter where you are, you'll have tools and resources to engage meaningfully with your global colleagues.
I10_MstarIndiaPvtLtd Morningstar India Private Ltd. (Delhi) Legal EntitySkills Required
- Bachelor's or Master's degree in Data Science, Computer Science, Statistics, Mathematics, Economics, Engineering, or related quantitative field
- 2+ years of experience in applied data science, machine learning, NLP, or information extraction
- Proven experience taking a data science or ML solution from problem definition through production launch and ongoing improvement
- Experience analyzing large, complex structured and unstructured datasets, including exploration, preprocessing, feature engineering, sampling, labeling, and dataset construction
- Hands-on experience developing document intelligence or information-extraction solutions using transformers, embeddings, RAG, LLMs, prompt engineering, fine-tuning, or agentic workflows
- Strong understanding of experimental design, statistical reasoning, model evaluation, error analysis, and metrics such as precision, recall, F1, field-level accuracy, confidence, and coverage
- Proficiency in Python and SQL, with experience using pandas, NumPy, scikit-learn, and PyTorch or TensorFlow
- Experience with Hugging Face, LangChain, or comparable NLP and LLM frameworks; ability to write maintainable, testable model and data-processing code
- Familiarity with cloud ML environments, version control, automated testing, model monitoring, containers, or data orchestration tools
- Strong communication and collaboration skills, including explaining model behavior, limitations, trade-offs, and recommendations
- Experience with financial data, document intelligence, or large-scale data collection
What the Team is Saying


Morningstar Compensation & Benefits Highlights
-
Leave & Time Off Breadth — Time-off policies include flexible PTO and a paid sabbatical every four years, often highlighted as a standout perk. Feedback suggests this structure supports strong work–life balance and meaningful breaks.
-
Parental & Family Support — Policies advertise a global minimum of 16 weeks for primary caregivers, up to 8 weeks for secondary caregivers, and at least six weeks of paid caregiving leave. These offerings signal above-average support for family and caregiving needs.
-
Retirement Support — Retirement programs feature employer 401(k) contributions/matching, with some postings citing a 75% match on up to 7% of pay. Feedback suggests these offerings are a strong pillar of the package.
Morningstar Insights

What We Do
We are a global investment research and financial data company with 40-plus offices across North America, Europe, Australia, and Asia. Our products and services are used daily by individual investors, financial advisors, asset managers, retirement plan providers, and institutional investors. We provide data, research, and analysis across managed investment products, publicly listed companies, private capital markets, debt securities, and real-time global market data. The financial system can have real barriers—hidden information, friction that can slow decisions, and forces that can limit transparency and access. We work to remove them, bringing independent research, connected data, and investor-first tools to a system that needs more clarity. The people doing this work span research, technology, design, product, sales, and functional areas. We build many of our products in-house, so the work can connect directly to the tools investors use to make real financial decisions.
Why Work With Us
Morningstar’s missing is to empower investor success. We can only do that if our people feel empowered. That means finding people who think independently, bring a wide range of backgrounds with analytical rigor and genuine intellectual curiosity to the work.
Gallery
Morningstar Teams
Morningstar Offices
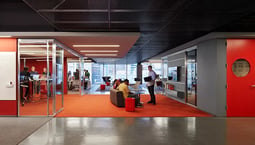
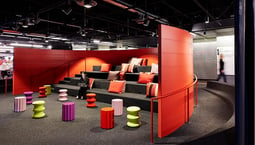
Hybrid Workspace
Employees engage in a combination of remote and on-site work.
Across most of our offices globally, employees work four days a week in the office and one day from home. We recognize that life doesn't always fit a fixed schedule and offer programs that can help provided increased workplace flexibility.


