

Maximum of 25 job preferences reached.
Top Artificial Intelligence DevOps & Platform Engineering Jobs

Artificial Intelligence • Software • Generative AI
Own and maintain infrastructure supporting a high-scale social AI platform, including deployment systems, monitoring, GPU cluster management, and CI/CD. The role requires strong ownership, comfort with ambiguity, and the ability to define infrastructure problems and solutions independently. The engineer will work in person from the company’s Palo Alto office and help ensure reliable, low-downtime operations for a rapidly shipping engineering team.
Top Skills:
Ci/CdDeploymentGpu Cluster ManagementMonitoring
Artificial Intelligence • Cloud • Information Technology • Software
Owns corporate IT strategy, infrastructure, networks, endpoints, SaaS platforms, identity and access management, cybersecurity controls, asset lifecycle, and end-user support. Leads IT operations, projects, documentation, procurement coordination, audit readiness, disaster recovery, and business continuity. Partners cross-functionally to improve reliability, security, compliance, service quality, and cost efficiency while serving as the primary technical escalation point.
Top Skills:
Av SystemsAWSAzureCmmcConfluenceCrowdstrikeEndpoint ManagementFedrampGoogle WorkspaceIdentity And Access ManagementIntuneIso 27001JAMFJIRAJumpcloudMfaMicrosoft 365NetworkingNistOktaSaas PlatformsSentineloneSoc 2Sso

Artificial Intelligence • Greentech • Hardware • Internet of Things • Transportation • Cybersecurity • Automation
Lead the architecture, deployment, and operation of scalable multi-region cloud infrastructure across multiple providers. Build internal developer platforms, automate CI/CD and cloud operations, implement observability, security, reliability, incident response, and FinOps practices. Establish SLOs, optimize costs, manage production incidents, mentor engineering teams, and guide long-term infrastructure roadmaps. The role also supports high-throughput systems, distributed architectures, and potentially geospatial and geo-ML workflows.
Top Skills:
AWSAzureBgpCdnCi/CdDatadogDistributed TracingDnsDockerGCPGrafanaInfrastructure As CodeKubernetesMicroservicesOpentelemetryPrometheusPythonRustServerlessService MeshTerraformTypescriptVpc
Artificial Intelligence • Information Technology • Robotics • Software
Own infrastructure for a fleet of autonomous robots, including networking, remote access, real-time video pipelines, CI, observability, alerting, data storage, and infrastructure costs. Build safe release gates and staged rollout processes for software changes across customer networks. Lead infrastructure initiatives across software engineering, machine learning, and fleet operations teams while ensuring robots remain connected and safe in production environments.
Top Skills:
AlertingCiFleet InfrastructureNetworkingObservabilityReal-Time Video PipelinesRemote AccessRobotics

4 Days AgoSaved
Artificial Intelligence • Machine Learning • Robotics • Generative AI
Own the reliability and scalability of large-scale infrastructure supporting video ingestion, billions of clips, and social features. Responsibilities include on-call leadership, incident response, postmortems, infrastructure-as-code, Elasticsearch operations, GCP and Kubernetes management, database scaling and sharding, CI/CD, and collaboration with engineering teams. The role requires strong judgment during production incidents, durable infrastructure solutions, and experience in rapidly scaling startup environments.
Top Skills:
C#C++CircleCICloud LoggingElasticsearchElectronGCPGithub ActionsIamJavaKotlinKubernetesMySQLPostgresRabbitMQReactRedisReduxSaltStyled ComponentsSwiftTerraformVpc
New
Track Smarter, Apply Better.
Ditch the spreadsheets. Organize your job search with our freeApplication Tracker.
Use For Free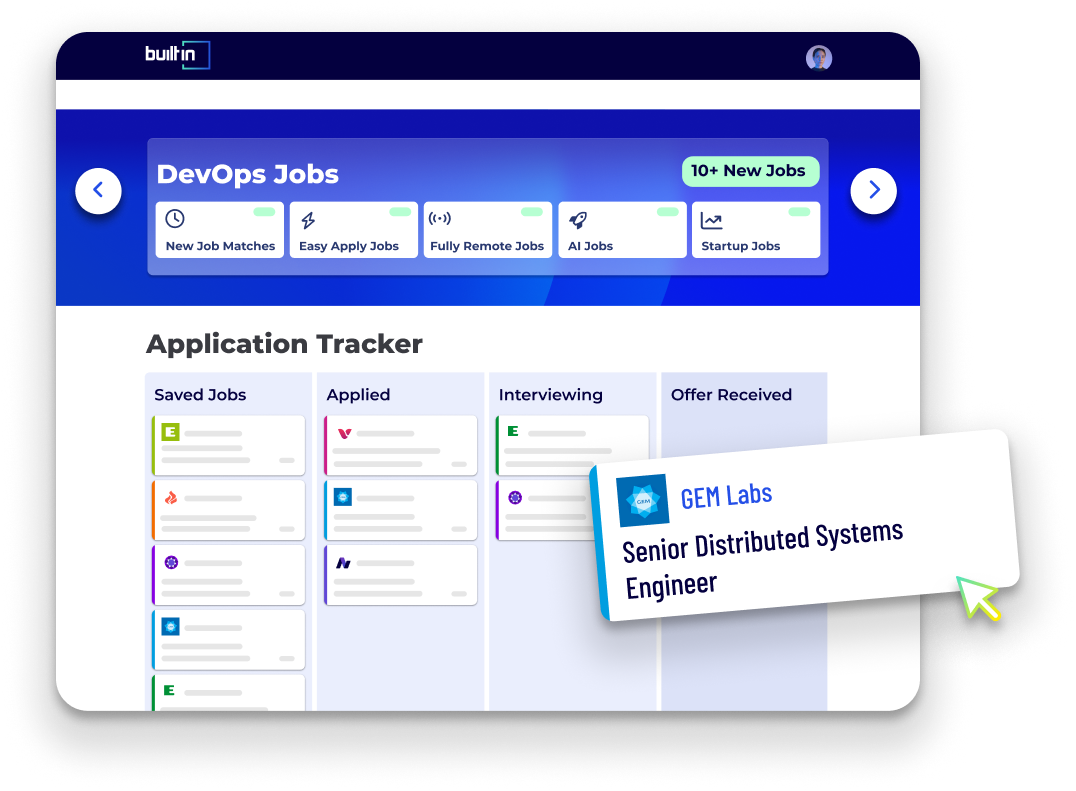
Artificial Intelligence • Big Data • Healthtech • Database • Business Intelligence
Design, build, and manage scalable AWS cloud infrastructure using Terraform and Infrastructure as Code. Own infrastructure projects from design through deployment, troubleshooting, and optimization. Automate provisioning with Python or Bash, maintain CircleCI pipelines, support Docker and Kubernetes environments, optimize cloud costs, and troubleshoot AWS infrastructure, networking, permissions, databases, and deployments in collaboration with engineering teams.
Top Skills:
AWSBashCi/CdCircleCICloud Infrastructure SecurityCloud NetworkingDockerEksEmrIamInfrastructure As CodeKubernetesPythonS3Terraform
Artificial Intelligence • Software
Design and maintain cloud infrastructure on GCP, manage Kubernetes, improve CI/CD pipelines, ensure reliability and security, and support rapid development cycles.
Top Skills:
Ci/CdDatadogGCPGrafanaKubernetesPrometheusTerraform

Artificial Intelligence • Blockchain • Software • Cryptocurrency
Operate and improve large-scale AI compute, storage, and networking infrastructure in 24x7 environments. Responsibilities include capacity planning, performance analysis, patching, upgrades, firmware management, automation, incident response, documentation, disaster recovery testing, and L3 escalation support. The role also requires customer collaboration, operations enablement, and participation in an on-call rotation while supporting OpenStack or similar private cloud platforms.
Top Skills:
Automation ScriptingBgpDatabase TechnologiesInfrastructure As CodeLoad BalancingNsxOpenstackOspfRoutingSoftware-Defined NetworkingSwitchingVlanVxlan

Artificial Intelligence • Automotive • Semiconductor
Build, standardize, and operate compute and software infrastructure for AI and HPC validation labs. Responsibilities include cluster provisioning, Linux images, drivers, Kubernetes or Slurm orchestration, benchmark harnesses, workload libraries, observability, dashboards, incident response, root-cause analysis, and automation. The role partners with architecture and performance teams to mirror customer deployments and support repeatable validation across AI, networking, memory, and DPU use cases.
Top Skills:
AnsibleBeegfsCC++CephCkaGpfsKubernetesLinuxLustreMlperfNemoPythonPytorch DdpPytorch FsdpRocmSlurmTclTerraformWindows

Artificial Intelligence • Cybersecurity
Owns deployment, lifecycle management, and evolution of a multi-prem platform across cloud, bare-metal, air-gapped, and regulated environments. Builds infrastructure-as-code and secure CI/CD pipelines, maintains Kubernetes clusters and observability systems, aligns SaaS and customer-hosted releases, and supports incident response and upgrades. The role also contributes to platform architecture, deployment documentation, compliance workflows, and secure operations across classified and government environments.
Top Skills:
AksArgocdAws GovcloudAzure GovernmentDnsDockerDod SrgEksFedrampFirewallsGithub ActionsGrafanaHelmImage SigningK0SKafkaKubernetesLinuxLokiNist 800-53OpensearchPrometheusSbomService MeshesSlsaTemporalTerraformVpcVpn

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies Hiring Engineering Roles
See All






All Filters
Total selected ()
No Results
No Results
