Storyblok is a headless CMS that enables marketers and developers to create with joy and publish with confidence. It empowers you to deliver structured and consistent content everywhere: websites, apps, AI search, and beyond.
Legendary brands like Virgin Media O2, Oatly, and TomTom use Storyblok to make a bigger, faster market impact.
WHAT IS IN IT FOR YOU
You will be joining a growing company where you can contribute to many “firsts”. Plus these benefits:
- Monthly remote work stipend (home internet costs, electricity). Home office equipment package right at the start (laptop, keyboard, monitor…)
- Home office equipment upgrade (furniture, ear plugs …) or membership to a local co-working space after your onboarding
- Sick leave benefit, parental leave and 25 days of annual leave plus your local national holidays
- Personal development fund for courses, books, conferences, and material
- The annual international team-building trip, quarterly and monthly online get-togethers
- As a fully remote company, with work-life balance at its core, you’ll enjoy flexible schedules
- An international team that loves to have fun at work and works hard together to accomplish shared goals
You will own the reliability, performance, and cost efficiency of the PostgreSQL data platform behind our flagship CMS — primarily Amazon Aurora PostgreSQL — along with the infrastructure and automation around it.
This is a reliability engineering role, not a classic administration one. Aurora takes care of patching, backups, failover, and storage growth; you own what it does not — query and index strategy, plan regressions across major version upgrades, vacuum and bloat, connection management, zero-downtime schema change, logical replication, and capacity and cost modeling. Alongside this, you work as a full member of the Infrastructure team on Terraform, CI/CD, observability, and security tooling, and you share the on-call rotation.
You will work in a shared-ownership model: backend teams own their queries and schemas, and you own the platform, guardrails, tooling, and knowledge-sharing that make their decisions safe. You will collaborate closely with backend engineers, DevOps engineers, Security, product owners, and the Data team.
We measure success by the reliability and predictable performance of the data platform, the quality of your incident response, and how well other engineering teams are equipped to make sound database decisions without you in the room.
ESSENTIAL JOB FUNCTIONSDatabase platform (approx. 60%)
- Own the reliability, performance, and scalability of our PostgreSQL platform (primarily Amazon Aurora): query and index strategy, execution plans, configuration tuning, and capacity planning, with particular attention to hot multi-tenant read paths.
- Lead zero-downtime version upgrades and schema migrations at scale, including diagnosing and preventing plan regressions across Aurora major versions.
- Own the operational health of the platform: vacuum strategy and bloat, long-running transactions and wraparound risk, connection management and pooling (including RDS Proxy), lock contention, and logical replication and slot hygiene.
- Review schema changes and DDL from backend teams for lock behavior, migration safety, and performance impact, and build the guardrails and tooling that make safe changes to the default path.
- Own backup, restore, and disaster recovery end-to-end, including rehearsed restore drills and the access, encryption, and auditing controls our compliance obligations require.
- Model database capacity and cost (I/O-Optimized vs. Standard, Serverless v2 sizing, read replica strategy) and drive cost-efficiency without compromising reliability.
- Deliver infrastructure and automation as a full member of the Infrastructure team, using Terraform and cloud-native tooling on AWS, and contribute to CI/CD pipelines including the safe automated handling of database changes.
- Build and maintain monitoring, alerting, and observability for database and platform systems (e.g. pg_stat_statements, Prometheus exporters, Grafana, Datadog, OpenTelemetry) so problems surface before customers feel them.
- Use cloud security and vulnerability management tooling (such as Aikido) to triage findings and keep the team's services compliant.
- Take part in the on-call rotation, incident response, and postmortems, driving root cause analysis and remediation that prevents recurrence.
- Raise the database competence of the wider engineering organization through design reviews, documentation and runbooks, and mentoring — so this expertise is not concentrated in one person.
- Demonstrate AI literacy, leveraging AI tools to enhance productivity, decision-making, and quality of work while applying sound judgment and critical thinking.
- 7+ years in database engineering, database reliability, infrastructure, or SRE roles, including significant hands-on ownership of production PostgreSQL.
- Deep PostgreSQL expertise: internals and MVCC, reading and acting on EXPLAIN (ANALYZE, BUFFERS), indexing strategy, vacuum behavior, locking, connection pooling, and configuration tuning.
- Strong experience with Amazon Aurora PostgreSQL and AWS-managed database services.
- Proven track record of zero-downtime upgrades and complex schema migrations on large, busy tables.
- Hands-on experience with physical and logical replication, partitioning, read scaling, and designing and validating backup and disaster-recovery strategies.
- Solid experience with Infrastructure-as-Code, primarily Terraform, on AWS.
- Strong Linux fundamentals plus fluency in at least one scripting language (Bash, Python, Ruby, or Go) for automation and tooling.
- Experience with monitoring and observability tooling, and a solid grasp of security practices (IAM, secrets management, network segmentation).
- Experience with change, incident, and problem management in production, and with Git and modern CI/CD workflows applied to database changes.
- Strong written and verbal communication in a remote-first organization, including the ability to explain database trade-offs to backend engineers and non-specialists.
- Willingness and ability to participate in an on-call rotation.
- Bachelor's or Master's degree in Computer Science or a related field, or equivalent practical experience.
- Familiarity with backend frameworks that interact with PostgreSQL (Ruby on Rails preferred; Python, Rust, or Elixir valued).
- Experience with caching layers (Redis, Memcached) and their interaction with database load.
- Exposure to analytics pipelines and warehousing (Redshift, Snowflake, ClickHouse) or CDC-based data flows.
- Experience with container platforms (ECS, EKS, Fargate), NoSQL or vector databases, or AWS certification (Database – Specialty, DevOps Engineer – Professional).
MENTAL, PHYSICAL AND ENVIRONMENTAL REQUIREMENTS
Remote (home) work opportunity or funded by Storyblok co-working space
GENERAL TERMS
Storyblok has a commitment to diversity and inclusion. We strive to create a hiring environment in which all people feel they are equally respected and valued, irrespective of gender identity or expression, sexual orientation, ethnicity, age, religion, citizenship or any other characteristic. You can find more information about our privacy policy here.
All communications regarding job opportunities at Storyblok will come from an official Storyblok employee with an email address ending in @storyblok.com. We will never redirect you to another portal or another site that is unrelated to our domain (storyblok.com).
Here is a sneak peek of Storyblok’s Visual Editor
If you need an accommodation for any part of the application process, please email [email protected]
Skills Required
- 7+ years of experience in database engineering, database reliability, infrastructure, or SRE roles
- Significant hands-on ownership of production PostgreSQL
- Deep PostgreSQL expertise, including MVCC, EXPLAIN ANALYZE BUFFERS, indexing, vacuum, locking, connection pooling, and configuration tuning
- Strong experience with Amazon Aurora PostgreSQL and AWS-managed database services
- Experience leading zero-downtime upgrades and complex schema migrations on large, busy tables
- Hands-on experience with physical and logical replication, partitioning, read scaling, backups, and disaster recovery
- Experience with Infrastructure-as-Code, primarily Terraform, on AWS
- Strong Linux fundamentals
- Fluency in at least one scripting language: Bash, Python, Ruby, or Go
- Experience with monitoring and observability tooling
- Understanding of IAM, secrets management, network segmentation, and security practices
- Experience with change, incident, and problem management in production
- Experience with Git and modern CI/CD workflows applied to database changes
- Strong written and verbal communication skills in a remote-first organization
- Willingness and ability to participate in an on-call rotation
- Bachelor’s or Master’s degree in Computer Science or a related field, or equivalent practical experience
- Familiarity with backend frameworks, preferably Ruby on Rails; Python, Rust, or Elixir valued
- Experience with Redis or Memcached caching layers
- Exposure to Redshift, Snowflake, ClickHouse, analytics pipelines, warehousing, or CDC data flows
- Experience with ECS, EKS, Fargate, NoSQL databases, or vector databases
- AWS certification, such as Database Specialty or DevOps Engineer Professional
Storyblok Compensation & Benefits Highlights
The following summarizes recurring compensation and benefits themes identified from responses generated by popular LLMs to common candidate questions about Storyblok and has not been reviewed or approved by Storyblok.
-
Leave & Time Off Breadth — Paid annual leave of 25 days plus local public holidays, alongside sick and parental leave, signals broad time‑off support. Flexible policies such as special leave and occasional sabbaticals further expand coverage.
-
Healthcare Strength — Health, dental, vision, disability, and life insurance are provided, complemented by mental health benefits and an Employee Assistance Program. Wellness programs and events add to the overall health support.
-
Flexible Benefits — A fully remote setup with flexible start/finish times is supported by home‑office equipment, monthly allowances, and sponsored co‑working options. Regular team offsites and online gatherings round out lifestyle‑oriented perks.
Storyblok Insights

What We Do
Storyblok is a headless content management system (CMS) designed to help businesses and developers manage digital content for websites, apps, and other digital experiences. The term "headless" means that Storyblok separates content management from the presentation layer, allowing developers to have more flexibility and control over how content is displayed.
Why Work With Us
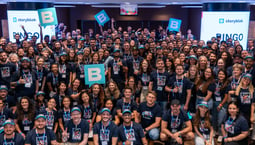
We’re all made up of different backgrounds, and experiences from around the world. Our Storyblok team consists of a pro moto racer, music anthropologist, marine biologist, running fans, snow bunnies, ex-cabin crew on super-jumbo jets, a Boca Junior football fan, and more!
Gallery